目录控制流

第 5 章 控制流Chapter 5 Control flows

条件语句、循环等控制流是计算机编程不可或缺的组成部分,因为它们使我们能够表达复杂的程序。因此,一个自然的问题是:这些构造能否被纳入可微程序?这正是本章的研究内容。Control flows, such as conditionals or loops, are an essential part of computer programming, as they allow us to express complex programs. It is therefore natural to ask whether these constructs can be included in a differentiable program. This is what we study in this chapter.

5.1 比较运算符5.1 Comparison operators

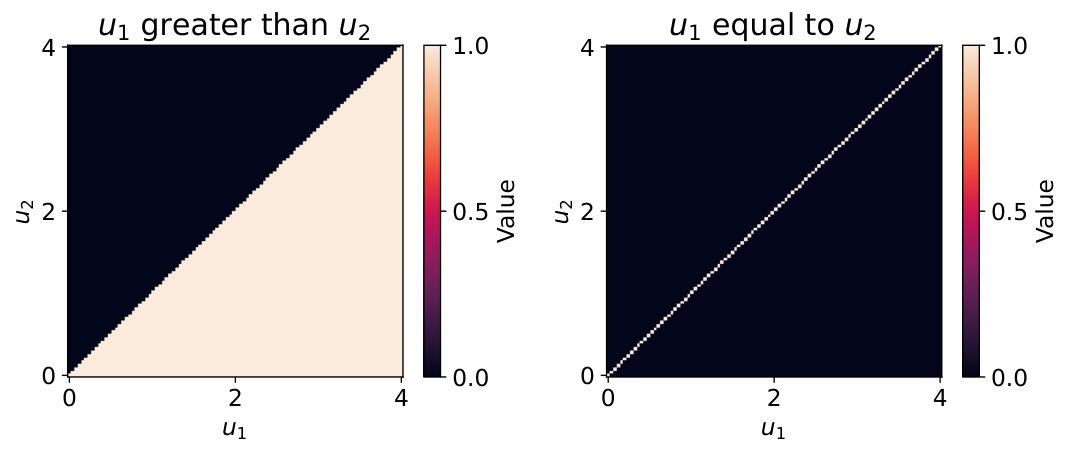
控制流依赖于比较运算符,又称关系运算符。形式上,我们可以将比较运算符 π=op(u1,u2)\pi=\mathrm{op}(u_{1},u_{2}) 定义为从 u1∈Ru_{1}\in\mathbb{R} 和 u2∈Ru_{2}\in\mathbb{R} 到 π∈{0,1}\pi\in\{0,1\} 的函数。所得的二值(布尔)输出 π\pi 随后可用于条件语句(见 5.6 节、5.7 节),以决定执行哪一个分支。我们定义以下运算符,如图 5.1 所示:Control flows rely on comparison operators, a.k.a. relational operators. Formally, we can define a comparison operator π=op(u1,u2)\pi=\mathrm{op}(u_{1},u_{2}) as a function from u1∈Ru_{1}\in\mathbb{R} and u2∈Ru_{2}\in\mathbb{R} to π∈{0,1}\pi\in\{0,1\}. The binary (Boolean) output π\pi can then be used within a conditional statement (see Section 5.6, Section 5.7) to decide whether to execute one branch or another. We define the following operators, illustrated in Fig. 5.1:

  • •

    大于:greater than:

    gt(u1,u2)\displaystyle\mathrm{gt}(u_{1},u_{2}) :={1 if u1≥u20 otherwise \displaystyle\coloneqq\begin{cases}1&\text{ if }u_{1}\geq u_{2}\\ 0&\text{ otherwise }\end{cases}
    =step(u1−u2)\displaystyle=\mathrm{step}(u_{1}-u_{2})
  • •

    小于:less than:

    lt(u1,u2)\displaystyle\mathrm{lt}(u_{1},u_{2}) :={1 if u1≤u20 otherwise \displaystyle\coloneqq\begin{cases}1&\text{ if }u_{1}\leq u_{2}\\ 0&\text{ otherwise }\end{cases}
    =step(u2−u1)\displaystyle=\mathrm{step}(u_{2}-u_{1})
  • •

    等于:equal:

    eq(u1,u2)\displaystyle\mathrm{eq}(u_{1},u_{2}) :={1 if ∣u1−u2∣=00 otherwise \displaystyle\coloneqq\begin{cases}1&\text{ if }|u_{1}-u_{2}|=0\\ 0&\text{ otherwise }\end{cases}
    =gt(u2,u1)⋅gt(u1,u2)\displaystyle=\mathrm{gt}(u_{2},u_{1})\cdot\mathrm{gt}(u_{1},u_{2})
    =step(u2−u1)⋅step(u1−u2)\displaystyle=\mathrm{step}(u_{2}-u_{1})\cdot\mathrm{step}(u_{1}-u_{2})
  • •

    不等于:not equal:

    neq(u1,u2)\displaystyle\mathrm{neq}(u_{1},u_{2}) :={1 if ∣u1−u2∣>00 otherwise \displaystyle\coloneqq\begin{cases}1&\text{ if }|u_{1}-u_{2}|>0\\ 0&\text{ otherwise }\end{cases}
    =1−eq(u1,u2)\displaystyle=1-\mathrm{eq}(u_{1},u_{2})
    =1−step(u2−u1)⋅step(u1−u2),\displaystyle=1-\mathrm{step}(u_{2}-u_{1})\cdot\mathrm{step}(u_{1}-u_{2}),

其中 step ⁣:R→{0,1}\mathrm{step}\colon\mathbb{R}\to\{0,1\} 为 Heaviside 阶跃函数where step ⁣:R→{0,1}\mathrm{step}\colon\mathbb{R}\to\{0,1\} is the Heaviside step function

step(u):={1 if u≥00 otherwise.\mathrm{step}(u)\coloneqq\begin{cases}1&\text{ if }u\geq 0\\ 0&\text{ otherwise}\end{cases}.

Heaviside 阶跃函数是分段常值函数。在 u=0u=0 处,该函数不连续;在 u≠0u\neq 0 处,它连续且导数为零。由于上述比较运算符均以 step\mathrm{step} 函数表达,它们都连续且几乎处处可微,且导数恒为零。因此,尽管它们的导数几乎处处良定义,却不携带任何信息,反而会阻碍梯度反向传播。The Heaviside step function is piecewise constant. At u=0u=0, the function is discontinuous. At u≠0u\neq 0, it is continuous and has null derivative. Since the comparison operators we presented are all expressed in terms of the step\mathrm{step} function, they are all continuous and differentiable almost everywhere, with null derivative. Therefore, while their derivatives are well-defined almost everywhere, they are uninformative and prevent gradient backpropagation.
Refer to caption
Refer to caption
图 5.1:大于、等于运算符均为不连续函数,会得到非黑即白的图像。可以用 Heaviside 阶跃函数的适当近似来对其进行平滑。Figure 5.1: The greater than and equal to operators are discontinuous functions, leading to black or white pictures. They can be smoothed with appropriate approximations of the Heaviside step function.

5.2 软不等式运算符5.2 Soft inequality operators

5.2.1 启发式定义Heuristic definition

为得到不等式运算符的连续松弛,我们可以启发式地将“大于”和“小于”表达式中的阶跃函数替换为 sigmoid 函数 sigmoidσ\mathrm{sigmoid}_{\sigma},其中 σ>0\sigma>0 为缩放参数。该 sigmoid 函数应满足以下性质:To obtain a continuous relaxation of inequality operators, we can heuristically replace the step function in the expression of “greater than” and “less than” by a sigmoid function sigmoidσ\mathrm{sigmoid}_{\sigma}, where σ>0\sigma>0 is a scaling parameter. Such a sigmoid function should satisfy the following properties:

  • •

    sigmoidσ(−u)=1−sigmoidσ(u)\mathrm{sigmoid}_{\sigma}(-u)=1-\mathrm{sigmoid}_{\sigma}(u),

  • •

    lim⁡u→∞sigmoidσ(u)=1\lim_{u\to\infty}\mathrm{sigmoid}_{\sigma}(u)=1,

  • •

    lim⁡u→−∞sigmoidσ(u)=0\lim_{u\to-\infty}\mathrm{sigmoid}_{\sigma}(u)=0,

  • •

    sigmoidσ(0)=12\mathrm{sigmoid}_{\sigma}(0)=\frac{1}{2}.

满足上述性质的两个 sigmoid 函数例子是 logistic 函数(标准 logistic 分布的 CDF)Two examples of sigmoids satisfying the aforementioned properties are the logistic function (the CDF of the standard logistic distribution)

sigmoidσ(u):=logisticσ(u):=11+e−u/σ∈(0,1)\mathrm{sigmoid}_{\sigma}(u)\coloneqq\mathrm{logistic}_{\sigma}(u)\coloneqq\frac{1}{1+e^{-u/\sigma}}\in(0,1)

以及标准高斯分布的 CDF,其定义见式 3.1,and the standard Gaussian’s CDF, defined in Eq. 3.1,

sigmoidσ(u):=Φ(u/σ).\mathrm{sigmoid}_{\sigma}(u)\coloneqq\Phi(u/\sigma).

于是,我们可以定义软“大于”We may then define the soft “greater than”

gt(μ1,μ2)\displaystyle\mathrm{gt}(\mu_{1},\mu_{2}) =step(μ1−μ2)\displaystyle=\mathrm{step}(\mu_{1}-\mu_{2})
≈sigmoidσ(μ1−μ2)\displaystyle\approx\mathrm{sigmoid}_{\sigma}(\mu_{1}-\mu_{2})
=:gtσ(μ1,μ2)\displaystyle\eqqcolon\mathrm{gt}_{\sigma}(\mu_{1},\mu_{2})

以及软“小于”运算符and the soft “less than”

lt(μ1,μ2)\displaystyle\mathrm{lt}(\mu_{1},\mu_{2}) =step(μ2−μ1)\displaystyle=\mathrm{step}(\mu_{2}-\mu_{1})
≈sigmoidσ(μ2−μ1)\displaystyle\approx\mathrm{sigmoid}_{\sigma}(\mu_{2}-\mu_{1})
=:ltσ(μ1,μ2)\displaystyle\eqqcolon\mathrm{lt}_{\sigma}(\mu_{1},\mu_{2})
=1−sigmoidσ(μ1−μ2)\displaystyle=1-\mathrm{sigmoid}_{\sigma}(\mu_{1}-\mu_{2})
=1−gtσ(μ1,μ2).\displaystyle=1-\mathrm{gt}_{\sigma}(\mu_{1},\mu_{2}).

在极限情形下,当 μ1−μ2→∞\mu_{1}-\mu_{2}\to\infty 时,有 sigmoidσ(μ1−μ2)→1\mathrm{sigmoid}_{\sigma}(\mu_{1}-\mu_{2})\to 1。可见,在极限情形下,若 μ1\mu_{1} 与 μ2\mu_{2} 相距无穷远,则 sigmoidσ\mathrm{sigmoid}_{\sigma} 输出的值为 11。除 logistic 函数与标准高斯分布的 CDF 之外,也可以采用其他 S 形函数,13.6 节对此已有讨论。特别地,对于稀疏 S 形函数,存在一个有限值 τ\tau,使得 μ1−μ2≥τ⟹sigmoidσ(μ1−μ2)=1\mu_{1}-\mu_{2}\geq\tau\Longrightarrow\mathrm{sigmoid}_{\sigma}(\mu_{1}-\mu_{2})=1。In the limit, we have that sigmoidσ(μ1−μ2)→1\mathrm{sigmoid}_{\sigma}(\mu_{1}-\mu_{2})\to 1 when μ1−μ2→∞\mu_{1}-\mu_{2}\to\infty. In the limit, sigmoidσ\mathrm{sigmoid}_{\sigma} therefore outputs a value of 11 if μ1\mu_{1} and μ2\mu_{2} are infinitely apart. Besides the logistic function and the standard Gaussian’s CDF, other sigmoid functions are possible, as discussed in Section 13.6. In particular, with sparse sigmoids, there exists a finite value τ\tau such that μ1−μ2≥τ⟹sigmoidσ(μ1−μ2)=1\mu_{1}-\mu_{2}\geq\tau\Longrightarrow\mathrm{sigmoid}_{\sigma}(\mu_{1}-\mu_{2})=1.

5.2.2 随机过程视角Stochastic process perspective

当用于替换阶跃函数的 S 形函数为 logistic 函数或标准高斯分布的 CDF 时,我们便能以更形式化的视角,重新审视前面关于 gtσ(μ1,μ2)\mathrm{gt}_{\sigma}(\mu_{1},\mu_{2}) 与 ltσ(μ1,μ2)\mathrm{lt}_{\sigma}(\mu_{1},\mu_{2}) 的启发式定义。事实上,对于实数值 μ1∈R\mu_{1}\in\mathbb{R} 与 μ2∈R\mu_{2}\in\mathbb{R},我们可以为其关联随机变量When the sigmoid used to replace the step function is the logistic function or the standard Gaussian’s CDF, we can revisit the previous heuristic definition of gtσ(μ1,μ2)\mathrm{gt}_{\sigma}(\mu_{1},\mu_{2}) and ltσ(μ1,μ2)\mathrm{lt}_{\sigma}(\mu_{1},\mu_{2}) from a more formal perspective. Indeed, to real values μ1∈R\mu_{1}\in\mathbb{R} and μ2∈R\mu_{2}\in\mathbb{R}, we can associate random variables

U1∼pμ1,σ1andU2∼pμ2,σ2,U_{1}\sim p_{\mu_{1},\sigma_{1}}\quad\text{and}\quad U_{2}\sim p_{\mu_{2},\sigma_{2}},

从而构成一个随机过程(这里假定 σ1\sigma_{1} 与 σ2\sigma_{2} 固定)。也可以将其写成thereby forming a stochastic process (we assume that σ1\sigma_{1} and σ2\sigma_{2} are fixed). Alternatively, we can also write

(U1,U2)∼pμ1,σ1⊗pμ2,σ2,(U_{1},U_{2})\sim p_{\mu_{1},\sigma_{1}}\otimes p_{\mu_{2},\sigma_{2}},

其中,对两个分布 p1p_{1} 与 p2p_{2},记 p1⊗p2p_{1}\otimes p_{2} 为它们的外积 (p1⊗p2)(u1,u2):=p1(u1)p2(u2)(p_{1}\otimes p_{2})(u_{1},u_{2})\coloneqq p_{1}(u_{1})p_{2}(u_{2})。于是可定义where for two distributions p1p_{1} and p2p_{2}, we denote by p1⊗p2p_{1}\otimes p_{2} their outer product (p1⊗p2)(u1,u2):=p1(u1)p2(u2)(p_{1}\otimes p_{2})(u_{1},u_{2})\coloneqq p_{1}(u_{1})p_{2}(u_{2}). We can then define

gtσ(μ1,μ2)\displaystyle\mathrm{gt}_{\sigma}(\mu_{1},\mu_{2}) =E[gt(U1,U2)]\displaystyle=\mathbb{E}\left[\mathrm{gt}(U_{1},U_{2})\right]
=E[step(U1−U2)]\displaystyle=\mathbb{E}\left[\mathrm{step}(U_{1}-U_{2})\right]
=P(U1−U2≥0)\displaystyle=\mathbb{P}(U_{1}-U_{2}\geq 0)
=P(U2−U1≤0)\displaystyle=\mathbb{P}(U_{2}-U_{1}\leq 0)
=FU2−U1(0),\displaystyle=F_{U_{2}-U_{1}}(0),

其中 FXF_{X} 为随机变量 XX 的累积分布函数(CDF),而 σ\sigma 是 σ1\sigma_{1} 与 σ2\sigma_{2} 的函数。类似地可得where FXF_{X} is the cumulative distribution function (CDF) of the random variable XX, and σ\sigma is a function of σ1\sigma_{1} and σ2\sigma_{2}. Similarly, we obtain

ltσ(μ1,μ2)\displaystyle\mathrm{lt}_{\sigma}(\mu_{1},\mu_{2}) =E[lt(U1,U2)]\displaystyle=\mathbb{E}\left[\mathrm{lt}(U_{1},U_{2})\right]
=E[step(U2−U1)]\displaystyle=\mathbb{E}\left[\mathrm{step}(U_{2}-U_{1})\right]
=P(U1−U2≤0)\displaystyle=\mathbb{P}(U_{1}-U_{2}\leq 0)
=FU1−U2(0).\displaystyle=F_{U_{1}-U_{2}}(0).

由此可见,软不等式运算符基于 U1U_{1} 与 U2U_{2} 之差的 CDF。We see that the soft inequality operators are based on the CDF of the difference between U1U_{1} and U2U_{2}.

对于位置—尺度族分布(12.4.1 节),从扰动的角度,我们也可以定义噪声变量 Z1∼p0,1Z_{1}\sim p_{0,1} 与 Z2∼p0,1Z_{2}\sim p_{0,1},使得 U1=μ1+σ1Z1U_{1}=\mu_{1}+\sigma_{1}Z_{1} 与 U2=μ2+σ2Z2U_{2}=\mu_{2}+\sigma_{2}Z_{2}(12.4.1 节)。于是有For location-scale family distributions (Section 12.4.1), from a perturbation perspective, we can also define noise variables Z1∼p0,1Z_{1}\sim p_{0,1} and Z2∼p0,1Z_{2}\sim p_{0,1} such that U1=μ1+σ1Z1U_{1}=\mu_{1}+\sigma_{1}Z_{1} and U2=μ2+σ2Z2U_{2}=\mu_{2}+\sigma_{2}Z_{2} (Section 12.4.1). We then have

gtσ(μ1,μ2)\displaystyle\mathrm{gt}_{\sigma}(\mu_{1},\mu_{2}) =E[gt(μ1+σ1Z1,μ2+σ2Z2)]\displaystyle=\mathbb{E}\left[\mathrm{gt}(\mu_{1}+\sigma_{1}Z_{1},\mu_{2}+\sigma_{2}Z_{2})\right]
ltσ(μ1,μ2)\displaystyle\mathrm{lt}_{\sigma}(\mu_{1},\mu_{2}) =E[lt(μ1+σ1Z1,μ2+σ2Z2)].\displaystyle=\mathbb{E}\left[\mathrm{lt}(\mu_{1}+\sigma_{1}Z_{1},\mu_{2}+\sigma_{2}Z_{2})\right].

高斯情形Gaussian case

当 U1∼Normal(μ1,σ12)U_{1}\sim\mathrm{Normal}(\mu_{1},\sigma_{1}^{2}) 与 U2∼Normal(μ2,σ22)U_{2}\sim\mathrm{Normal}(\mu_{2},\sigma_{2}^{2}) 时,有When U1∼Normal(μ1,σ12)U_{1}\sim\mathrm{Normal}(\mu_{1},\sigma_{1}^{2}) and U2∼Normal(μ2,σ22)U_{2}\sim\mathrm{Normal}(\mu_{2},\sigma_{2}^{2}), we have

U1−U2∼Normal(μ1−μ2,σ12+σ22).U_{1}-U_{2}\sim\mathrm{Normal}(\mu_{1}-\mu_{2},\sigma_{1}^{2}+\sigma_{2}^{2}). (5.1)

记 Φ\Phi 为标准高斯分布的 CDF,于是得到Denoting Φ\Phi the standard Gaussian’s CDF, we then obtain

gtσ(μ1,μ2)\displaystyle\mathrm{gt}_{\sigma}(\mu_{1},\mu_{2}) =FU2−U1(0)\displaystyle=F_{U_{2}-U_{1}}(0)
=Φ(0−(μ2−μ1)σ)\displaystyle=\Phi\left(\frac{0-(\mu_{2}-\mu_{1})}{\sigma}\right)
=Φ(μ1−μ2σ)\displaystyle=\Phi\left(\frac{\mu_{1}-\mu_{2}}{\sigma}\right)
ltσ(μ1,μ2)\displaystyle\mathrm{lt}_{\sigma}(\mu_{1},\mu_{2}) =FU1−U2(0)\displaystyle=F_{U_{1}-U_{2}}(0)
=Φ(0−(μ1−μ2)σ)\displaystyle=\Phi\left(\frac{0-(\mu_{1}-\mu_{2})}{\sigma}\right)
=Φ(μ2−μ1σ),\displaystyle=\Phi\left(\frac{\mu_{2}-\mu_{1}}{\sigma}\right),

其中 σ:=σ12+σ22\sigma\coloneqq\sqrt{\sigma_{1}^{2}+\sigma_{2}^{2}}。对于 Z1Z_{1} 与 Z2Z_{2},相应的分布为高斯噪声。where σ:=σ12+σ22\sigma\coloneqq\sqrt{\sigma_{1}^{2}+\sigma_{2}^{2}}. The corresponding distribution for Z1Z_{1} and Z2Z_{2} is Gaussian noise.

logistic 情形Logistic case

当 U1∼Gumbel(μ1,σ)U_{1}\sim\mathrm{Gumbel}(\mu_{1},\sigma) 与 U2∼Gumbel(μ2,σ)U_{2}\sim\mathrm{Gumbel}(\mu_{2},\sigma) 时,有When U1∼Gumbel(μ1,σ)U_{1}\sim\mathrm{Gumbel}(\mu_{1},\sigma) and U2∼Gumbel(μ2,σ)U_{2}\sim\mathrm{Gumbel}(\mu_{2},\sigma), we have

U1−U2∼Logistic(μ1−μ2,σ).U_{1}-U_{2}\sim\mathrm{Logistic}(\mu_{1}-\mu_{2},\sigma). (5.2)

于是得到(另见命题 14.5.3)We then obtain (see also Proposition 14.5.3)

gtσ(μ1,μ2)\displaystyle\mathrm{gt}_{\sigma}(\mu_{1},\mu_{2}) =logistic(μ1−μ2σ)\displaystyle=\mathrm{logistic}\left(\frac{\mu_{1}-\mu_{2}}{\sigma}\right)
ltσ(μ1,μ2)\displaystyle\mathrm{lt}_{\sigma}(\mu_{1},\mu_{2}) =logistic(μ2−μ1σ).\displaystyle=\mathrm{logistic}\left(\frac{\mu_{2}-\mu_{1}}{\sigma}\right).

对于 Z1Z_{1} 与 Z2Z_{2},相应的分布为 Gumbel 噪声。The corresponding distribution for Z1Z_{1} and Z2Z_{2} is Gumbel noise.

恢复硬不等式运算符Recovering hard inequality operators

通过下式即可轻松恢复“硬”不等式运算符We easily recover the “hard” inequality operator by

gt(μ1,μ2)=E[gt(U1,U2)],\mathrm{gt}(\mu_{1},\mu_{2})=\mathbb{E}\left[\mathrm{gt}(U_{1},U_{2})\right],

其中 Ui∼δμiU_{i}\sim\delta_{\mu_{i}},且 δμi\delta_{\mu_{i}} 为 delta 分布,它将概率 11 赋予 μi\mu_{i}。where Ui∼δμiU_{i}\sim\delta_{\mu_{i}} and where δμi\delta_{\mu_{i}} is the delta distribution that assigns a probability of 11 to μi\mu_{i}.

5.3 软相等运算符5.3 Soft equality operators

5.3.1 启发式定义Heuristic definition

相等运算符 eq(μ1,μ2)\mathrm{eq}(\mu_{1},\mu_{2}) 可视为数值之间一种极端的相似度函数,其输出只能是 00 或 11。因此,若要定义软相等运算符,一个自然的思路便是用更一般的相似度函数取代相等运算符。相似度函数应在 μ1=μ2\mu_{1}=\mu_{2} 处取得最大值,并随 μ1\mu_{1} 与 μ2\mu_{2} 相互远离而递减。核函数便是一类常见的相似度函数。简言之,核 k(μ1,μ2)k(\mu_{1},\mu_{2}) 可看作内积The equality operator eq(μ1,μ2)\mathrm{eq}(\mu_{1},\mu_{2}) can be seen as an extreme kind of similarity function between numbers, that can only output the values 00 or 11. To define soft equality operators, a natural idea is therefore to replace the equality operator by a more general similarity function. A similarity function should achieve its maximum at μ1=μ2\mu_{1}=\mu_{2} and it should decrease as μ1\mu_{1} and μ2\mu_{2} move apart. A common family of similarity functions are kernels. Briefly, a kernel k(μ1,μ2)k(\mu_{1},\mu_{2}) can be seen as the inner product

k(μ1,μ2):=⟨ϕ(μ1),ϕ(μ2)⟩k(\mu_{1},\mu_{2})\coloneqq\langle\phi(\mu_{1}),\phi(\mu_{2})\rangle

在某个(可能是无穷维的)空间 H\mathcal{H} 中,μ1\mu_{1} 与 μ2\mu_{2} 的嵌入 ϕ(μ1)\phi(\mu_{1}) 与 ϕ(μ2)\phi(\mu_{2}) 之间的内积(确切地说,该空间是再生核希尔伯特空间);关于核的深入综述参见 [178, 185]。为得到 00 与 11 之间近似于相等运算符的相似度度量,我们可以做归一化处理,得到between the embeddings ϕ(μ1)\phi(\mu_{1}) and ϕ(μ2)\phi(\mu_{2}) of μ1\mu_{1} and μ2\mu_{2} in some (potentially infinite-dimensional) space H\mathcal{H}, a reproducing kernel Hilbert space to be precise; see [178, 185] for an in-depth review of kernels. To obtain a similarity measure between 00 and 11 approximating the equality operator, we can normalize to obtain

eq(μ1,μ2)\displaystyle\mathrm{eq}(\mu_{1},\mu_{2}) ≈k(μ1,μ2)k(μ1,μ1)k(μ2,μ2)\displaystyle\approx\frac{k(\mu_{1},\mu_{2})}{\sqrt{k(\mu_{1},\mu_{1})k(\mu_{2},\mu_{2})}}
=⟨ϕ(μ1),ϕ(μ2)⟩∥ϕ(μ1)∥∥ϕ(μ2)∥,\displaystyle=\frac{\langle\phi(\mu_{1}),\phi(\mu_{2})\rangle}{\|\phi(\mu_{1})\|\|\phi(\mu_{2})\|},

其中 ∥ϕ(μ)∥:=⟨ϕ(μ),ϕ(μ)⟩=κ(μ,μ)\|\phi(\mu)\|\coloneqq\sqrt{\langle\phi(\mu),\phi(\mu)\rangle}=\sqrt{\kappa(\mu,\mu)}。这便是 ϕ(μ1)\phi(\mu_{1}) 与 ϕ(μ2)\phi(\mu_{2}) 之间的余弦相似度。where ∥ϕ(μ)∥:=⟨ϕ(μ),ϕ(μ)⟩=κ(μ,μ)\|\phi(\mu)\|\coloneqq\sqrt{\langle\phi(\mu),\phi(\mu)\rangle}=\sqrt{\kappa(\mu,\mu)}. This is the cosine similarity between ϕ(μ1)\phi(\mu_{1}) and ϕ(μ2)\phi(\mu_{2}).

一类特殊的核是各向同性核,其形式为A particular kind of kernel is isotropic kernels of the form

k(μ1,μ2):=κ(μ1−μ2),k(\mu_{1},\mu_{2})\coloneqq\kappa(\mu_{1}-\mu_{2}),

其取值只取决于输入之间的差。当核带有尺度参数 σ>0\sigma>0 时,我们将其记作 κσ\kappa_{\sigma}。据此,可将软相等运算符定义为that depend only on the difference between inputs. When the kernel has a scale parameter σ>0\sigma>0, we use the notation κσ\kappa_{\sigma}. We can then define a soft equality operator as

eq(μ1,μ2)≈eqσ(μ1,μ2):=κσ(μ1−μ2)κσ(0).\displaystyle\mathrm{eq}(\mu_{1},\mu_{2})\approx\mathrm{eq}_{\sigma}(\mu_{1},\mu_{2})\coloneqq\frac{\kappa_{\sigma}(\mu_{1}-\mu_{2})}{\kappa_{\sigma}(0)}.

各向同性核有多种可选,例如高斯核Several isotropic kernels can be chosen such as the Gaussian kernel

κσ(t):=exp⁡(−t22σ2)\kappa_{\sigma}(t)\coloneqq\exp\left(-\frac{t^{2}}{2\sigma^{2}}\right)

或 logistic 核or the logistic kernel

κσ(t):=sech2(t2σ),\kappa_{\sigma}(t)\coloneqq\mathrm{sech}^{2}\left(\frac{t}{2\sigma}\right),

其中我们定义了双曲正割where we defined the hyperbolic secant

sech(u):=2/(exp⁡(u)+exp⁡(−u)).\mathrm{sech}(u)\coloneqq 2/(\exp(u)+\exp(-u)).

正如其名称所示,这些核可从概率视角自然导出,下文将对此加以介绍。As their names suggest, these kernels arise naturally from a probabilistic perspective, that we present below.

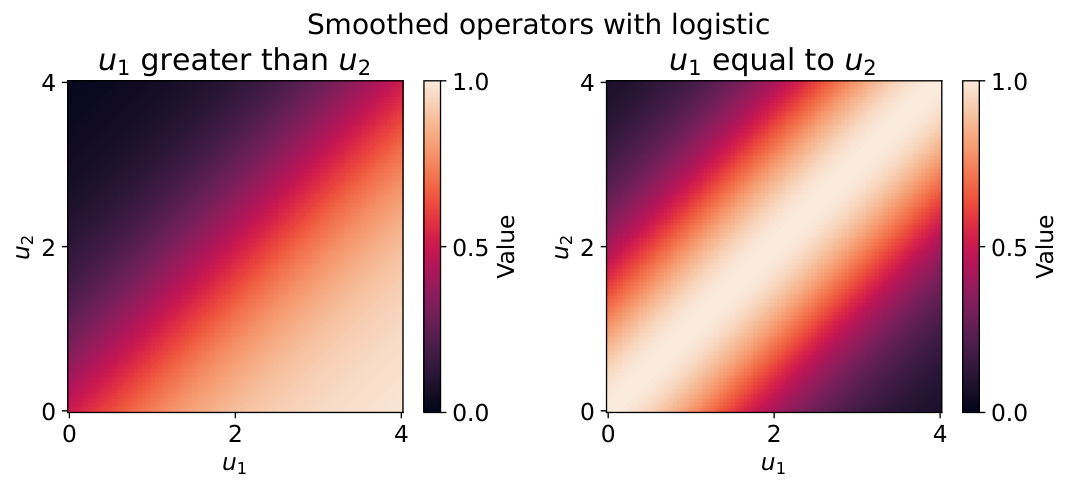
图 5.2 给出了用这些核得到的软相等运算符。直观地说,我们将位于 μ1=μ2\mu_{1}=\mu_{2} 处的一根竖条替换成了一个隆起函数。用 logistic 核得到的软相等运算符,与 [153] 以另一种方式得到的表达式(见其式 9)相吻合。The soft equality operators obtained with these kernels are illustrated in Fig. 5.2. Intuitively, we replaced a bar located at μ1=μ2\mu_{1}=\mu_{2} with a bump function. The soft equality operator obtained with the logistic kernel coincides with the expression [153] arrive at (see their Eq. 9), in a different manner.
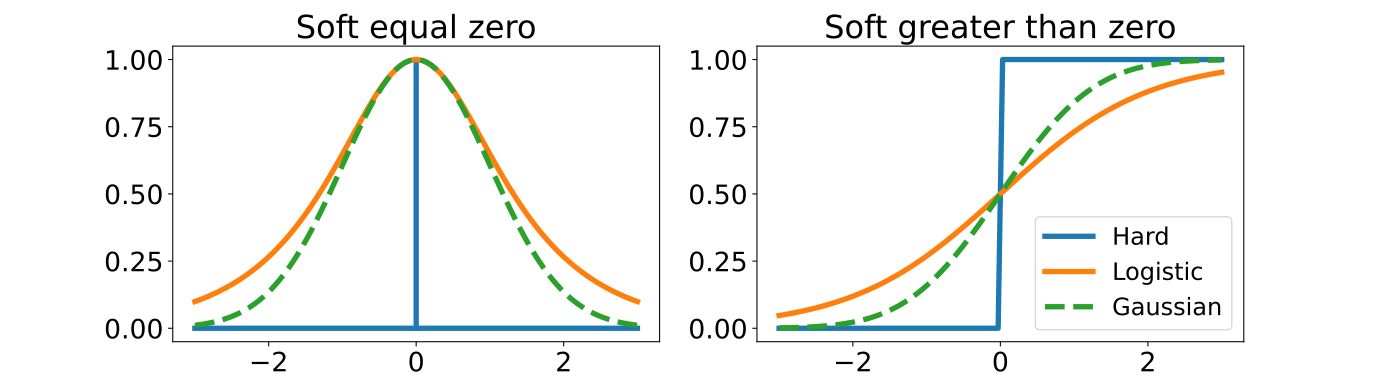
图 5.2:软相等运算符与软大于运算符可分别定义为归一化的核(PDF)与 CDF 函数。Figure 5.2: Soft equality and soft greater than operators can be defined as normalized kernels (PDF) and as CDF functions, respectively.

5.3.2 随机过程视角Stochastic process perspective

我们再次采用随机过程视角,在此视角下将随机变量关联起来We again adopt the stochastic process perspective, in which we associate random variables

U1∼pμ1,σandU2∼pμ2,σU_{1}\sim p_{\mu_{1},\sigma}\quad\text{and}\quad U_{2}\sim p_{\mu_{2},\sigma}

与实数值 μ1∈R\mu_{1}\in\mathbb{R} 和 μ2∈R\mu_{2}\in\mathbb{R} 相关联。然而,要处理相等运算符,我们不能简单地使用 eq(U1,U2)\mathrm{eq}(U_{1},U_{2}) 的期望,因为to real values μ1∈R\mu_{1}\in\mathbb{R} and μ2∈R\mu_{2}\in\mathbb{R}. However, to handle the equality operator, we cannot simply use the expectation of eq(U1,U2)\mathrm{eq}(U_{1},U_{2}) since

E[eq(U1,U2)]=P(U1=U2)=0,\mathbb{E}[\mathrm{eq}(U_{1},U_{2})]=\mathbb{P}(U_{1}=U_{2})=0,

设 U1U_{1} 与 U2U_{2} 为相互独立的连续变量。尽管我们不能直接使用 U1=U2U_{1}=U_{2} 的概率,也不能等价地使用 U1−U2=0U_{1}-U_{2}=0 的概率,但仍可考虑采用 U1−U2U_{1}-U_{2} 的概率密度函数(PDF)fU1−U2f_{U_{1}-U_{2}},并取其于 00 处的值。为确保该函数在 00 处取得最大值 11,可对该 PDF 加以归一化,从而定义U1U_{1} and U2U_{2} being independent continuous variables. While we cannot use the probability of U1=U2U_{1}=U_{2}, or equivalently of U1−U2=0U_{1}-U_{2}=0, we can consider using the probability density function (PDF) fU1−U2f_{U_{1}-U_{2}} of U1−U2U_{1}-U_{2} evaluated at 00. To ensure that the maximum is achieved at 00 with value 11, we can normalize the PDF to define

eqσ(μ1,μ2)=fU1−U2(0)fU0(0),\mathrm{eq}_{\sigma}(\mu_{1},\mu_{2})=\frac{f_{U_{1}-U_{2}}(0)}{f_{U_{0}}(0)},

其中 U0∼p0,σU_{0}\sim p_{0,\sigma}(此处假设 fU0f_{U_{0}} 在 00 处取得最大值)。众所周知,两个随机变量之和的 PDF 即为二者各自 PDF 的卷积。由此可得where U0∼p0,σU_{0}\sim p_{0,\sigma} (we assume that fU0f_{U_{0}} attains its maximum at 00). It is well-known that the PDF of the sum of two random variables is the convolution of their respective PDFs. We therefore have

fU1−U2(t)\displaystyle f_{U_{1}-U_{2}}(t) =(fU1∗f−U2)(t)\displaystyle=(f_{U_{1}}\ast f_{-U_{2}})(t)
=∫−∞∞fU1(τ)f−U2(t−τ)dτ.\displaystyle=\int_{-\infty}^{\infty}f_{U_{1}}(\tau)f_{-U_{2}}(t-\tau)d\tau.

特别地,当 t=0t=0 时,若 fXf_{X} 为服从位置—尺度族分布的随机变量的 PDF,则可得In particular, with t=0t=0, if fXf_{X} is the PDF of a location-scale family distributed random variable, we obtain

fU1−U2(0)\displaystyle f_{U_{1}-U_{2}}(0) =(fU1∗f−U2)(0)\displaystyle=(f_{U_{1}}\ast f_{-U_{2}})(0)
=∫−∞∞fU1(τ)f−U2(−τ)dτ\displaystyle=\int_{-\infty}^{\infty}f_{U_{1}}(\tau)f_{-U_{2}}(-\tau)d\tau
=∫−∞∞fU1(τ)fU2(τ)dτ\displaystyle=\int_{-\infty}^{\infty}f_{U_{1}}(\tau)f_{U_{2}}(\tau)d\tau
:=⟨fU1,fU2⟩\displaystyle\coloneqq\langle f_{U_{1}},f_{U_{2}}\rangle
:=κ(μ1,μ2).\displaystyle\coloneqq\kappa(\mu_{1},\mu_{2}).

我们确实得到了一个内积,因而也就得到了一个核函数。We indeed recover an inner product and therefore a kernel.

绝对差的 CDF 与 PDFCDF and PDF of absolute difference

虽然 P(U1=U2)=0\mathbb{P}(U_{1}=U_{2})=0,但我们也可以改用 P(∣U1−U2∣≤ε)=F∣U1−U2∣(ε)\mathbb{P}(|U_{1}-U_{2}|\leq\varepsilon)=F_{|U_{1}-U_{2}|}(\varepsilon) 作为软相等的一种替代刻画。对任意随机变量 XX,均有While P(U1=U2)=0\mathbb{P}(U_{1}=U_{2})=0, we can also consider using P(∣U1−U2∣≤ε)=F∣U1−U2∣(ε)\mathbb{P}(|U_{1}-U_{2}|\leq\varepsilon)=F_{|U_{1}-U_{2}|}(\varepsilon) as an alternative notion of soft equality. For any random variable XX, we have

F∣X∣(x)\displaystyle F_{|X|}(x) =P(∣X∣≤x)\displaystyle=\mathbb{P}(|X|\leq x)
=P(−x≤X≤x)\displaystyle=\mathbb{P}(-x\leq X\leq x)
=P(X≤x)−P(X≤−x)\displaystyle=\mathbb{P}(X\leq x)-\mathbb{P}(X\leq-x)
=FX(x)−FX(−x).\displaystyle=F_{X}(x)-F_{X}(-x).

因此,Therefore,

P(∣U1−U2∣≤ε)=FU1−U2(ε)−FU1−U2(−ε).\mathbb{P}(|U_{1}-U_{2}|\leq\varepsilon)=F_{U_{1}-U_{2}}(\varepsilon)-F_{U_{1}-U_{2}}(-\varepsilon).

据此,还可推出 ∣X∣|X| 的 PDF 为We can also derive the PDF of ∣X∣|X| as

f∣X∣(x)\displaystyle f_{|X|}(x) =FX′(x)−FX′(−x)\displaystyle=F^{\prime}_{X}(x)-F^{\prime}_{X}(-x)
=fX(x)+fX(−x)\displaystyle=f_{X}(x)+f_{X}(-x)

特别地and in particular

f∣X∣(0)=2fX(0).f_{|X|}(0)=2f_{X}(0).

因此Therefore

f∣U1−U2∣(0)=2fU1−U2(0),f_{|U_{1}-U_{2}|}(0)=2f_{U_{1}-U_{2}}(0),

这也进一步说明,取 U1−U2U_{1}-U_{2} 的 PDF 在 00 处的值是合理的。当 XX 服从正态分布时,∣X∣|X| 服从所谓的折叠正态分布。further justifying using the PDF of U1−U2U_{1}-U_{2} evaluated at 00. When XX follows a normal distribution, ∣X∣|X| follows the so-called folded normal distribution.

高斯情形Gaussian case

当 U1∼Normal(μ1,σ12)U_{1}\sim\mathrm{Normal}(\mu_{1},\sigma_{1}^{2})、U2∼Normal(μ2,σ22)U_{2}\sim\mathrm{Normal}(\mu_{2},\sigma_{2}^{2}) 时,由式 5.1 可得When U1∼Normal(μ1,σ12)U_{1}\sim\mathrm{Normal}(\mu_{1},\sigma_{1}^{2}) and U2∼Normal(μ2,σ22)U_{2}\sim\mathrm{Normal}(\mu_{2},\sigma_{2}^{2}), we obtain from Eq. 5.1

fU1−U2(t)=12πexp⁡(−(t−(μ1−μ2))22(σ12+σ22))f_{U_{1}-U_{2}}(t)=\frac{1}{\sqrt{2\pi}}\exp\left(-\frac{(t-(\mu_{1}-\mu_{2}))^{2}}{2(\sigma_{1}^{2}+\sigma_{2}^{2})}\right)

从而so that

eqσ(μ1,μ2)=exp⁡(−(μ1−μ2)22(σ12+σ22))∈[0,1].\mathrm{eq}_{\sigma}(\mu_{1},\mu_{2})=\exp\left(-\frac{(\mu_{1}-\mu_{2})^{2}}{2(\sigma_{1}^{2}+\sigma_{2}^{2})}\right)\in[0,1].

我们确实得到了 κσ(μ1−μ2)/κσ(0)\kappa_{\sigma}(\mu_{1}-\mu_{2})/\kappa_{\sigma}(0),其中 κσ\kappa_{\sigma} 为高斯核,σ=σ12+σ22\sigma=\sqrt{\sigma_{1}^{2}+\sigma_{2}^{2}}。至于绝对差的 CDF,则可得We indeed recover κσ(μ1−μ2)/κσ(0)\kappa_{\sigma}(\mu_{1}-\mu_{2})/\kappa_{\sigma}(0), where κσ\kappa_{\sigma} is the Gaussian kernel with σ=σ12+σ22\sigma=\sqrt{\sigma_{1}^{2}+\sigma_{2}^{2}}. For the CDF of the absolute difference, we obtain

P(∣U1−U2∣≤ε)=Φ(ε−(μ1−μ2)σ)−Φ(−ε−(μ1−μ2)σ).\mathbb{P}(|U_{1}-U_{2}|\leq\varepsilon)=\Phi\left(\frac{\varepsilon-(\mu_{1}-\mu_{2})}{\sigma}\right)-\Phi\left(\frac{-\varepsilon-(\mu_{1}-\mu_{2})}{\sigma}\right).

logistic 情形Logistic case

当 U1∼Gumbel(μ1,σ)U_{1}\sim\mathrm{Gumbel}(\mu_{1},\sigma)、U2∼Gumbel(μ2,σ)U_{2}\sim\mathrm{Gumbel}(\mu_{2},\sigma) 时,回顾When U1∼Gumbel(μ1,σ)U_{1}\sim\mathrm{Gumbel}(\mu_{1},\sigma) and U2∼Gumbel(μ2,σ)U_{2}\sim\mathrm{Gumbel}(\mu_{2},\sigma), recalling that

sech(u):=2/(exp⁡(u)+exp⁡(−u)),\mathrm{sech}(u)\coloneqq 2/(\exp(u)+\exp(-u)),

由式 5.2 可得we obtain from Eq. 5.2

fU1−U2(t)=14σsech2(t−(μ1−μ2)2σ)f_{U_{1}-U_{2}}(t)=\frac{1}{4\sigma}\mathrm{sech}^{2}\left(\frac{t-(\mu_{1}-\mu_{2})}{2\sigma}\right)

从而so that

eqσ(μ1,μ2)=sech2(μ1−μ22σ)∈[0,1].\mathrm{eq}_{\sigma}(\mu_{1},\mu_{2})=\mathrm{sech}^{2}\left(\frac{\mu_{1}-\mu_{2}}{2\sigma}\right)\in[0,1].

我们确实得到了 κσ(μ1−μ2)/κσ(0)\kappa_{\sigma}(\mu_{1}-\mu_{2})/\kappa_{\sigma}(0),其中 κσ\kappa_{\sigma} 为 logistic 核,σ=σ1=σ2\sigma=\sigma_{1}=\sigma_{2}。We indeed recover κσ(μ1−μ2)/κσ(0)\kappa_{\sigma}(\mu_{1}-\mu_{2})/\kappa_{\sigma}(0), where κσ\kappa_{\sigma} is the logistic kernel with σ=σ1=σ2\sigma=\sigma_{1}=\sigma_{2}.

5.3.3 高斯过程视角Gaussian process perspective

前一种方法是将 μ1\mu_{1} 和 μ2\mu_{2} 映射为两个相互独立的随机变量 U1∼pμ1,σ1U_{1}\sim p_{\mu_{1},\sigma_{1}} 和 U2∼pμ2,σ2U_{2}\sim p_{\mu_{2},\sigma_{2}}(这里假定 σ1\sigma_{1} 和 σ2\sigma_{2} 固定不变)。我们也可以换一种做法:将 μ1\mu_{1} 和 μ2\mu_{2} 映射为两个彼此相依的随机变量 U1U_{1} 和 U2U_{2},其协方差取决于 μ1\mu_{1} 与 μ2\mu_{2} 之间的相似度。借助高斯过程[95],即可实现这一做法。The previous approach relied on mapping μ1\mu_{1} and μ2\mu_{2} to two independent random variables U1∼pμ1,σ1U_{1}\sim p_{\mu_{1},\sigma_{1}} and U2∼pμ2,σ2U_{2}\sim p_{\mu_{2},\sigma_{2}} (we assume that σ1\sigma_{1} and σ2\sigma_{2} are fixed). Instead, we can consider mapping μ1\mu_{1} and μ2\mu_{2} to two dependent random variables U1U_{1} and U2U_{2}, whose covariance depends on the similarity between μ1\mu_{1} and μ2\mu_{2}. We can do so by using a Gaussian process [95].

R\mathbb{R} 上的高斯过程,是以 μ∈R\mu\in\mathbb{R} 为索引的随机过程 {Uμ:μ∈R}\{U_{\mu}:\mu\in\mathbb{R}\}:对任意一组与 (μ1,…,μK)∈RK(\mu_{1},\ldots,\mu_{K})\in\mathbb{R}^{K} 相对应的 KK 个随机变量 (Uμ1,…,UμK)(U_{\mu_{1}},\dots,U_{\mu_{K}}),它们都构成多元高斯随机变量。高斯过程由均值函数 μ↦E[Uμ]\mu\mapsto\mathbb{E}[U_{\mu}] 与协方差函数 (μi,μj)↦Cov⁡(Uμi,Uμj)(\mu_{i},\mu_{j})\mapsto\operatorname{Cov}(U_{\mu_{i}},U_{\mu_{j}}) 共同刻画。均值函数可直接取 E[Uμ]=μ\mathbb{E}[U_{\mu}]=\mu;协方差函数则须保证高斯过程中任意随机变量组合的方差非负,而核函数恰好满足这一性质。因此可以定义A Gaussian process on R\mathbb{R} is a stochastic process {Uμ:μ∈R}\{U_{\mu}:\mu\in\mathbb{R}\} indexed by μ∈R\mu\in\mathbb{R} such that any subset of KK random variables (Uμ1,…,UμK)(U_{\mu_{1}},\dots,U_{\mu_{K}}) associated with (μ1,…,μK)∈RK(\mu_{1},\ldots,\mu_{K})\in\mathbb{R}^{K} is a multivariate Gaussian random variable. The Gaussian process is characterized by the mean function μ↦E[Uμ]\mu\mapsto\mathbb{E}[U_{\mu}], and its covariance function (μi,μj)↦Cov⁡(Uμi,Uμj)(\mu_{i},\mu_{j})\mapsto\operatorname{Cov}(U_{\mu_{i}},U_{\mu_{j}}). For the mean function, we may simply choose E[Uμ]=μ\mathbb{E}[U_{\mu}]=\mu. For the covariance function, we need to ensure that the variance of any combination of random variables in the Gaussian process is non-negative. This property is satisfied by kernel functions. We can therefore define

Cov⁡(Uμi,Uμj):=k(μi,μj),\operatorname{Cov}(U_{\mu_{i}},U_{\mu_{j}})\coloneqq k(\mu_{i},\mu_{j}),

其中 kk 为某个核函数。有了这种从实数到随机变量的映射,还需给出随机变量之间相似度的度量,一个自然的选择是它们的相关性for some kernel kk. Equipped with such a mapping from real numbers to random variables, we need a measure of similarity between random variables. A natural choice is their correlation

corr(Uμi,Uμj):=Cov⁡(Uμi,Uμj)Var⁡(Uμi)Var⁡(Uμj)∈[−1,1].\mathrm{corr}(U_{\mu_{i}},U_{\mu_{j}})\coloneqq\frac{\operatorname{Cov}(U_{\mu_{i}},U_{\mu_{j}})}{\sqrt{\operatorname{Var}(U_{\mu_{i}})\operatorname{Var}(U_{\mu_{j}})}}\in[-1,1].

于是得到We therefore obtain

corr(Uμi,Uμj)\displaystyle\mathrm{corr}(U_{\mu_{i}},U_{\mu_{j}}) =k(μi,μj)k(μi,μi)k(μj,μj)\displaystyle=\frac{k(\mu_{i},\mu_{j})}{\sqrt{k(\mu_{i},\mu_{i})k(\mu_{j},\mu_{j})}}
=⟨ϕ(μi),ϕ(μj)⟩∥ϕ(μi)∥∥ϕ(μj)∥,\displaystyle=\frac{\langle\phi(\mu_{i}),\phi(\mu_{j})\rangle}{\|\phi(\mu_{i})\|\|\phi(\mu_{j})\|},

这与前文所述的余弦相似度度量一致。特别地,当 K=2K=2 且 kσ(μ1,μ2)=κ(μ1−μ2)k_{\sigma}(\mu_{1},\mu_{2})=\kappa(\mu_{1}-\mu_{2}) 时,便得到先前启发式定义的软相等运算符which coincides with the cosine similarity measure we saw before. In the particular case K=2K=2 and when kσ(μ1,μ2)=κ(μ1−μ2)k_{\sigma}(\mu_{1},\mu_{2})=\kappa(\mu_{1}-\mu_{2}), we then recover the previous heuristically defined soft equality operator

eqσ(μ1,μ2)=corr(Uμ1,Uμ2)=κ(μ1−μ2)κ(0).\mathrm{eq}_{\sigma}(\mu_{1},\mu_{2})=\mathrm{corr}(U_{\mu_{1}},U_{\mu_{2}})=\frac{\kappa(\mu_{1}-\mu_{2})}{\kappa(0)}.

5.4 逻辑运算符5.4 Logical operators

逻辑运算符可用于实施布尔代数运算。形式上,可将其定义为从 {0,1}×{0,1}\{0,1\}\times\{0,1\} 到 {0,1}\{0,1\} 的函数。例如,and(逻辑合取,又称逻辑积)、or(逻辑析取,又称逻辑和)与 not(逻辑否定,又称逻辑补)运算符的定义为Logical operators can be used to perform Boolean algebra. Formally, we can define them as functions from {0,1}×{0,1}\{0,1\}\times\{0,1\} to {0,1}\{0,1\}. The and (logical conjunction a.k.a. logical product), or (logical disjunction a.k.a. logical addition) and not (logical negation a.k.a. logical complement) operators, for example, are defined by

and(π,π′)\displaystyle\mathrm{and}(\pi,\pi^{\prime}) :={1 if π=π′=10 otherwise \displaystyle\coloneqq\begin{cases}1&\text{ if }\pi=\pi^{\prime}=1\\ 0&\text{ otherwise }\end{cases}
or(π,π′)\displaystyle\mathrm{or}(\pi,\pi^{\prime}) :={1 if 1∈{π,π′}0 otherwise \displaystyle\coloneqq\begin{cases}1&\text{ if }1\in\{\pi,\pi^{\prime}\}\\ 0&\text{ otherwise }\end{cases}
not(π)\displaystyle\mathrm{not}(\pi) :={0 if π=11 if π=0.\displaystyle\coloneqq\begin{cases}0&\text{ if }\pi=1\\ 1&\text{ if }\pi=0\end{cases}.

这些运算符的经典性质包括Classical properties of these operators include

  • •

    交换律:Commutativity:

    and(π,π′)=and(π′,π)\displaystyle\mathrm{and}(\pi,\pi^{\prime})=\mathrm{and}(\pi^{\prime},\pi)
    or(π,π′)=or(π′,π)\displaystyle\mathrm{or}(\pi,\pi^{\prime})=\mathrm{or}(\pi^{\prime},\pi)
  • •

    结合律:Associativity:

    and(π,and(π′,π′′))\displaystyle\mathrm{and}(\pi,\mathrm{and}(\pi^{\prime},\pi^{\prime\prime})) =and(and(π,π′),π′′)\displaystyle=\mathrm{and}(\mathrm{and}(\pi,\pi^{\prime}),\pi^{\prime\prime})
    or(π,or(π′,π′′))\displaystyle\mathrm{or}(\pi,\mathrm{or}(\pi^{\prime},\pi^{\prime\prime})) =or(or(π,π′),π′′)\displaystyle=\mathrm{or}(\mathrm{or}(\pi,\pi^{\prime}),\pi^{\prime\prime})
  • •

    and 对 or 的分配律:Distributivity of and over or:

    and(π,or(π′,π′′))=or(and(π,π′),and(π,π′′))\mathrm{and}(\pi,\mathrm{or}(\pi^{\prime},\pi^{\prime\prime}))=\mathrm{or}(\mathrm{and}(\pi,\pi^{\prime}),\mathrm{and}(\pi,\pi^{\prime\prime}))
  • •

    单位元:Neutral element:

    and(π,1)\displaystyle\mathrm{and}(\pi,1) =π\displaystyle=\pi
    or(π,0)\displaystyle\mathrm{or}(\pi,0) =π\displaystyle=\pi
  • •

    De Morgan 定律:De Morgan’s laws:

    not(or(π,π′))\displaystyle\mathrm{not}(\mathrm{or}(\pi,\pi^{\prime})) =and(not(π),not(π′))\displaystyle=\mathrm{and}(\mathrm{not}(\pi),\mathrm{not}(\pi^{\prime}))
    not(and(π,π′))\displaystyle\mathrm{not}(\mathrm{and}(\pi,\pi^{\prime})) =or(not(π),not(π′)).\displaystyle=\mathrm{or}(\mathrm{not}(\pi),\mathrm{not}(\pi^{\prime})).

更一般地,对于二值向量 π=(π1,…,πK)∈{0,1}K{\bm{\pi}}=(\pi_{1},\dots,\pi_{K})\in\{0,1\}^{K},可将 all(全称量化,∀\forall)与 any(存在量化,∃\exists)运算符——即从 {0,1}K\{0,1\}^{K} 到 {0,1}\{0,1\} 的函数——定义为More generally, for a binary vector π=(π1,…,πK)∈{0,1}K{\bm{\pi}}=(\pi_{1},\dots,\pi_{K})\in\{0,1\}^{K}, we can define all (universal quantification, ∀\forall) and any (existential quantification, ∃\exists) operators, which are functions from {0,1}K\{0,1\}^{K} to {0,1}\{0,1\}, as

all(π):={1 if π1=⋯=πK=10 otherwise \mathrm{all}({\bm{\pi}})\coloneqq\begin{cases}1&\text{ if }\pi_{1}=\dots=\pi_{K}=1\\ 0&\text{ otherwise }\end{cases}

以及and

any(π):={1 if 1∈{π1,…,πK}0 otherwise .\mathrm{any}({\bm{\pi}})\coloneqq\begin{cases}1&\text{ if }1\in\{\pi_{1},\dots,\pi_{K}\}\\ 0&\text{ otherwise }\end{cases}.

5.5 逻辑运算符的连续扩展5.5 Continuous extensions of logical operators

5.5.1 概率式连续扩展Probabilistic continuous extension

and、or 与 not 运算符还可等价地写作We can equivalently write the and, or and not operators as

and(π,π′)\displaystyle\mathrm{and}(\pi,\pi^{\prime}) =π⋅π′\displaystyle=\pi\cdot\pi^{\prime}
or(π,π′)\displaystyle\mathrm{or}(\pi,\pi^{\prime}) =π+π′−π⋅π′\displaystyle=\pi+\pi^{\prime}-\pi\cdot\pi^{\prime}
not(π)\displaystyle\mathrm{not}(\pi) =1−π.\displaystyle=1-\pi.

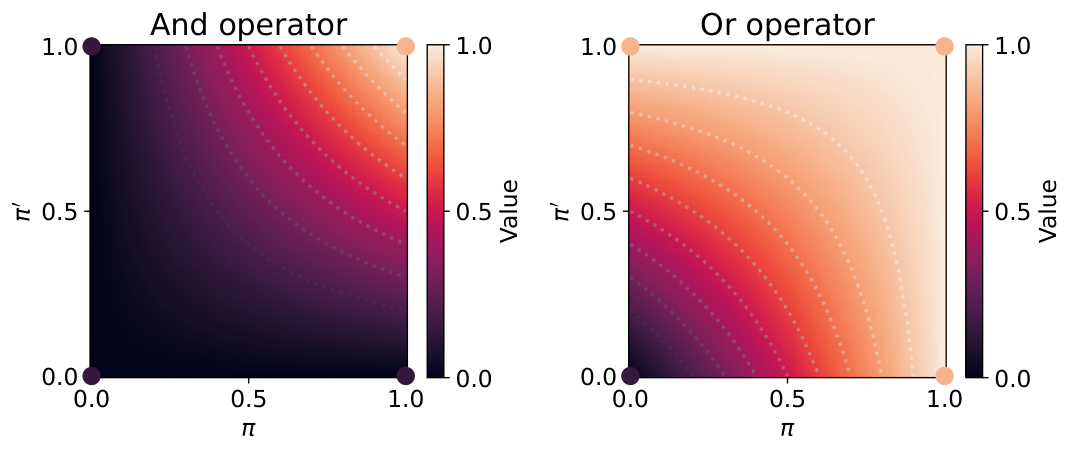
以上定义都是此前那些定义的扩展:可将它们用作定义在 [0,1]×[0,1]→[0,1][0,1]\times[0,1]\to[0,1] 上的函数,如图 5.3 所示。这意味着,借助 5.2 节中定义的软比较运算符,便可得到 π,π′∈[0,1]\pi,\pi^{\prime}\in[0,1]。同理,也可定义 all 与 any 的连续扩展,它们是定义在 [0,1]K[0,1]^{K} 上、取值于 [0,1][0,1] 的函数,即These are extensions of the previous definitions: we can use them as functions from [0,1]×[0,1]→[0,1][0,1]\times[0,1]\to[0,1], as illustrated in Fig. 5.3. This means that we can use the soft comparison operators defined in Section 5.2 to obtain π,π′∈[0,1]\pi,\pi^{\prime}\in[0,1]. Likewise, we can define continuous extensions of all and any, which are functions from [0,1]K[0,1]^{K} to [0,1][0,1], as

all(π)\displaystyle\mathrm{all}({\bm{\pi}}) =∏i=1Kπi\displaystyle=\prod_{i=1}^{K}\pi_{i}
any(π)\displaystyle\mathrm{any}({\bm{\pi}}) =1−∏i=1K(1−πi).\displaystyle=1-\prod_{i=1}^{K}(1-\pi_{i}).
Refer to caption
图 5.3:布尔的 and 与 or 运算符是定义在 {0,1}×{0,1}\{0,1\}\times\{0,1\} 上、取值于 {0,1}\{0,1\} 的函数(即图中的各个角点),而它们的连续扩展 and(π,π′):=π⋅π′\mathrm{and}(\pi,\pi^{\prime})\coloneqq\pi\cdot\pi^{\prime} 与 or(π,π′):=π+π′−π⋅π′\mathrm{or}(\pi,\pi^{\prime})\coloneqq\pi+\pi^{\prime}-\pi\cdot\pi^{\prime} 则定义了从 [0,1]×[0,1][0,1]\times[0,1] 到 [0,1][0,1] 的函数。Figure 5.3: The Boolean and and or operators are functions from {0,1}×{0,1}\{0,1\}\times\{0,1\} to {0,1}\{0,1\} (corners in the figure) but their continuous extensions and(π,π′):=π⋅π′\mathrm{and}(\pi,\pi^{\prime})\coloneqq\pi\cdot\pi^{\prime} as well as or(π,π′):=π+π′−π⋅π′\mathrm{or}(\pi,\pi^{\prime})\coloneqq\pi+\pi^{\prime}-\pi\cdot\pi^{\prime} define a function from [0,1]×[0,1][0,1]\times[0,1] to [0,1][0,1].

从概率的角度看,若令 YY 与 Y′Y^{\prime} 为两个相互独立的随机变量,分别服从参数为 π\pi 与 π′\pi^{\prime} 的 伯努利分布,则From a probabilistic perspective, if we let YY and Y′Y^{\prime} be two independent random variables distributed according to Bernoulli distributions with parameters π\pi and π′\pi^{\prime}, then

and(π,π′)\displaystyle\mathrm{and}(\pi,\pi^{\prime}) =P(Y=1∩Y′=1)=P(Y=1)⋅P(Y′=1)\displaystyle=\mathbb{P}(Y=1\cap Y^{\prime}=1)=\mathbb{P}(Y=1)\cdot\mathbb{P}(Y^{\prime}=1)
or(π,π′)\displaystyle\mathrm{or}(\pi,\pi^{\prime}) =P(Y=1∪Y′=1)\displaystyle=\mathbb{P}(Y=1\cup Y^{\prime}=1)
=P(Y=1)+P(Y′=1)−P(Y=1∩Y′=1)\displaystyle=\mathbb{P}(Y=1)+\mathbb{P}(Y^{\prime}=1)-\mathbb{P}(Y=1\cap Y^{\prime}=1)
=P(Y=1)+P(Y′=1)−P(Y=1)P(Y′=1)\displaystyle=\mathbb{P}(Y=1)+\mathbb{P}(Y^{\prime}=1)-\mathbb{P}(Y=1)\mathbb{P}(Y^{\prime}=1)
not(π)\displaystyle\mathrm{not}(\pi) =P(Y≠1)=1−P(Y=1).\displaystyle=\mathbb{P}(Y\neq 1)=1-\mathbb{P}(Y=1).

在概率论中,这三个式子分别对应两个独立变量的乘积法则、加法法则和补集法则。In probability theory, these correspond to the product rule of two independent variables, the addition rule, and the complement rule.

同理,若令 Y=(Y1,…,YK)∈{0,1}KY=(Y_{1},\dots,Y_{K})\in\{0,1\}^{K} 为服从参数为 π=(π1,…,πK){\bm{\pi}}=(\pi_{1},\dots,\pi_{K}) 的多元 伯努利分布的随机变量,则Likewise, if we let Y=(Y1,…,YK)∈{0,1}KY=(Y_{1},\dots,Y_{K})\in\{0,1\}^{K} be a random variable distributed according to a multivariate Bernoulli distribution with parameters π=(π1,…,πK){\bm{\pi}}=(\pi_{1},\dots,\pi_{K}), then

all(π)\displaystyle\textrm{all}({\bm{\pi}}) =P(Y1=1∩⋯∩YK=1)\displaystyle=\mathbb{P}(Y_{1}=1\cap\dots\cap Y_{K}=1)
=∏i=1KP(Yi=1)\displaystyle=\prod_{i=1}^{K}\mathbb{P}(Y_{i}=1)
any(π)\displaystyle\textrm{any}({\bm{\pi}}) =P(Y1=1∪⋯∪YK=1)\displaystyle=\mathbb{P}(Y_{1}=1\cup\dots\cup Y_{K}=1)
=1−P(¬(Y1=1∪⋯∪YK=1))\displaystyle=1-\mathbb{P}(\neg(Y_{1}=1\cup\dots\cup Y_{K}=1))
=1−P(Y1≠1∩⋯∩YK≠1)\displaystyle=1-\mathbb{P}(Y_{1}\neq 1\cap\dots\cap Y_{K}\neq 1)
=1−∏i=1K(1−P(Yi=1)).\displaystyle=1-\prod_{i=1}^{K}(1-\mathbb{P}(Y_{i}=1)).

以上两式分别是概率的链式法则,以及 KK 个独立变量的概率加法法则。These are the chain rule of probability and the addition rule of probability for KK independent variables.

5.5.2 三角范数与余范数Triangular norms and co-norms

更一般地,模糊逻辑文献 [108, 102] 引入了三角范数与余范数的概念,分别用以给出 and 与 or 运算符的连续松弛。More generally, in the fuzzy logic literature [108, 102], the concepts of triangular norms and co-norms have been introduced to provide continuous relaxations of the and and or operators, respectively.

定义 5.5.1(三角范数与余范数)。Definition 5.5.1 (Triangular norms and conorms).
三角范数,又称 t-范数,是一个从 [0,1]×[0,1][0,1]\times[0,1] 到 [0,1][0,1] 的函数,它满足交换律、结合律与关于 11 的中性元性质,并且是单调的,即对所有的 π≤τ\pi\leq\tau 和 π′≤τ′\pi^{\prime}\leq\tau^{\prime},都有 t(π,π′)≤t(τ,τ′)t(\pi,\pi^{\prime})\leq t(\tau,\tau^{\prime})。三角余范数,又称 t-余范数,定义与之类似,但关于 00 是中性的。A triangular norm, a.k.a. t-norm, is a function from [0,1]×[0,1][0,1]\times[0,1] to [0,1][0,1] which is commutative, associative, neutral w.r.t. 11 and is monotone, meaning that t(π,π′)≤t(τ,τ′)t(\pi,\pi^{\prime})\leq t(\tau,\tau^{\prime}) for all π≤τ\pi\leq\tau and π′≤τ′\pi^{\prime}\leq\tau^{\prime}. A triangular conorm, a.k.a. t-conorm, is defined similarly but is neutral w.r.t. 00.

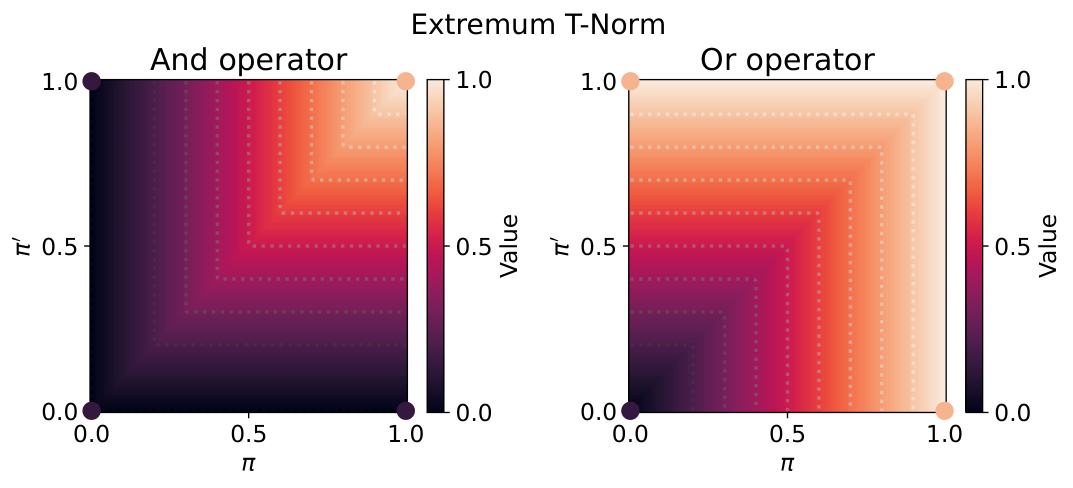
前文给出的 and 与 or 的概率式扩展,正是三角范数与余范数的示例,表 5.1 中还列出了更多例子。借助这些运算符的结合律性质,可将它们推广到向量 π∈[0,1]K{\bm{\pi}}\in[0,1]^{K},从而定义 all 与 any 运算符的连续扩展,如表 5.2 所示。更多示例与分析,例如可参见 [198,第 2 章和第 3 章]。The previously-defined probabilistic extensions of and and or are examples of triangular norms and conorms. More examples are given in Table 5.1. Thanks to the associative property of these operators, we can generalize them to vectors π∈[0,1]K{\bm{\pi}}\in[0,1]^{K} to define continuous extensions of the all and any operators, as shown in Table 5.2. For more examples and analysis, see for instance [198, Chapters 2 and 3].
Refer to caption
Refer to caption
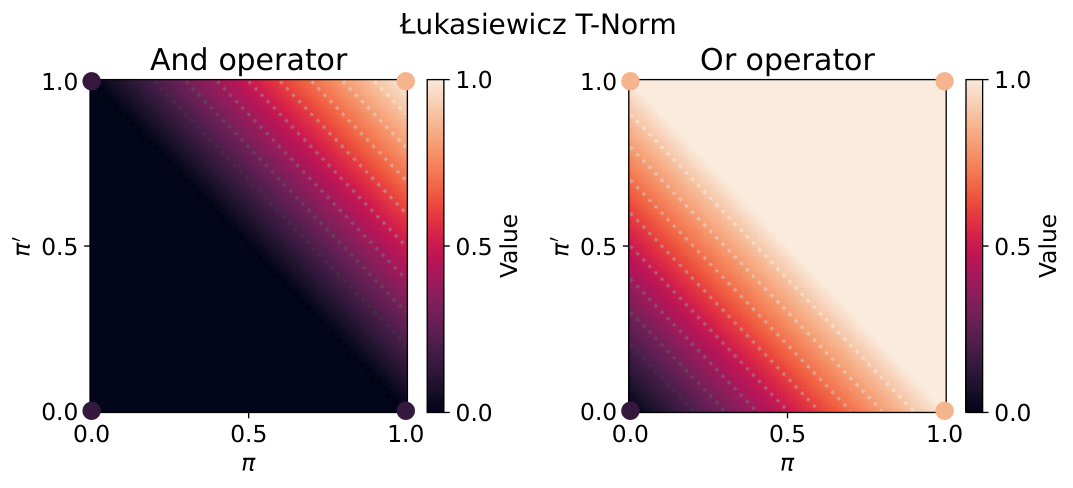
图 5.4:利用三角范数(t-范数)对布尔 and 与 or 运算符所作的其他松弛。Figure 5.4: Alternative relaxations of the Boolean and and or operators using triangular norms (t-norms).
表 5.1:三角范数与余范数的示例,它们分别是 and 与 or 运算符的连续松弛。对 min 与 max 运算符作平滑处理,还可得到更多实例。Table 5.1: Examples of triangular norms and conorms, which are continuous relaxations of the and and or operators, respectively. More instances can be obtained by smoothing out the min and max operators.
t-范数(松弛后的 and)t-norm (relaxed and) t-余范数(松弛后的 or)t-conorm (relaxed or)
概率的Probabilistic π⋅π′\pi\cdot\pi^{\prime} π+π′−π⋅π′\pi+\pi^{\prime}-\pi\cdot\pi^{\prime}
极值Extremum min⁡(π,π′)\min(\pi,\pi^{\prime}) max⁡(π,π′)\max(\pi,\pi^{\prime})
ŁukasiewiczŁukasiewicz max⁡(π+π′−1,0)\max(\pi+\pi^{\prime}-1,0) min⁡(π+π′,1)\min(\pi+\pi^{\prime},1)
表 5.2:all 与 any 运算符的连续扩展。Table 5.2: Continuous extensions of the all and any operators.
All(∀\forall)All (∀\forall) Any(∃\exists)Any (∃\exists)
概率性Probabilistic ∏i=1Kπi\prod_{i=1}^{K}\pi_{i} 1−∏i=1K(1−πi)1-\prod_{i=1}^{K}(1-\pi_{i})
极值Extremum min⁡(π1,…,πK)\min(\pi_{1},\dots,\pi_{K}) max⁡(π1,…,πK)\max(\pi_{1},\dots,\pi_{K})
ŁukasiewiczŁukasiewicz max⁡(∑i=1Kπi−(K−1),0)\max(\sum_{i=1}^{K}\pi_{i}-(K-1),0) min⁡(∑i=1Kπi,1)\min(\sum_{i=1}^{K}\pi_{i},1)

5.6 if-else 语句5.6 If-else statements

if-else 语句依据条件执行不同的代码。形式上,可将 ifelse ⁣:{0,1}×V×V→V\mathrm{ifelse}\colon\{0,1\}\times\mathcal{V}\times\mathcal{V}\to\mathcal{V} 函数定义为An if-else statement executes different code depending on a condition. Formally, we can define the ifelse ⁣:{0,1}×V×V→V\mathrm{ifelse}\colon\{0,1\}\times\mathcal{V}\times\mathcal{V}\to\mathcal{V} function by

ifelse(π,v1,v0)\displaystyle\mathrm{ifelse}(\pi,{\bm{v}}_{1},{\bm{v}}_{0}) :={v1 if π=1v0 if π=0\displaystyle\coloneqq\begin{cases}{\bm{v}}_{1}&\text{ if }\pi=1\\ {\bm{v}}_{0}&\text{ if }\pi=0\end{cases} (5.3)
=π⋅v1+(1−π)⋅v0.\displaystyle=\pi\cdot{\bm{v}}_{1}+(1-\pi)\cdot{\bm{v}}_{0}.

变量 π\pi 称为谓词。它是一个二值(布尔)变量,因此当 π∉{0,1}\pi\not\in\{0,1\} 时,函数 ifelse\mathrm{ifelse} 无定义。于是,该函数关于 π∈{0,1}\pi\in\{0,1\} 既不连续也不可微。另一方面,分别对应假分支与真分支的 v0∈V{\bm{v}}_{0}\in\mathcal{V} 与 v1∈V{\bm{v}}_{1}\in\mathcal{V} 可以是连续变量。若 π=1\pi=1,则函数关于 v1{\bm{v}}_{1} 为线性,关于 v0{\bm{v}}_{0} 为常值。反之,若 π=0\pi=0,则函数关于 v0{\bm{v}}_{0} 为线性,关于 v1{\bm{v}}_{1} 为常值。下面讨论如何对 ifelse\mathrm{ifelse} 求导。The π\pi variable is called the predicate. It is a binary (Boolean) variable, making the function ifelse\mathrm{ifelse} undefined if π∉{0,1}\pi\not\in\{0,1\}. The function is therefore discontinuous and nondifferentiable w.r.t. π∈{0,1}\pi\in\{0,1\}. On the other hand, v0∈V{\bm{v}}_{0}\in\mathcal{V} and v1∈V{\bm{v}}_{1}\in\mathcal{V}, which correspond to the false and true branches, can be continuous variables. If π=1\pi=1, the function is linear w.r.t. v1{\bm{v}}_{1} and constant w.r.t. v0{\bm{v}}_{0}. Conversely, if π=0\pi=0, the function is linear w.r.t. v0{\bm{v}}_{0} and constant w.r.t. v1{\bm{v}}_{1}. We now discuss how to differentiate through ifelse\mathrm{ifelse}.

5.6.1 通过分支变量求导Differentiating through branch variables

当 π∈{0,1}\pi\in\{0,1\} 固定时,ifelse(π,v1,v0)\mathrm{ifelse}(\pi,{\bm{v}}_{1},{\bm{v}}_{0}) 是关于 v1∈V{\bm{v}}_{1}\in\mathcal{V} 与 v0∈V{\bm{v}}_{0}\in\mathcal{V} 的良定义函数,因而可作为计算图中的一个节点使用(8.3 节)。由于它关于 v1{\bm{v}}_{1} 与 v0{\bm{v}}_{0} 具有线性性,可得其关于 v1{\bm{v}}_{1} 与 v0{\bm{v}}_{0} 的雅可比矩阵分别为For π∈{0,1}\pi\in\{0,1\} fixed, ifelse(π,v1,v0)\mathrm{ifelse}(\pi,{\bm{v}}_{1},{\bm{v}}_{0}) is a valid function w.r.t. v1∈V{\bm{v}}_{1}\in\mathcal{V} and v0∈V{\bm{v}}_{0}\in\mathcal{V}, and can therefore be used as a node in a computational graph (Section 8.3). Due to the linearity w.r.t. v1{\bm{v}}_{1} and v0{\bm{v}}_{0}, we obtain that the Jacobians w.r.t. v1{\bm{v}}_{1} and v0{\bm{v}}_{0} are

∂v0ifelse(π,v1,v0)\displaystyle\partial_{{\bm{v}}_{0}}\mathrm{ifelse}(\pi,{\bm{v}}_{1},{\bm{v}}_{0}) :={0 if π=1I if π=0\displaystyle\coloneqq\begin{cases}0&\text{ if }\pi=1\\ I&\text{ if }\pi=0\end{cases}
=(1−π)⋅I\displaystyle=(1-\pi)\cdot I

与and

∂v1ifelse(π,v1,v0)\displaystyle\partial_{{\bm{v}}_{1}}\mathrm{ifelse}(\pi,{\bm{v}}_{1},{\bm{v}}_{0}) :={I if π=10 if π=0\displaystyle\coloneqq\begin{cases}I&\text{ if }\pi=1\\ 0&\text{ if }\pi=0\end{cases}
=π⋅I,\displaystyle=\pi\cdot I,

其中 II 为适当大小的单位矩阵。if-else 语句大多会与其他函数组合使用。设 g1 ⁣:U1→Vg_{1}\colon\mathcal{U}_{1}\to\mathcal{V} 与 g0 ⁣:U0→Vg_{0}\colon\mathcal{U}_{0}\to\mathcal{V} 为可微函数,并定义 v1:=g1(u1){\bm{v}}_{1}\coloneqq g_{1}({\bm{u}}_{1}) 与 v0:=g0(u0){\bm{v}}_{0}\coloneqq g_{0}({\bm{u}}_{0}),其中 u1∈U1{\bm{u}}_{1}\in\mathcal{U}_{1},u0∈U0{\bm{u}}_{0}\in\mathcal{U}_{0}。于是,ifelse\mathrm{ifelse}、g1g_{1} 与 g0g_{0} 的组合即为由下式定义的函数 f ⁣:{0,1}×U1×U0→Vf\colon\{0,1\}\times\mathcal{U}_{1}\times\mathcal{U}_{0}\to\mathcal{V}:where II is the identity matrix of appropriate size. Most of the time, if-else statements are composed with other functions. Let g1 ⁣:U1→Vg_{1}\colon\mathcal{U}_{1}\to\mathcal{V} and g0 ⁣:U0→Vg_{0}\colon\mathcal{U}_{0}\to\mathcal{V} be differentiable functions. We then define v1:=g1(u1){\bm{v}}_{1}\coloneqq g_{1}({\bm{u}}_{1}) and v0:=g0(u0){\bm{v}}_{0}\coloneqq g_{0}({\bm{u}}_{0}), where u1∈U1{\bm{u}}_{1}\in\mathcal{U}_{1} and u0∈U0{\bm{u}}_{0}\in\mathcal{U}_{0}. The composition of ifelse\mathrm{ifelse}, g1g_{1} and g0g_{0} is then the function f ⁣:{0,1}×U1×U0→Vf\colon\{0,1\}\times\mathcal{U}_{1}\times\mathcal{U}_{0}\to\mathcal{V} defined by

f(π,u1,u0)\displaystyle f(\pi,{\bm{u}}_{1},{\bm{u}}_{0}) :=ifelse(π,g1(u1),g0(u0))\displaystyle\coloneqq\mathrm{ifelse}(\pi,g_{1}({\bm{u}}_{1}),g_{0}({\bm{u}}_{0}))
=π⋅g1(u1)+(1−π)⋅g0(u0).\displaystyle=\pi\cdot g_{1}({\bm{u}}_{1})+(1-\pi)\cdot g_{0}({\bm{u}}_{0}).

由此可得其雅可比矩阵为We obtain that the Jacobians are

∂u1f(π,u1,u0)=π⋅∂g1(u1)\partial_{{\bm{u}}_{1}}f(\pi,{\bm{u}}_{1},{\bm{u}}_{0})=\pi\cdot\partial g_{1}({\bm{u}}_{1})

与and

∂u0f(π,u1,u0)=(1−π)⋅∂g0(u0).\partial_{{\bm{u}}_{0}}f(\pi,{\bm{u}}_{1},{\bm{u}}_{0})=(1-\pi)\cdot\partial g_{0}({\bm{u}}_{0}).

只要 g1g_{1} 与 g0g_{0} 是可微函数,我们便可毫无障碍地通过分支变量 u1{\bm{u}}_{1} 与 u0{\bm{u}}_{0} 求导。真正棘手的是谓词变量 π\pi,下面就来讨论这一点。As long as g1g_{1} and g0g_{0} are differentiable functions, we can therefore differentiate through the branch variables u1{\bm{u}}_{1} and u0{\bm{u}}_{0} without any issue. More problematic is the predicate variable π\pi, as we now discuss.

5.6.2 通过谓词变量求导Differentiating through predicate variables

谓词变量 π\pi 是二值的,因而无法直接求导。不过,π\pi 可以是某个比较运算符的输出。例如,假设我们想表达由下式定义的函数 fh ⁣:R×U1×U0→Vf_{h}\colon\mathbb{R}\times\mathcal{U}_{1}\times\mathcal{U}_{0}\to\mathcal{V}:The predicate variable π\pi is binary and therefore cannot be differentiated directly. However, π\pi can be the output of a comparison operator. For example, suppose we want to express the function fh ⁣:R×U1×U0→Vf_{h}\colon\mathbb{R}\times\mathcal{U}_{1}\times\mathcal{U}_{0}\to\mathcal{V} defined by

fh(p,u1,u0):={g1(u1) if p≥0g0(u0) otherwise .f_{h}(p,{\bm{u}}_{1},{\bm{u}}_{0})\coloneqq\begin{cases}g_{1}({\bm{u}}_{1})&\text{ if }p\geq 0\\ g_{0}({\bm{u}}_{0})&\text{ otherwise }\end{cases}.

采用我们的记号,上式可改写为Using our notation, this can be rewritten as

fh(p,u1,u0)\displaystyle f_{h}(p,{\bm{u}}_{1},{\bm{u}}_{0}) :=ifelse(gt(p,0),g1(u1),g0(u0))\displaystyle\coloneqq\mathrm{ifelse}(\mathrm{gt}(p,0),g_{1}({\bm{u}}_{1}),g_{0}({\bm{u}}_{0}))
=ifelse(step(p),g1(u1),g0(u0))\displaystyle=\mathrm{ifelse}(\mathrm{step}(p),g_{1}({\bm{u}}_{1}),g_{0}({\bm{u}}_{0}))
=step(p)g1(u1)+(1−step(p))g0(u0).\displaystyle=\mathrm{step}(p)g_{1}({\bm{u}}_{1})+(1-\mathrm{step}(p))g_{0}({\bm{u}}_{0}).

Heaviside 阶跃函数在 p=0p=0 处不连续,但在所有 p≠0p\neq 0 上连续且可微,导数为 step′(p)=0\mathrm{step}^{\prime}(p)=0。因此,函数 fhf_{h} 关于 p≠0p\neq 0 的导数为零。The Heaviside step function has a discontinuity at p=0p=0, but it is continuous and differentiable with derivative step′(p)=0\mathrm{step}^{\prime}(p)=0 for all p≠0p\neq 0. The function fhf_{h} therefore has null derivative w.r.t. p≠0p\neq 0,

∂pfh(p,u1,u0)\displaystyle\partial_{p}f_{h}(p,{\bm{u}}_{1},{\bm{u}}_{0}) =∂1fh(p,u1,u0)\displaystyle=\partial_{1}f_{h}(p,{\bm{u}}_{1},{\bm{u}}_{0})
=step′(p)(g1(u1)−g0(u0))\displaystyle=\mathrm{step}^{\prime}(p)(g_{1}({\bm{u}}_{1})-g_{0}({\bm{u}}_{0}))
=0.\displaystyle={\mathbf{0}}.

换言之,虽然 fhf_{h} 关于 pp(对于 p≠0p\neq 0)有良定义的导数,但这些导数并不提供有用信息。作为另一个例子,现在我们考虑函数In other words, while fhf_{h} has well-defined derivatives w.r.t. pp for p≠0p\neq 0, the derivatives are uninformative. As another example, let us now consider the function

gh(u1,u0):=fh(t(u1),u1,u0),g_{h}({\bm{u}}_{1},{\bm{u}}_{0})\coloneqq f_{h}(t({\bm{u}}_{1}),{\bm{u}}_{1},{\bm{u}}_{0}),

其中 tt 是某个可微函数。这一次,u1{\bm{u}}_{1} 同时影响谓词与真分支。于是,利用命题 2.3.12 可得for some differentiable function tt. This time, u1{\bm{u}}_{1} influences both the predicate and the true branch. Then, using Proposition 2.3.12, we obtain

∂u1gh(u1,u0)\displaystyle\partial_{{\bm{u}}_{1}}g_{h}({\bm{u}}_{1},{\bm{u}}_{0}) =∂t(u1)∂1fh(t(u1),u1,u0)+∂2fh(t(u1),u1,u0)\displaystyle=\partial t({\bm{u}}_{1})\partial_{1}f_{h}(t({\bm{u}}_{1}),{\bm{u}}_{1},{\bm{u}}_{0})+\partial_{2}f_{h}(t({\bm{u}}_{1}),{\bm{u}}_{1},{\bm{u}}_{0})
=∂2fh(t(u1),u1,u0).\displaystyle=\partial_{2}f_{h}(t({\bm{u}}_{1}),{\bm{u}}_{1},{\bm{u}}_{0}).

换言之,谓词 t(u1)t({\bm{u}}_{1}) 的导数不会影响 ghg_{h} 的导数。In other words, the derivatives of the predicate t(u1)t({\bm{u}}_{1}) do not influence the derivatives of ghg_{h}.

5.6.3 连续松弛Continuous relaxations

幸运的是,我们还记得Fortunately, we recall that

ifelse(π,v1,v0)=π⋅v1+(1−π)⋅v0.\mathrm{ifelse}(\pi,{\bm{v}}_{1},{\bm{v}}_{0})=\pi\cdot{\bm{v}}_{1}+(1-\pi)\cdot{\bm{v}}_{0}.

该函数完全良定义,即使 π∈[0,1]\pi\in[0,1] 取代了 π∈{0,1}\pi\in\{0,1\}。也就是说,该定义将式 5.3 从离散集合 {0,1}\{0,1\} 扩展到连续的单位线段 [0,1][0,1]。我们已经看到This function is perfectly well-defined, even if π∈[0,1]\pi\in[0,1], instead of π∈{0,1}\pi\in\{0,1\}. That is, this definition is an extension of Eq. 5.3 from the discrete set {0,1}\{0,1\} to the continuous unit segment [0,1][0,1]. We saw that

gt(a,b)≈gtσ(a,b):=sigmoidσ(a−b)∈[0,1],\mathrm{gt}(a,b)\approx\mathrm{gt}_{\sigma}(a,b)\coloneqq\mathrm{sigmoid}_{\sigma}(a-b)\in[0,1],

其中我们用 sigmoidσ\mathrm{sigmoid}_{\sigma} 表示一个将 R\mathbb{R} 映射到 [0,1][0,1] 的可微 S 形函数。例如,我们可以使用 logistic 函数或标准高斯分布的 CDF。如果我们现在定义where we use sigmoidσ\mathrm{sigmoid}_{\sigma} to denote a differentiable S-shaped function mapping R\mathbb{R} to [0,1][0,1]. For instance, we can use the logistic function or the standard Gaussian’s CDF. If we now define

fs(p,u1,u0)\displaystyle f_{s}(p,{\bm{u}}_{1},{\bm{u}}_{0}) :=ifelse(gtσ(p,0),g1(u1),g0(u0))\displaystyle\coloneqq\mathrm{ifelse}(\mathrm{gt}_{\sigma}(p,0),g_{1}({\bm{u}}_{1}),g_{0}({\bm{u}}_{0}))
=ifelse(sigmoidσ(p),g1(u1),g0(u0))\displaystyle=\mathrm{ifelse}(\mathrm{sigmoid}_{\sigma}(p),g_{1}({\bm{u}}_{1}),g_{0}({\bm{u}}_{0}))
=sigmoidσ(p)g1(u1)+(1−sigmoidσ(p))g0(u0),\displaystyle=\mathrm{sigmoid}_{\sigma}(p)g_{1}({\bm{u}}_{1})+(1-\mathrm{sigmoid}_{\sigma}(p))g_{0}({\bm{u}}_{0}), (5.4)

则雅可比矩阵变为the Jacobian becomes

∂pfs(p,u1,u0)=sigmoidσ′(p)(g1(u1)−g0(u0)).\partial_{p}f_{s}(p,{\bm{u}}_{1},{\bm{u}}_{0})=\mathrm{sigmoid}^{\prime}_{\sigma}(p)(g_{1}({\bm{u}}_{1})-g_{0}({\bm{u}}_{0})).

若 sigmoidσ=logistic(⋅/σ)\mathrm{sigmoid}_{\sigma}=\mathrm{logistic}(\cdot/\sigma) 或 sigmoidσ=Φ(⋅/σ)\mathrm{sigmoid}_{\sigma}=\Phi(\cdot/\sigma),则雅可比矩阵处处非零,从而使梯度能够通过计算图反向传播。这是第四部分所研究的平滑的一个例子。If sigmoidσ=logistic(⋅/σ)\mathrm{sigmoid}_{\sigma}=\mathrm{logistic}(\cdot/\sigma) or sigmoidσ=Φ(⋅/σ)\mathrm{sigmoid}_{\sigma}=\Phi(\cdot/\sigma), the Jacobian is non-null everywhere, allowing gradients to backpropagate through the computational graph. This is an example of smoothing as studied in Part IV.
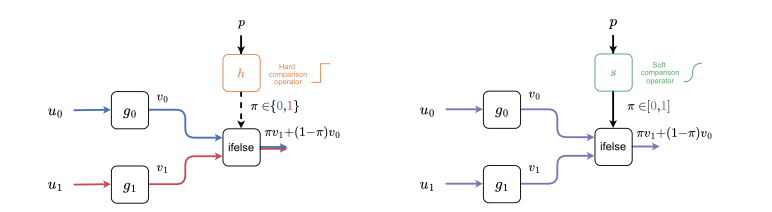
图 5.5:使用带硬比较运算符或软比较运算符的 if-else 语句的程序的计算图。使用硬比较运算符(阶跃函数,左图)时,谓词 π\pi 是离散变量(用虚线表示)。根据谓词 π\pi 的取值(00 或 11),只有一个分支(红色或蓝色)对输出有贡献。可以计算沿连续变量路径(实线)的导数。然而,诸如谓词这样的离散变量会阻止有意义的导数传播。使用软比较运算符(sigmoid,右图)时,谓词是连续变量,因而可以求关于输入 pp 的导数。在这种情况下,两个分支(分别对应 g0g_{0} 与 g1g_{1})都对输出有贡献,因此都需要求值。Figure 5.5: Computation graphs of programs using if-else statements with either hard or soft comparison operators. By using a hard comparison operator (step function, left panel) the predicate π\pi is a discrete variable (represented by a dashed line). Depending on the value (00 or 11) of the predicate π\pi, only one branch (red or blue) contributes to the output. Derivatives along a path of continuous variables (dense lines) can be computed. However, discrete variables such as the predicate prevent the propagation of meaningful derivatives. By using a soft comparison operator (sigmoid, right panel), the predicate is a continuous variable and derivatives with respect to the input pp can be taken. In this case both branches (corresponding to g0g_{0} and g1g_{1}) contribute to the output and therefore need to be evaluated.

概率视角Probabilistic perspective

从概率视角看,我们可以把式 5.4 视为 gi(ui)g_{i}({\bm{u}}_{i}) 的期望,其中 i∈{0,1}i\in\{0,1\} 是一个服从参数为 π=sigmoidσ(p)\pi=\mathrm{sigmoid}_{\sigma}(p) 的 伯努利分布的二值随机变量:From a probabilistic perspective, we can view Eq. 5.4 as the expectation of gi(ui)g_{i}({\bm{u}}_{i}), where i∈{0,1}i\in\{0,1\} is a binary random variable distributed according to a Bernoulli distribution with parameter π=sigmoidσ(p)\pi=\mathrm{sigmoid}_{\sigma}(p):

fs(p,u1,u0)=Ei∼Bernoulli(sigmoidσ(p))[gi(ui)].f_{s}(p,{\bm{u}}_{1},{\bm{u}}_{0})=\mathbb{E}_{i\sim\mathrm{Bernoulli}(\mathrm{sigmoid}_{\sigma}(p))}\left[g_{i}({\bm{u}}_{i})\right].

对两个可能分支取期望,使该函数关于 pp 可微,因为 sigmoidσ(p)\mathrm{sigmoid}_{\sigma}(p) 是可微的。当然,这样做的代价是需要对两个分支都求值,而不是只求值其中一个分支。概率视角还表明,如有需要,我们也可以按下式计算方差:Taking the expectation over the two possibles branches makes the function differentiable with respect to pp, since sigmoidσ(p)\mathrm{sigmoid}_{\sigma}(p) is differentiable. Of course, this comes at the cost of evaluating both branches, instead of a single one. The probabilistic perspective suggests that we can also compute the variance if needed as

Vi∼Bernoulli(sigmoidσ(p))[gi(ui)]\displaystyle\mathbb{V}_{i\sim\mathrm{Bernoulli}(\mathrm{sigmoid}_{\sigma}(p))}\left[g_{i}({\bm{u}}_{i})\right]
=\displaystyle= Ei∼Bernoulli(sigmoidσ(p))[(fs(p,u1,u0)−gi(ui))2].\displaystyle\mathbb{E}_{i\sim\mathrm{Bernoulli}(\mathrm{sigmoid}_{\sigma}(p))}\left[(f_{s}(p,{\bm{u}}_{1},{\bm{u}}_{0})-g_{i}({\bm{u}}_{i}))^{2}\right].

概率视角还提示,可以采用不同的尺度来定义平滑,如图 5.6 所示。The probabilistic viewpoint also suggests different scales at which a smoothing can be defined as illustrated in Fig. 5.6.

另一种视角 [153] 基于 logistic 分布。事实上,若 PP 是服从均值为 pp、尺度为 11 的 logistic 分布的随机变量,则如我们在注 3.3.1 中所见,其 CDF 为 P(P≤0)=logistic(−p)=1−logistic(p)\mathbb{P}(P\leq 0)=\mathrm{logistic}(-p)=1-\mathrm{logistic}(p),因此Another perspective [153] is based on the logistic distribution. Indeed, if PP is a random variable following a logistic distribution with mean pp and scale 11, we saw in Remark 3.3.1 that the CDF is P(P≤0)=logistic(−p)=1−logistic(p)\mathbb{P}(P\leq 0)=\mathrm{logistic}(-p)=1-\mathrm{logistic}(p) and therefore

fs(p,u1,u0)\displaystyle f_{s}(p,{\bm{u}}_{1},{\bm{u}}_{0}) =ifelse(logistic(p),g1(u1),g0(u0))\displaystyle=\mathrm{ifelse}(\mathrm{logistic}(p),g_{1}({\bm{u}}_{1}),g_{0}({\bm{u}}_{0}))
=logistic(p)g1(u1)+(1−logistic(p))g0(u0)\displaystyle=\mathrm{logistic}(p)g_{1}({\bm{u}}_{1})+(1-\mathrm{logistic}(p))g_{0}({\bm{u}}_{0})
=P(P>0)⋅g1(u1)+P(P≤0)⋅g0(u0).\displaystyle=\mathbb{P}(P>0)\cdot g_{1}({\bm{u}}_{1})+\mathbb{P}(P\leq 0)\cdot g_{0}({\bm{u}}_{0}).
注 5.6.1(全局平滑与局部平滑)。Remark 5.6.1 (Global versus local smoothing).
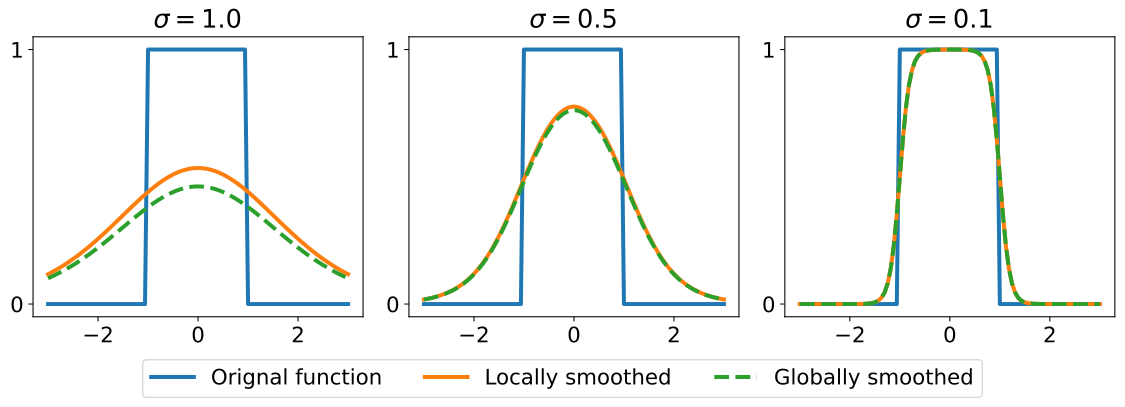
考虑函数Consider the function f(x,y,z):={yif a≤x≤bzotherwise.\displaystyle f(x,y,z)\coloneqq\begin{cases}y&\text{if}\ a\leq x\leq b\\ z&\text{otherwise}\end{cases}. 关于 yy 和 zz 的导数是良定义的。另一方面,关于 xx 的导数不是良定义的,因为它涉及比较算子和逻辑算子 and\mathrm{and}。采用我们的记号,可以将该函数重写为The derivatives w.r.t. yy and zz are well-defined. The derivative w.r.t. xx on the other hand is not well-defined since it involves comparison operators and the logical operator and\mathrm{and}. Using our notation, we can rewrite the function as f(x,y,z)\displaystyle f(x,y,z) =ifelse(and(gt(x,a),lt(x,b)),y,z).\displaystyle=\mathrm{ifelse}(\mathrm{and}(\mathrm{gt}(x,a),\mathrm{lt}(x,b)),y,z). 一种局部平滑方法是在程序的局部将 gt\mathrm{gt} 和 lt\mathrm{lt} 分别替换为 gtσ\mathrm{gt}_{\sigma} 和 ltσ\mathrm{lt}_{\sigma}:A local smoothing approach consists in replacing gt\mathrm{gt} and lt\mathrm{lt} by gtσ\mathrm{gt}_{\sigma} and ltσ\mathrm{lt}_{\sigma} locally in the program: fσloc(x,y,z)\displaystyle f^{\mathrm{loc}}_{\sigma}(x,y,z) :=ifelse(and(gtσ(x,a),ltσ(x,b)),y,z)\displaystyle\coloneqq\mathrm{ifelse}(\mathrm{and}(\mathrm{gt}_{\sigma}(x,a),\mathrm{lt}_{\sigma}(x,b)),y,z) =πaπby+(1−πaπb)z\displaystyle=\pi_{a}\pi_{b}y+(1-\pi_{a}\pi_{b})z 其中where πa\displaystyle\pi_{a} :=sigmoidσ(x−a)\displaystyle\coloneqq\mathrm{sigmoid}_{\sigma}(x-a) πb\displaystyle\pi_{b} :=sigmoidσ(b−x),\displaystyle\coloneqq\mathrm{sigmoid}_{\sigma}(b-x), 对任意 sigmoid 函数 sigmoidσ\mathrm{sigmoid}_{\sigma} 成立。全局平滑方法则使用整个程序的期望for any sigmoid function sigmoidσ\mathrm{sigmoid}_{\sigma}. A global smoothing approach instead uses the expectation of the entire program fσglob(x,y,z)\displaystyle f^{\mathrm{glob}}_{\sigma}(x,y,z) :=EZ[ifelse(and(gt(x+σZ,a),lt(x+σZ,b)),y,z)]\displaystyle\coloneqq\mathbb{E}_{Z}[\mathrm{ifelse}(\mathrm{and}(\mathrm{gt}(x+\sigma Z,a),\mathrm{lt}(x+\sigma Z,b)),y,z)] =ifelse(π,y,z)\displaystyle=\mathrm{ifelse}(\pi,y,z) 其中where π\displaystyle\pi :=EZ[and(gt(x+σZ,a),lt(x+σZ,b))]\displaystyle\coloneqq\mathbb{E}_{Z}[\mathrm{and}(\mathrm{gt}(x+\sigma Z,a),\mathrm{lt}(x+\sigma Z,b))] =P(a≤x+σZ≤b)\displaystyle=\mathbb{P}(a\leq x+\sigma Z\leq b) =sigmoidσ(b−x)−sigmoidσ(a−x)\displaystyle=\mathrm{sigmoid}_{\sigma}(b-x)-\mathrm{sigmoid}_{\sigma}(a-x) =πb−πa,\displaystyle=\pi_{b}-\pi_{a}, 对 sigmoidσ\mathrm{sigmoid}_{\sigma},即 σZ\sigma Z 的累积分布函数。因此我们得到for sigmoidσ\mathrm{sigmoid}_{\sigma} the CDF of σZ\sigma Z. We therefore obtain fσglob(x,y,z)=(πb−πa)y+(1−(πb−πa))z.f^{\mathrm{glob}}_{\sigma}(x,y,z)=(\pi_{b}-\pi_{a})y+(1-(\pi_{b}-\pi_{a}))z. 差异源于这样一个事实:局部方法独立地平滑 a≤xa\leq x 和 x≤bx\leq b(将 1⁡X≥a\operatorname{\mathbf{1}}_{X\geq a} 和 1⁡X≤b\operatorname{\mathbf{1}}_{X\leq b} 视为独立的随机变量),而全局方法则同时平滑 a≤x≤ba\leq x\leq b。在实践中,当 σ→0\sigma\rightarrow 0 时,两种方法都能很好地近似原函数;并且当 σ\sigma 足够小时,两者一致,如图 5.6 所示。The difference stems from the fact that the local approach smoothes out a≤xa\leq x and x≤bx\leq b independently (treating 1⁡X≥a\operatorname{\mathbf{1}}_{X\geq a} and 1⁡X≤b\operatorname{\mathbf{1}}_{X\leq b} as independent random variables), while the global approach smoothes out a≤x≤ba\leq x\leq b simultaneously. In practice, both approaches approximate the original function well as σ→0\sigma\rightarrow 0 and coincide for σ\sigma sufficiently small as illustrated in Fig. 5.6.
图5.6:针对门函数的全局与局部平滑方法;该门函数在 x∈[−1,1]x\in[-1,1] 时为 f(x):=1f(x)\coloneqq 1,否则为 f(x):=0f(x)\coloneqq 0。在我们的记号中,可以写成 f(x)=ifelse(and(gt(x,−1),lt(x,1)),1,0)f(x)=\mathrm{ifelse}(\mathrm{and}(\mathrm{gt}(x,-1),\mathrm{lt}(x,1)),1,0)。局部方法分别对 gt\mathrm{gt} 和 lt\mathrm{lt} 进行平滑。全局方法使用整个程序的期望,见注 5.6.1。我们观察到,尽管对于较大的 σ\sigma,这些方法有所不同,但对于较小的 σ\sigma,它们很快趋于一致。Figure 5.6: Global versus local smoothing approaches on a gate function f(x):=1f(x)\coloneqq 1 if x∈[−1,1]x\in[-1,1], and f(x):=0f(x)\coloneqq 0 otherwise. In our notation, we can write f(x)=ifelse(and(gt(x,−1),lt(x,1)),1,0)f(x)=\mathrm{ifelse}(\mathrm{and}(\mathrm{gt}(x,-1),\mathrm{lt}(x,1)),1,0). A local approach smoothes out gt\mathrm{gt} and lt\mathrm{lt} separately. A global approach uses the expectation of the whole program, see Remark 5.6.1. We observe that, though the approaches differ for large σ\sigma, they quickly coincide for smaller σ\sigma.

5.7 else-if 语句5.7 Else-if statements

上一节关注的是 if-else 语句,即只有两个分支的条件语句。现在我们将研究推广到包含 else-if 语句的条件语句,这类语句有 KK 个分支。In the previous section, we focused on if-else statements: conditionals with only two branches. We now generalize our study to conditionals including else-if statements, that have KK branches.

5.7.1 编码 KK 个分支Encoding KK branches

对于只有 22 个分支的条件语句,我们用二值变量 π∈{0,1}\pi\in\{0,1\} 来编码条件语句需要走的分支。对于有 KK 个分支的条件语句,我们需要一种方式来编码条件语句需要走 KK 个分支中的哪一个。为此,我们可以使用向量 π∈{e1,…,eK}{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\},其中 ei{\bm{e}}_{i} 表示标准基向量(又称 one-hot 向量)For conditionals with only 22 branches, we encoded the branch that the conditional needs to take using the binary variable π∈{0,1}\pi\in\{0,1\}. For conditionals with KK branches, we need a way to encode which of the KK branches the conditional needs to take. To do so, we can use a vector π∈{e1,…,eK}{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\}, where ei{\bm{e}}_{i} denotes the standard basis vector (a.k.a. one-hot vector)

ei:=(0,…,1⏟i,…,0),{\bm{e}}_{i}\coloneqq(0,\dots,\underbrace{1}_{i},\dots,0),

即一个在第 ii 个坐标处为 1、其余 K−1K-1 个坐标为零的向量。向量 ei{\bm{e}}_{i} 是 分类变量 i∈[K]i\in[K] 的编码。a vector with a single one in the coordinate ii and K−1K-1 zeros. The vector ei{\bm{e}}_{i} is the encoding of a categorical variable i∈[K]i\in[K].

组合布尔值Combining booleans

要构造这样的向量 π∈{e1,…,eK}{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\},我们可以组合前面定义的比较运算符和逻辑运算符来定义 π=(π1,…,πK){\bm{\pi}}=(\pi_{1},\dots,\pi_{K})。不过,必须确保只有一个 πi\pi_{i} 非零。例 5.7.1 给出了一个例子。To form such a vector π∈{e1,…,eK}{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\}, we can combine the previously-defined comparison and logical operators to define π=(π1,…,πK){\bm{\pi}}=(\pi_{1},\dots,\pi_{K}). However, we need to ensure that only one πi\pi_{i} is non-zero. We give an example in Example 5.7.1.

argmax 与 argmin 算子Argmax and argmin operators

构造 π{\bm{\pi}} 的另一条途径,是使用 argmax 和 argmin 算子Another way to form π{\bm{\pi}} is to use the argmax and argmin operators

argmax(p)\displaystyle\mathrm{argmax}({\bm{p}}) :=arg max⁡π∈{e1,…,eK}⟨π,p⟩\displaystyle\coloneqq\argmax_{{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\}}\langle{\bm{\pi}},{\bm{p}}\rangle
argmin(p)\displaystyle\mathrm{argmin}({\bm{p}}) :=arg min⁡π∈{e1,…,eK}⟨π,p⟩=argmax(−p).\displaystyle\coloneqq\argmin_{{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\}}\langle{\bm{\pi}},{\bm{p}}\rangle=\mathrm{argmax}(-{\bm{p}}).

它们可以看作大于和小于运算符的自然推广。遇到并列情形时,我们任意打破平局。They can be seen as a natural generalization of the greater than and less than operators. In case of ties, we break them arbitrarily.

5.7.2 条件语句Conditionals

现在,我们可以把条件语句表示为函数 cond ⁣:{e1,…,eK}×VK→V\mathrm{cond}\colon\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\}\times\mathcal{V}^{K}\to\mathcal{V},其定义为We can now express a conditional statement as the function
cond ⁣:{e1,…,eK}×VK→V\mathrm{cond}\colon\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\}\times\mathcal{V}^{K}\to\mathcal{V} defined by

cond(π,v1,…,vK)\displaystyle\mathrm{cond}({\bm{\pi}},{\bm{v}}_{1},\dots,{\bm{v}}_{K}) :={v1 if π=e1⋮vK if π=eK\displaystyle\coloneqq\begin{cases}{\bm{v}}_{1}&\text{ if }{\bm{\pi}}={\bm{e}}_{1}\\ \vdots&\\ {\bm{v}}_{K}&\text{ if }{\bm{\pi}}={\bm{e}}_{K}\end{cases} (5.5)
=∑i=1Kπivi.\displaystyle=\sum_{i=1}^{K}\pi_{i}{\bm{v}}_{i}.

与 ifelse\mathrm{ifelse} 函数类似,cond\mathrm{cond} 函数关于 π∈{e1,…,eK}{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\} 不连续且不可微。不过,若对某个 ii 固定 π=ei{\bm{\pi}}={\bm{e}}_{i},则该函数关于 vi{\bm{v}}_{i} 是线性的,并在 j≠ij\neq i 时关于 vj{\bm{v}}_{j} 为常值。下面用一个简单例子说明如何借助这一形式化来表达。Similarly to the ifelse\mathrm{ifelse} function, the cond\mathrm{cond} function is discontinuous and nondifferentiable w.r.t. π∈{e1,…,eK}{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\}. However, given π=ei{\bm{\pi}}={\bm{e}}_{i} fixed for some ii, the function is linear in vi{\bm{v}}_{i} and constant in vj{\bm{v}}_{j} for j≠ij\neq i. We illustrate how to express a simple example, using this formalism.

例 5.7.1(软阈值算子)。Example 5.7.1 (Soft-thresholding operator).
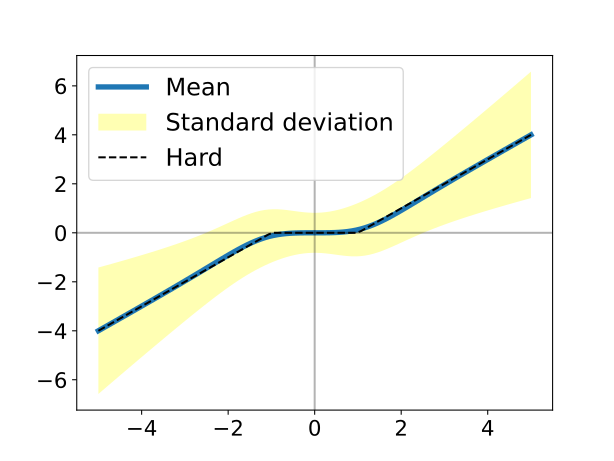
软阈值算子(另见第 16.4 节)是一种常用于促进稀疏性的算子,其定义为The soft-thresholding operator (see also Section 16.4) is a commonly-used operator to promote sparsity. It is defined by SoftThreshold(u,λ):={0 if ∣u∣≤λu−λ if u≥λu+λ if u≤−λ.\mathrm{SoftThreshold}(u,\lambda)\coloneqq\begin{cases}0&\text{ if }|u|\leq\lambda\\ u-\lambda&\text{ if }u\geq\lambda\\ u+\lambda&\text{ if }u\leq-\lambda\end{cases}. 为了在我们的形式体系中表达它,我们可以使用比较算子将 π∈{e1,e2,e3}{\bm{\pi}}\in\{{\bm{e}}_{1},{\bm{e}}_{2},{\bm{e}}_{3}\} 定义为To express it in our formalism, we can define π∈{e1,e2,e3}{\bm{\pi}}\in\{{\bm{e}}_{1},{\bm{e}}_{2},{\bm{e}}_{3}\} using comparison operators as π\displaystyle{\bm{\pi}} :=(lt(∣u∣,λ),gt(u,λ),lt(u,−λ))\displaystyle\coloneqq(\mathrm{lt}(|u|,\lambda),\mathrm{gt}(u,\lambda),\mathrm{lt}(u,-\lambda)) =(step(λ−∣u∣),step(u−λ),step(−u−λ)).\displaystyle=(\mathrm{step}(\lambda-|u|),\mathrm{step}(u-\lambda),\mathrm{step}(-u-\lambda)). 等价地,我们也可以使用 argmax 算子将 π{\bm{\pi}} 定义为Equivalently, we can also define π{\bm{\pi}} using an argmax operator as π:=argmax((λ−∣u∣,u−λ,−u−λ)).{\bm{\pi}}\coloneqq\mathrm{argmax}((\lambda-|u|,u-\lambda,-u-\lambda)). 在出现并列的情况下(这发生在 ∣u∣=λ|u|=\lambda 处),我们在 π{\bm{\pi}} 中只保留一个非零坐标。于是,可以将该算子重写为In case of ties, which happens at ∣u∣=λ|u|=\lambda, we keep only one non-zero coordinate in π{\bm{\pi}}. We can then rewrite the operator as SoftThreshold(u,λ)=cond(π,0,u−λ,u+λ).\mathrm{SoftThreshold}(u,\lambda)=\mathrm{cond}({\bm{\pi}},0,u-\lambda,u+\lambda). 如我们将看到的,把 argmax\mathrm{argmax} 替换为 softargmax\mathrm{softargmax} 会在三个可能分支上诱导出一个分类分布。均值可视为该算子的一个平滑版本,我们也可以计算其标准差,如图 5.7 所示。As we will see, replacing argmax\mathrm{argmax} with softargmax\mathrm{softargmax} induces a categorical distribution over the three possible branches. The mean value can be seen as a smoothed out version of the operator, and we can also compute the standard deviation, as illustrated in Fig. 5.7.
图 5.7:一个含三个分支的条件语句:软阈值算子(见例 5.7.1)。它是分段线性函数(黑色点线)。借助 softargmax,可以在这三个分支上诱导出一个分类概率分布。期望值(蓝线)可视为该算子经平滑后的版本。所诱导的分布还使我们能够计算标准差。Figure 5.7: A conditional with three branches: the soft-thresholding operator (see Example 5.7.1). It is a piecewise linear function (dotted black line). Using a softargmax, we can induce a categorical probability distribution over the three branches. The expected value (blue line) can be seen as a smoothed out version of the operator. The induced distribution allows us to also compute the standard deviation.

5.7.3 通过分支变量求导Differentiating through branch variables

当 π{\bm{\pi}} 固定时,cond(π,v1,…,vK)\mathrm{cond}({\bm{\pi}},{\bm{v}}_{1},\dots,{\bm{v}}_{K}) 是关于 vi{\bm{v}}_{i} 的有效函数,因而仍可作为计算图中的一个节点使用。由于关于 vi{\bm{v}}_{i} 具有线性性,可得关于 vi{\bm{v}}_{i} 的雅可比矩阵为For π{\bm{\pi}} fixed, cond(π,v1,…,vK)\mathrm{cond}({\bm{\pi}},{\bm{v}}_{1},\dots,{\bm{v}}_{K}) is a valid function w.r.t. vi{\bm{v}}_{i}, and can therefore again be used as a node in a computational graph. Due to the linearity w.r.t. vi{\bm{v}}_{i}, we obtain that the Jacobian w.r.t. vi{\bm{v}}_{i} is

∂vicond(π,v1,…,vK)\displaystyle\partial_{{\bm{v}}_{i}}\mathrm{cond}({\bm{\pi}},{\bm{v}}_{1},\dots,{\bm{v}}_{K}) :={I if π=ei0 if π≠ei.\displaystyle\coloneqq\begin{cases}I&\text{ if }{\bm{\pi}}={\bm{e}}_{i}\\ {\mathbf{0}}&\text{ if }{\bm{\pi}}\neq{\bm{e}}_{i}\end{cases}.

设 gi ⁣:Ui→Vg_{i}\colon\mathcal{U}_{i}\to\mathcal{V} 为可微函数,且 ui∈Ui{\bm{u}}_{i}\in\mathcal{U}_{i}。若定义复合Let gi ⁣:Ui→Vg_{i}\colon\mathcal{U}_{i}\to\mathcal{V} be a differentiable function and ui∈Ui{\bm{u}}_{i}\in\mathcal{U}_{i}. If we define the composition

f(π,u1,…,uK):=cond(π,g1(u1),…,gK(uK)),f({\bm{\pi}},{\bm{u}}_{1},\dots,{\bm{u}}_{K})\coloneqq\mathrm{cond}({\bm{\pi}},g_{1}({\bm{u}}_{1}),\dots,g_{K}({\bm{u}}_{K})),

则可得关于 ui{\bm{u}}_{i} 的雅可比矩阵为we then obtain that the Jacobian w.r.t. ui{\bm{u}}_{i} is

∂uif(π,u1,…,uK)\displaystyle\partial_{{\bm{u}}_{i}}f({\bm{\pi}},{\bm{u}}_{1},\dots,{\bm{u}}_{K}) :={∂gi(ui) if π=ei0 if π≠ei.\displaystyle\coloneqq\begin{cases}\partial g_{i}({\bm{u}}_{i})&\text{ if }{\bm{\pi}}={\bm{e}}_{i}\\ {\mathbf{0}}&\text{ if }{\bm{\pi}}\neq{\bm{e}}_{i}\end{cases}.

只要各 gig_{i} 函数可微,我们就能在 π{\bm{\pi}} 固定时通过分支变量 ui{\bm{u}}_{i} 求导。As long as the gig_{i} functions are differentiable, we can therefore differentiate through the branch variables ui{\bm{u}}_{i} for π{\bm{\pi}} fixed.

5.7.4 通过谓词变量求导Differentiating through predicate variables

正如我们所见,π{\bm{\pi}} 既可以由比较运算符和逻辑运算符组合得到,也可以由 argmax 和 argmin 算子得到。下面说明这些算子为何会带来问题。例如,假设我们希望表示函数As we saw, π{\bm{\pi}} can be obtained by combining comparison and logical operators, or it can be obtained by argmax and argmin operators. We illustrate here why these operators are problematic. For example, suppose we want to express the function

fa(p,u1,…,uK):={v1 if p=e1⋮vK if p=eK.f_{a}({\bm{p}},{\bm{u}}_{1},\dots,{\bm{u}}_{K})\coloneqq\begin{cases}{\bm{v}}_{1}&\text{ if }{\bm{p}}={\bm{e}}_{1}\\ \vdots&\\ {\bm{v}}_{K}&\text{ if }{\bm{p}}={\bm{e}}_{K}\end{cases}.

采用我们的记号,这可以表示为In our notation, this can be expressed as

fa(p,u1,…,uK):=cond(argmax(p),g1(u1),…,gK(uK)),f_{a}({\bm{p}},{\bm{u}}_{1},\dots,{\bm{u}}_{K})\coloneqq\mathrm{cond}(\mathrm{argmax}({\bm{p}}),g_{1}({\bm{u}}_{1}),\dots,g_{K}({\bm{u}}_{K})),

与 ifelse 情形一样,关于 p{\bm{p}} 的雅可比矩阵几乎处处为零,As for the ifelse case, the Jacobian w.r.t. p{\bm{p}} is null almost everywhere,

∂pfa(p,u1,…,uK)=0.\partial_{\bm{p}}f_{a}({\bm{p}},{\bm{u}}_{1},\dots,{\bm{u}}_{K})={\mathbf{0}}.

5.7.5 连续松弛Continuous relaxations

与 Heaviside 阶跃函数类似,argmax 和 argmin 函数也是分段常值函数,并在出现平局时不连续。它们的雅可比矩阵几乎处处为零,在出现平局时则无定义。因此,尽管其雅可比矩阵几乎处处良定义,它们却不提供有用信息,还会阻碍梯度反向传播。我们可以用 softargmax 替换 argmaxSimilarly to the Heaviside step function, the argmax and argmin functions are piecewise constant, with discontinuities in case of ties. Their Jacobians are zero almost everywhere, and undefined in case of ties. Therefore, while their Jacobian is well-defined almost everywhere, they are uninformative and prevent gradient backpropagation. We can replace the argmax with a softargmax

softargmax(p):=exp⁡(p)∑i=1Kexp⁡(pi)∈△K\mathrm{softargmax}({\bm{p}})\coloneqq\frac{\exp({\bm{p}})}{\sum_{i=1}^{K}\exp(p_{i})}\in\triangle^{K}

类似地and similarly

softargmin(p):=softargmax(−p)∈△K.\mathrm{softargmin}({\bm{p}})\coloneqq\mathrm{softargmax}(-{\bm{p}})\in\triangle^{K}.

argmax 的其他松弛方式同样可行,详见 13.7 节。关于扰动的视角,另见 14.5.3 节。Other relaxations of the argmax are possible, as discussed in Section 13.7. See also Section 14.5.3 for the perturbation perspective.

幸运的是,该定义Fortunately, the definition

cond(π,v1,…,vK)=∑i=1Kπivi\mathrm{cond}({\bm{\pi}},{\bm{v}}_{1},\dots,{\bm{v}}_{K})=\sum_{i=1}^{K}\pi_{i}{\bm{v}}_{i}

若以 π∈△K{\bm{\pi}}\in\triangle^{K} 代替 π∈{e1,…,eK}{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\},该定义便完全成立,因此可视为式 5.5 的推广。此时若定义is perfectly valid if we use π∈△K{\bm{\pi}}\in\triangle^{K} instead of π∈{e1,…,eK}{\bm{\pi}}\in\{{\bm{e}}_{1},\dots,{\bm{e}}_{K}\}, and can therefore be seen as an extension of Eq. 5.5. If we now define

fs(p,u1,…,uK)\displaystyle f_{s}({\bm{p}},{\bm{u}}_{1},\dots,{\bm{u}}_{K}) :=cond(softargmax(p),g1(u1),…,gK(uK))\displaystyle\coloneqq\mathrm{cond}(\mathrm{softargmax}({\bm{p}}),g_{1}({\bm{u}}_{1}),\dots,g_{K}({\bm{u}}_{K}))
=∑i=1K[softargmax(p)]i⋅gi(ui),\displaystyle=\sum_{i=1}^{K}[\mathrm{softargmax}({\bm{p}})]_{i}\cdot g_{i}({\bm{u}}_{i}), (5.6)

雅可比矩阵变为the Jacobian becomes

∂pfs(p,u1,…,uK)=∂softargmax(p)(g1(u1),…,gK(uK)),\partial_{\bm{p}}f_{s}({\bm{p}},{\bm{u}}_{1},\dots,{\bm{u}}_{K})=\partial\mathrm{softargmax}({\bm{p}})(g_{1}({\bm{u}}_{1}),\dots,g_{K}({\bm{u}}_{K})),

它处处非零,因而梯度得以沿计算图反向传播。which is non-null everywhere, allowing gradients to backpropagate through the computational graph.

概率视角Probabilistic perspective

从概率视角看,式 5.6 可视为 gi(ui)g_{i}({\bm{u}}_{i}) 的期望,其中 i∈[K]i\in[K] 是服从以 π=softargmax(p){\bm{\pi}}=\mathrm{softargmax}({\bm{p}}) 为参数的 分类分布的 分类随机变量:From a probabilistic perspective, we can view Eq. 5.6 as the expectation of gi(ui)g_{i}({\bm{u}}_{i}), where i∈[K]i\in[K] is a categorical random variable distributed according to a categorical distribution with parameter π=softargmax(p){\bm{\pi}}=\mathrm{softargmax}({\bm{p}}):

fs(p,u1,…,uK)=Ei∼Categorical(softargmax(p))[gi(ui)].f_{s}({\bm{p}},{\bm{u}}_{1},\dots,{\bm{u}}_{K})=\mathbb{E}_{i\sim\mathrm{Categorical}(\mathrm{softargmax}({\bm{p}}))}\left[g_{i}({\bm{u}}_{i})\right].

对 KK 个可能分支取期望,可使函数关于 p{\bm{p}} 可微,代价则是需要计算所有分支,而非只计算单个分支。与 if-else 情形类似,如有需要,方差可按如下方式计算Taking the expectation over the KK possible branches makes the function differentiable with respect to p{\bm{p}}, at the cost of evaluating all branches, instead of a single one. Similarly as for the if-else case, we can compute the variance if needed as

Vi∼Categorical(softargmax(p))[gi(ui)]\displaystyle\mathbb{V}_{i\sim\mathrm{Categorical}(\mathrm{softargmax}({\bm{p}}))}\left[g_{i}({\bm{u}}_{i})\right]
=\displaystyle= Ei∼Categorical(softargmax(p))[(fs(p,u1,…,uK)−gi(ui))2].\displaystyle\mathbb{E}_{i\sim\mathrm{Categorical}(\mathrm{softargmax}({\bm{p}}))}\left[(f_{s}({\bm{p}},{\bm{u}}_{1},\dots,{\bm{u}}_{K})-g_{i}({\bm{u}}_{i}))^{2}\right].

图 5.7 对此作了说明。This is illustrated in Fig. 5.7.

5.8 for 循环5.8 For loops

for 循环是一种控制流,用于依次调用固定数目 KK 个函数,并复用上一次迭代的输出。就最一般的情形而言,for 循环可写为如下形式。For loops are a control flow for sequentially calling a fixed number KK of functions, reusing the output from the previous iteration. In full generality, a for loop can be written as follows.

算法 1 r=forloop(s0){\bm{r}}=\mathrm{forloop}({\bm{s}}_{0})Algorithm 1 r=forloop(s0){\bm{r}}=\mathrm{forloop}({\bm{s}}_{0})
for k:=1,…,Kk\coloneqq 1,\ldots,K do
  sk:=fk(sk−1){\bm{s}}_{k}\coloneqq f_{k}({\bm{s}}_{k-1})
r:=sK{\bm{r}}\coloneqq{\bm{s}}_{K}

如图 5.9 所示,这定义了一条计算链。若各函数 fkf_{k} 均可微,便定义了一个有效的计算图,因此我们可以借助自动微分,对 forloop\mathrm{forloop} 关于其输入 s0{\bm{s}}_{0} 求导。4.2 节回顾的前馈网络可视为参数化的 for 循环,即As illustrated in Fig. 5.9, this defines a computation chain. Assuming the functions fkf_{k} are all differentiable, this defines a valid computation graph, we can therefore use automatic differentiation to differentiate forloop\mathrm{forloop} w.r.t. its input s0{\bm{s}}_{0}. Feedforward networks, reviewed in Section 4.2, can be seen as parameterized for loops, i.e.,

fk(sk−1):=gk(sk−1,wk),f_{k}({\bm{s}}_{k-1})\coloneqq g_{k}({\bm{s}}_{k-1},{\bm{w}}_{k}),

其中 gkg_{k} 为某个可微函数。for some differentiable function gkg_{k}.

例 5.8.1(展开的梯度下降)Example 5.8.1 (Unrolled gradient descent).
假设我们要关于 w{\bm{w}} 最小化如下函数Suppose we want to minimize w.r.t. w{\bm{w}} the function L(w,λ):=1N∑i=1Nℓ(h(xi,w),yi)+λ2∥w∥22.L({\bm{w}},\lambda)\coloneqq\frac{1}{N}\sum_{i=1}^{N}\ell(h({\bm{x}}_{i},{\bm{w}}),{\bm{y}}_{i})+\frac{\lambda}{2}\|{\bm{w}}\|^{2}_{2}. 给定初始值 w0{\bm{w}}_{0},梯度下降(第 16.1 节)按如下形式迭代:Given an initialization w0{\bm{w}}_{0}, gradient descent (Section 16.1) performs iterations of the form wk=f(wk−1,γk,λ):=wk−1−γk∇1L(wk−1,λ).{\bm{w}}_{k}=f({\bm{w}}_{k-1},\gamma_{k},\lambda)\coloneqq{\bm{w}}_{k-1}-\gamma_{k}\nabla_{1}L({\bm{w}}_{k-1},\lambda). 因此,梯度下降可以写成一个 for 循环:Gradient descent can therefore be expressed as a for loop with fk(wk−1):=f(wk−1,γk,λ).f_{k}({\bm{w}}_{k-1})\coloneqq f({\bm{w}}_{k-1},\gamma_{k},\lambda). 这意味着,只要 ff 可微——也就是 LL 二次可微——我们就能通过梯度下降的迭代过程求导。例如,这可用于对超参数 γk\gamma_{k} 或 λ\lambda 进行基于梯度的优化。它是双层优化的一个特例;另见第 11 章。This means that we can differentiate through the iterations of gradient descent, as long as ff is differentiable, meaning that LL is twice differentiable. This is useful for instance to perform gradient-based optimization of the hyperparameters γk\gamma_{k} or λ\lambda. This is a special case of bilevel optimization; see also Chapter 11.
例 5.8.2(冒泡排序)Example 5.8.2 (Bubble sort).
冒泡排序是一种简单的排序算法,它通过反复按需交换元素来工作。在数学上,交换两个元素 ii 与 jj,可以写成由 RN×[N]×[N]\mathbb{R}^{N}\times[N]\times[N] 到 RN\mathbb{R}^{N} 的一个函数,定义为Bubble sort is a simple sorting algorithm that works by repeatedly swapping elements if necessary. Mathematically, swapping two elements ii and jj can be written as a function from RN×[N]×[N]\mathbb{R}^{N}\times[N]\times[N] to RN\mathbb{R}^{N} defined by swap(v,i,j):=v+(vj−vi)ei+(vi−vj)ej.\mathrm{swap}({\bm{v}},i,j)\coloneqq{\bm{v}}+(v_{j}-v_{i}){\bm{e}}_{i}+(v_{i}-v_{j}){\bm{e}}_{j}. 于是,我们可以把冒泡排序写成We can then write bubble sort as for i:=1,…,N do\displaystyle\text{\bf for} \ i\coloneqq 1,\dots,N \ \text{\bf do} for j:=1,…,N−i−1 do\displaystyle\quad\text{\bf for} \ j\coloneqq 1,\dots,N-i-1 \ \text{\bf do} v′:=swap(v,j,j+1)\displaystyle\quad\quad{\bm{v}}^{\prime}\coloneqq\mathrm{swap}({\bm{v}},j,j+1) π:=step(vj−vj+1)\displaystyle\quad\quad\pi\coloneqq\mathrm{step}(v_{j}-v_{j+1}) v←ifelse(π,v′,v)\displaystyle\quad\quad{\bm{v}}\leftarrow\mathrm{ifelse}(\pi,{\bm{v}}^{\prime},{\bm{v}}) 将 Heaviside 阶跃函数换为 logistic 函数,便得到该算法的一个平滑版本。Replacing the Heaviside step function with the logistic function gives a smoothed version of the algorithm.

图 5.9:scan 函数的计算图。序列到序列 RNN 可视为参数化的 scan 函数。 Figure 5.9: Computation graph of the scan function. Sequence-to-sequence RNNs can be seen as a parameterized scan function.
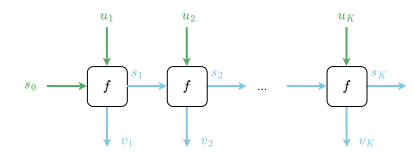
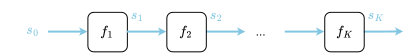
图 5.8:for 循环构成一条计算链。前馈网络可视为参数化的 for 循环,其中每个函数 fkf_{k} 依赖于某些参数 wk{\bm{w}}_{k}。Figure 5.8: A for loop forms a computation chain. A feed forward network can be seen as a parameterized for loop, where each function fkf_{k} depends on some parameters wk{\bm{w}}_{k}.

5.9 scan 函数5.9 Scan functions

scan 是源自函数式编程的高阶函数(即函数的函数)。它可用于对各个元素 uk{\bm{u}}_{k} 执行某种操作 ff,并将该操作的结果 sk{\bm{s}}_{k} 传递至下一次迭代。Scan is a higher-order function (meaning a function of a function) originating from functional programming. It is useful to perform an operation ff on individual elements uk{\bm{u}}_{k} while carrying the result sk{\bm{s}}_{k} of that operation to the next iteration.

算法 2 r=scan(s0,u1,…,uK){\bm{r}}=\mathrm{scan}({\bm{s}}_{0},{\bm{u}}_{1},\dots,{\bm{u}}_{K})Algorithm 2 r=scan(s0,u1,…,uK){\bm{r}}=\mathrm{scan}({\bm{s}}_{0},{\bm{u}}_{1},\dots,{\bm{u}}_{K})
for k:=1,…,Kk\coloneqq 1,\ldots,K do
  sk,vk:=f(sk−1,uk){\bm{s}}_{k},{\bm{v}}_{k}\coloneqq f({\bm{s}}_{k-1},{\bm{u}}_{k})
r:=(sK,v1,…,vK){\bm{r}}\coloneqq({\bm{s}}_{K},{\bm{v}}_{1},\dots,{\bm{v}}_{K})

如图 5.9 所示,这同样定义了一个有效的计算图;只要函数 ff 可微,便可以用自动微分对其求导。4.7 节讨论的序列到序列 RNN 可以视为参数化的 scan。这一抽象的优越之处在于,并行 scan 算法在计算机科学中已有广泛研究 [25, 182]。As illustrated in Fig. 5.9, this again defines a valid computational graph and can be differentiated through using autodiff, assuming the function ff is differentiable. Sequence-to-sequence RNNs, reviewed in Section 4.7, can be seen as a parameterized scan. An advantage of this abstraction is that parallel scan algorithms have been studied extensively in computer science [25, 182].

例 5.9.1(前缀和)。Example 5.9.1 (Prefix sum).
Scan 可视为前缀和(又称累积和)从加法到任意二元运算的推广。事实上,前缀和相当于执行Scan can be seen as a generalization of the prefix sum (a.k.a. cumulative sum) from the addition to any binary operation. Indeed, a prefix sum amounts to perform v1\displaystyle{\bm{v}}_{1} :=u1\displaystyle\coloneqq{\bm{u}}_{1} v2\displaystyle{\bm{v}}_{2} :=u1+u2\displaystyle\coloneqq{\bm{u}}_{1}+{\bm{u}}_{2} v3\displaystyle{\bm{v}}_{3} :=u1+u2+u3\displaystyle\coloneqq{\bm{u}}_{1}+{\bm{u}}_{2}+{\bm{u}}_{3} 它可以定义如下,从而表示为一次 scan:which can be expressed as a scan by defining vk\displaystyle{\bm{v}}_{k} :=sk−1+uk\displaystyle\coloneqq{\bm{s}}_{k-1}+{\bm{u}}_{k} f(sk−1,uk)\displaystyle f({\bm{s}}_{k-1},{\bm{u}}_{k}) :=(vk,vk)\displaystyle\coloneqq({\bm{v}}_{k},{\bm{v}}_{k}) 从 s0=0{\bm{s}}_{0}={\mathbf{0}} 开始(此处 sK{\bm{s}}_{K} 与 vK{\bm{v}}_{K} 是多余的)。starting from s0=0{\bm{s}}_{0}={\mathbf{0}} (sK{\bm{s}}_{K} and vK{\bm{v}}_{K} are redundant in this case).

5.10 while 循环5.10 While loops

5.10.1 将 while 循环视为循环图While loops as cyclic graphs

while 循环是一种控制流:它重复执行某项操作,并复用上一次迭代的输出,直至某个条件得到满足。设 f ⁣:S→{0,1}f\colon\mathcal{S}\to\{0,1\} 是判断应当停止(π=1\pi=1)还是继续(π=0\pi=0)的函数,g ⁣:S→Sg\colon\mathcal{S}\to\mathcal{S} 是执行操作的函数。于是,不失一般性,while 循环可以写成如下形式。A while loop is a control flow used to repeatedly perform an operation, reusing the output of the previous iteration, until a certain condition is met. Suppose f ⁣:S→{0,1}f\colon\mathcal{S}\to\{0,1\} is a function to determine whether to stop (π=1\pi=1) or continue (π=0\pi=0) and g ⁣:S→Sg\colon\mathcal{S}\to\mathcal{S} is a function for performing an operation. Then, without loss of generality, a while loop can be written as follows.

算法 3 r=whileloop(s){\bm{r}}=\mathrm{whileloop}({\bm{s}})Algorithm 3 r=whileloop(s){\bm{r}}=\mathrm{whileloop}({\bm{s}})
π←f(s)\pi\leftarrow f({\bm{s}})
while π=0\pi=0 do
  s←g(s){\bm{s}}\leftarrow g({\bm{s}})
  π←f(s)\pi\leftarrow f({\bm{s}})
r:=s{\bm{r}}\coloneqq{\bm{s}}

这个定义在某种程度上是循环的,因为我们使用了 while 关键字。不过,我们也可以等价地把该算法改写为递归形式。This definition is somewhat cyclic, as we used the while keyword. However, we can equivalently rewrite the algorithm recursively.

算法 4 r=whileloop(s){\bm{r}}=\mathrm{whileloop}({\bm{s}})Algorithm 4 r=whileloop(s){\bm{r}}=\mathrm{whileloop}({\bm{s}})
π:=f(s)\pi\coloneqq f({\bm{s}})
if π=0\pi=0 then
  r:=s{\bm{r}}\coloneqq{\bm{s}}
else
  r:=whileloop(g(s)){\bm{r}}\coloneqq\mathrm{whileloop}(g({\bm{s}}))

与 for 循环和 scan 不同,while 循环的迭代次数事先未知,甚至可能无限。就这一点而言,while 循环可以视为一个循环图,如图 5.10 所示。Unlike for loops and scan, the number of iterations of while loops is not known ahead of time, and may even be infinite. In this respect, a while loop can be seen as a cyclic graph, as illustrated in Fig. 5.10.
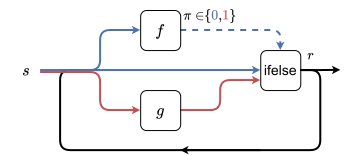
图 5.10:while 循环可以表示为循环图。若 π=1\pi=1,则 while 循环停止;若 π=0\pi=0,则再执行一次迭代 s←g(s){\bm{s}}\leftarrow g({\bm{s}})、π←f(s)\pi\leftarrow f({\bm{s}})。Figure 5.10: A while loop can be represented as a cyclic graph. The while loop stops if π=1\pi=1 and performs another iteration s←g(s){\bm{s}}\leftarrow g({\bm{s}}), π←f(s)\pi\leftarrow f({\bm{s}}) if π=0\pi=0.

惰性求值的重要性Importance of lazy evaluation

我们还可以用 5.6 节定义的 ifelse\mathrm{ifelse} 函数,把算法 4 实现为We can also implement Algorithm 4 in terms of the ifelse\mathrm{ifelse} function defined in Section 5.6 as

r\displaystyle{\bm{r}} :=ifelse(f(s),whileloop(g(s)),s)\displaystyle\coloneqq\mathrm{ifelse}(f({\bm{s}}),\mathrm{whileloop}(g({\bm{s}})),{\bm{s}})
=f(s)⋅whileloop(g(s))+(1−f(s))⋅s.\displaystyle=f({\bm{s}})\cdot\mathrm{whileloop}(g({\bm{s}}))+(1-f({\bm{s}}))\cdot{\bm{s}}.

然而,为避免无限递归,关键在于 ifelse\mathrm{ifelse} 必须支持惰性求值。也就是说,上面定义中的 whileloop(g(s))\mathrm{whileloop}(g({\bm{s}})) 当且仅当 π=f(s)=1\pi=f({\bm{s}})=1 时才应当被求值。换言之,f(s)∈{0,1}f({\bm{s}})\in\{0,1\} 这一事实对于保证递归的良定义至关重要。However, to avoid an infinite recursion, it is crucial that ifelse\mathrm{ifelse} supports lazy evaluation. That is, whileloop(g(s))\mathrm{whileloop}(g({\bm{s}})) in the definition above should be evaluated if and only if π=f(s)=1\pi=f({\bm{s}})=1. In other words, the fact that f(s)∈{0,1}f({\bm{s}})\in\{0,1\} is crucial to ensure that the recursion is well-defined.

5.10.2 展开的 while 循环Unrolled while loops

为避免无界 while 循环带来的问题,我们可以强制 while 循环在 TT 次迭代后停止,即截断 while 循环。展开算法 4 可得(此处取 T=3T=3)To avoid the issues with unbounded while loops, we can enforce that a while loop stops after TT iterations, i.e., we can truncate the while loop. Unrolling Algorithm 4 gives (here with T=3T=3)

π0:=f(s0)\displaystyle\pi_{0}\coloneqq f({\bm{s}}_{0})
if π0=1 then\displaystyle\text{\bf{if}} \ \pi_{0}=1 \ \textbf{\bf{then}}
r:=s0\displaystyle\quad{\bm{r}}\coloneqq{\bm{s}}_{0}
elseelse
s1:=g(s0),π1:=f(s1)\displaystyle\quad{\bm{s}}_{1}\coloneqq g({\bm{s}}_{0}),\pi_{1}\coloneqq f({\bm{s}}_{1})
if π1=1 then\displaystyle\quad\text{\bf{if}} \ \pi_{1}=1 \ \textbf{\bf{then}}
r:=s1\displaystyle\quad\quad{\bm{r}}\coloneqq{\bm{s}}_{1}
else else
s2:=g(s1),π2:=f(s2)\displaystyle\quad\quad{\bm{s}}_{2}\coloneqq g({\bm{s}}_{1}),\pi_{2}\coloneqq f({\bm{s}}_{2})
if π2=1 then\displaystyle\quad\quad\text{\bf{if}} \ \pi_{2}=1 \ \textbf{\bf{then}}
r:=s2\displaystyle\quad\quad\quad{\bm{r}}\coloneqq{\bm{s}}_{2}
else  else
r:=s3:=g(s2)\displaystyle\quad\quad\quad{\bm{r}}\coloneqq{\bm{s}}_{3}\coloneqq g({\bm{s}}_{2})

借助 ifelse\mathrm{ifelse} 函数,我们可以将其改写为Using the ifelse\mathrm{ifelse} function, we can rewrite it as

r=ifelse(\displaystyle{\bm{r}}=\mathrm{ifelse}( π0,\displaystyle\pi_{0},
s0,\displaystyle{\bm{s}}_{0},
ifelse(π1,\displaystyle\mathrm{ifelse}(\pi_{1},
s1,\displaystyle\hskip 28.45274pt{\bm{s}}_{1},
ifelse(π2,\displaystyle\hskip 28.45274pt\mathrm{ifelse}(\pi_{2},
s2,\displaystyle\hskip 56.9055pt{\bm{s}}_{2},
s3)))\displaystyle\hskip 56.9055pt{\bm{s}}_{3})))

而这本身又等价于which is itself equivalent to

r\displaystyle{\bm{r}} =π0s0+(1−π0)[π1s1+(1−π1)[π2s2+(1−π2)s3]]\displaystyle=\pi_{0}{\bm{s}}_{0}+(1-\pi_{0})\left[\pi_{1}{\bm{s}}_{1}+(1-\pi_{1})\left[\pi_{2}{\bm{s}}_{2}+(1-\pi_{2}){\bm{s}}_{3}\right]\right]
=π0s0+(1−π0)π1s1+(1−π0)(1−π1)π2s2+(1−π0)(1−π1)(1−π2)s3.\displaystyle=\pi_{0}{\bm{s}}_{0}+(1-\pi_{0})\pi_{1}{\bm{s}}_{1}+(1-\pi_{0})(1-\pi_{1})\pi_{2}{\bm{s}}_{2}+(1-\pi_{0})(1-\pi_{1})(1-\pi_{2}){\bm{s}}_{3}.

更一般地,对于 T∈NT\in\mathbb{N},公式为More generally, for T∈NT\in\mathbb{N}, the formula is

r\displaystyle{\bm{r}} =∑i=0T((1−π0)…(1−πi−1))πisi\displaystyle=\sum_{i=0}^{T}\left((1-\pi_{0})\dots(1-\pi_{i-1})\right)\pi_{i}{\bm{s}}_{i}
=∑i=0T(∏j=0i−1(1−πj))πisi,\displaystyle=\sum_{i=0}^{T}\left(\prod_{j=0}^{i-1}(1-\pi_{j})\right)\pi_{i}{\bm{s}}_{i},

其中我们定义了where we defined

si\displaystyle{\bm{s}}_{i} :=g(si−1):=gi(s0):=g∘⋯∘g⏟i times(s0)∈S\displaystyle\coloneqq g({\bm{s}}_{i-1})\coloneqq g^{i}({\bm{s}}_{0})\coloneqq\underbrace{g\circ\dots\circ g}_{i\text{ times}}({\bm{s}}_{0})\in\mathcal{S}
πi\displaystyle\pi_{i} :=f(si)∈{0,1}.\displaystyle\coloneqq f({\bm{s}}_{i})\in\{0,1\}.

另见 [153]。若进一步引入简记See also [153]. If we further define the shorthand notation

π~0\displaystyle\tilde{\pi}_{0} :=π0\displaystyle\coloneqq\pi_{0}
π~i\displaystyle\tilde{\pi}_{i} :=(∏j=0i−1(1−πj))πii∈{1,…,T},\displaystyle\coloneqq\left(\prod_{j=0}^{i-1}(1-\pi_{j})\right)\pi_{i}\quad i\in\{1,\dots,T\},

使得 π~:=(π~0,π~1,…,π~T)∈△T+1\tilde{{\bm{\pi}}}\coloneqq(\tilde{\pi}_{0},\tilde{\pi}_{1},\dots,\tilde{\pi}_{T})\in\triangle^{T+1} 是一个离散概率分布,包含在 TT 次迭代中每一次停止的概率,那么我们就可以用条件语句改写截断 while 循环的输出,so that π~:=(π~0,π~1,…,π~T)∈△T+1\tilde{{\bm{\pi}}}\coloneqq(\tilde{\pi}_{0},\tilde{\pi}_{1},\dots,\tilde{\pi}_{T})\in\triangle^{T+1} is a discrete probability distribution containing the probabilities to stop at each of the TT iterations, we can rewrite the output of a truncated while using a conditional,

r=cond(π~,s0,s1,…,sT)=∑t=0Tπ~tst.{\bm{r}}=\mathrm{cond}(\tilde{{\bm{\pi}}},{\bm{s}}_{0},{\bm{s}}_{1},\dots,{\bm{s}}_{T})=\sum_{t=0}^{T}\tilde{\pi}_{t}{\bm{s}}_{t}.

如图 5.11 所示。This is illustrated in Fig. 5.11.
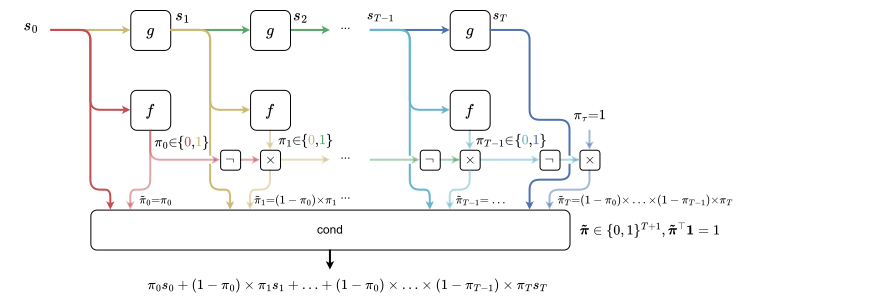
图 5.11:展开的截断 while 循环的计算图。与图 5.5 一样,实线表示连续变量,虚线表示离散变量。一个至多迭代 TT 次的 while 循环,其输出可以写成一个含 T+1T+1 个分支的条件语句,即 cond(π~,s0,…,sT)=∑t=0Tπ~tst\mathrm{cond}(\tilde{{\bm{\pi}}},{\bm{s}}_{0},\dots,{\bm{s}}_{T})=\sum_{t=0}^{T}\tilde{\pi}_{t}{\bm{s}}_{t} 。Figure 5.11: Computation graph of an unrolled truncated while loop. As in Fig. 5.5, we depict continuous variables in dense lines and discrete variables in dashed lines. The output of a while loop with at most TT iterations can be written as a conditional with T+1T+1 branches, cond(π~,s0,…,sT)=∑t=0Tπ~tst\mathrm{cond}(\tilde{{\bm{\pi}}},{\bm{s}}_{0},\dots,{\bm{s}}_{T})=\sum_{t=0}^{T}\tilde{\pi}_{t}{\bm{s}}_{t}.
例 5.10.1(用牛顿法计算平方根)。Example 5.10.1 (Computing the square root using Newton’s method).
计算实数 x>0x>0 的平方根 x\sqrt{x},可以转化为一个求根问题,并用牛顿法求解。从初始值 s0s_{0} 出发,迭代式为Computing the square root x\sqrt{x} of a real number x>0x>0 can be cast as a root finding problem, which we can solve using Newton’s method. Starting from an initialization s0s_{0}, the iterations read si+1:=g(si):=12(si+xsi).s_{i+1}\coloneqq g({\bm{s}}_{i})\coloneqq\frac{1}{2}\left(s_{i}+\frac{x}{s_{i}}\right). 为度量第 ii 次迭代的误差,我们可以定义To measure the error on iteration ii, we can define ε(si):=12(si2−x)2.\varepsilon(s_{i})\coloneqq\frac{1}{2}(s_{i}^{2}-x)^{2}. 于是,我们可以采用如下停止准则:As a stopping criterion, we can then use πi\displaystyle\pi_{i} :={1 if ε(si)≤τ0 otherwise \displaystyle\coloneqq\begin{cases}1&\text{ if }\varepsilon(s_{i})\leq\tau\\ 0&\text{ otherwise }\end{cases} =step(τ−ε(si)),\displaystyle=\mathrm{step}(\tau-\varepsilon(s_{i})), 其中 0<τ≪10<\tau\ll 1 是误差容限,step\mathrm{step} 是 Heaviside 阶跃函数。where 0<τ≪10<\tau\ll 1 is an error tolerance and step\mathrm{step} is the Heaviside step function.

5.10.3 马尔可夫链视角Markov chain perspective

给定函数 g ⁣:S→Sg\colon\mathcal{S}\to\mathcal{S} 与初始化 s0∈S{\bm{s}}_{0}\in\mathcal{S} ,while 循环的取值只能落在由 si=g(si−1){\bm{s}}_{i}=g({\bm{s}}_{i-1}) 所定义的离散取值集合 s0,s1,s2,…{\bm{s}}_{0},{\bm{s}}_{1},{\bm{s}}_{2},\ldots 中。若 while 循环无界,则该集合可能是可数无限的;若 while 循环保证会停止,则该集合是有限的。循环是从状态 si{\bm{s}}_{i} 转移到状态 si+1{\bm{s}}_{i+1} ,还是停留在 si{\bm{s}}_{i} ,由停止准则 πi∈{0,1}\pi_{i}\in\{0,1\} 决定。因此,为了对 while 循环的状态建模,我们可以考虑一个离散空间为 {s0,s1,s2,… }\{{\bm{s}}_{0},{\bm{s}}_{1},{\bm{s}}_{2},\dots\} 的马尔可夫链(该空间总可以与 {0,1,2,… }\{0,1,2,\dots\} 等同),其转移概率为Given the function g ⁣:S→Sg\colon\mathcal{S}\to\mathcal{S} and the initialization s0∈S{\bm{s}}_{0}\in\mathcal{S}, a while loop can only go through a discrete set of values s0,s1,s2,…{\bm{s}}_{0},{\bm{s}}_{1},{\bm{s}}_{2},\ldots defined by si=g(si−1){\bm{s}}_{i}=g({\bm{s}}_{i-1}). This set is potentially countably infinite if the while loop is unbounded, and finite if the while loop is guaranteed to stop. Whether the loop moves from the state si{\bm{s}}_{i} to the state si+1{\bm{s}}_{i+1}, or stays at si{\bm{s}}_{i}, is determined by the stopping criterion πi∈{0,1}\pi_{i}\in\{0,1\}. To model the state of the while loop, we can then consider a Markov chain with a discrete space {s0,s1,s2,… }\{{\bm{s}}_{0},{\bm{s}}_{1},{\bm{s}}_{2},\dots\}, which we can always identify with {0,1,2,… }\{0,1,2,\dots\}, with transition probabilities

P(St+1=si∣St=sj)=pi,j:={πi if i=j(1−πi) if i=j+10 otherwise ,\mathbb{P}(S_{t+1}={\bm{s}}_{i}|S_{t}={\bm{s}}_{j})=p_{i,j}\coloneqq\begin{cases}\pi_{i}&\text{ if }i=j\\ (1-\pi_{i})&\text{ if }i=j+1\\ 0&\text{ otherwise }\end{cases},

而初始状态为 S0=s0S_{0}={\bm{s}}_{0} 。这里,StS_{t} 是循环在第 tt 次迭代时的取值。注意,由于 πi∈{0,1}\pi_{i}\in\{0,1\} ,这些 pi,jp_{i,j} 个取值是“退化”的概率。不过,这一框架让我们能够自然地推广到 while 循环的光滑版本。为说明该框架,若 while 循环在 T=3T=3 处停止,则转移概率可以写成一个矩阵and initial state S0=s0S_{0}={\bm{s}}_{0}. Here, StS_{t} is the value at iteration tt of the loop. Note that since πi∈{0,1}\pi_{i}\in\{0,1\}, the pi,jp_{i,j} values are “degenerate” probabilities. However, this framework lets us generalize to a smooth version of the while loop naturally. To illustrate the framework, if the while loop stops at T=3T=3, the transition probabilities can be cast as a matrix

P:=(pi,j)i,j=0T:=s0s1s2s3s00100s10010s20001s30001.\mathbf{P}\coloneqq(p_{i,j})_{i,j=0}^{T}\coloneqq\begin{array}{ccccc}&{\bm{s}}_{0}&{\bm{s}}_{1}&{\bm{s}}_{2}&{\bm{s}}_{3}\\ {\bm{s}}_{0}&0&1&0&0\\ {\bm{s}}_{1}&0&0&1&0\\ {\bm{s}}_{2}&0&0&0&1\\ {\bm{s}}_{3}&0&0&0&1\\ \end{array}.

while 循环的输出 r{\bm{r}} 由状态停留在同一取值上的时刻决定The output r{\bm{r}} of the while-loop is determined by the time at which the state stays at the same value

I=min⁡{i∈{1,2,…} s.t. Si=Si−1}.I=\min\{i\in\{1,2,\ldots\}\ \text{s.t.}\ S_{i}=S_{i-1}\}.

注意,II 本身是一个随机变量,因为它由 SiS_{i} 这些变量定义。它被称为停时。于是该链的输出为Note that II itself is a random variable, as it is defined by the SiS_{i} variables. It is called a stopping time. The output of the chain is then

r\displaystyle{\bm{r}} =E[SI]\displaystyle=\mathbb{E}[S_{I}]
=∑i=1+∞P(I=i)E[Si∣I=i]\displaystyle=\sum_{i=1}^{+\infty}\mathbb{P}(I=i)\mathbb{E}[S_{i}|I=i]
=∑i=1+∞P(I=i)si−1\displaystyle=\sum_{i=1}^{+\infty}\mathbb{P}(I=i){\bm{s}}_{i-1}
=∑i=1+∞∏j=0i−2(1−πj)πi−1si−1\displaystyle=\sum_{i=1}^{+\infty}\prod_{j=0}^{i-2}(1-\pi_{j})\pi_{i-1}{\bm{s}}_{i-1}
=∑i=0+∞∏j=0i−1(1−πj)πisi.\displaystyle=\sum_{i=0}^{+\infty}\prod_{j=0}^{i-1}(1-\pi_{j})\pi_{i}{\bm{s}}_{i}.

由于停时无法事先得知,对 ii 的求和从 00 到 ∞\infty 。然而,若我们在停止准则中强制 while 循环运行的迭代次数不超过 TT ,即令Because the stopping time is not known ahead of time, the sum over ii goes from 00 to ∞\infty. However, if we enforce in the stopping criterion that the while loop runs no longer than TT iterations, by setting

πi:=or(f(si),eq(i,T))∈{0,1},\pi_{i}\coloneqq\text{or}(f({\bm{s}}_{i}),\mathrm{eq}(i,T))\in\{0,1\},

我们便自然地重新得到此前通过展开 while 循环所得到的表达式,we then naturally recover the expression found by unrolling the while loop before,

r\displaystyle{\bm{r}} =E[SI]=∑i=0T∏j=0i−1(1−πj)πisi.\displaystyle=\mathbb{E}[S_{I}]=\sum_{i=0}^{T}\prod_{j=0}^{i-1}(1-\pi_{j})\pi_{i}{\bm{s}}_{i}.

例如,当 T=3T=3 时,转移概率矩阵为For example, with T=3T=3, the transition probability matrix is

P=s0s1s2s3s0π01−π000s10π11−π10s200π21−π2s30001.\mathbf{P}=\begin{array}{ccccc}&{\bm{s}}_{0}&{\bm{s}}_{1}&{\bm{s}}_{2}&{\bm{s}}_{3}\\ {\bm{s}}_{0}&\pi_{0}&1-\pi_{0}&0&0\\ {\bm{s}}_{1}&0&\pi_{1}&1-\pi_{1}&0\\ {\bm{s}}_{2}&0&0&\pi_{2}&1-\pi_{2}\\ {\bm{s}}_{3}&0&0&0&1\\ \end{array}.

平滑的 while 循环Smoothed while loops

借助这一框架,只要我们平滑掉谓词,甚至可以通过 while 循环的停止准则进行反向传播。例如,我们看到例 5.10.1 中的停止准则为 f(si)=step(τ−ε(si))f({\bm{s}}_{i})=\mathrm{step}(\tau-\varepsilon({\bm{s}}_{i})) ,因此With the help of this framework, we can backpropagate even through the while loop’s stopping criterion, provided that we smooth out the predicate. For example, we saw that the stopping criterion in Example 5.10.1 is f(si)=step(τ−ε(si))f({\bm{s}}_{i})=\mathrm{step}(\tau-\varepsilon({\bm{s}}_{i})) and therefore

πi:=or(f(si),eq(i,T))∈{0,1}.\pi_{i}\coloneqq\text{or}(f({\bm{s}}_{i}),\mathrm{eq}(i,T))\in\{0,1\}.

由于 step\mathrm{step} 函数的作用,while 循环关于 τ\tau 的导数恒为 00,这与 if-else 语句的情形相同。若把停止准则改为 f(si)=sigmoid(τ−ε(si))f({\bm{s}}_{i})=\mathrm{sigmoid}(\tau-\varepsilon({\bm{s}}_{i})),则有(回想一下,or\mathrm{or} 在 [0,1]×[0,1][0,1]\times[0,1] 上是良定义的)Due to the step\mathrm{step} function, the derivative of the while loop with respect to τ\tau will always be 00, just like it was the case for if-else statements. If we change the stopping criterion to f(si)=sigmoid(τ−ε(si))f({\bm{s}}_{i})=\mathrm{sigmoid}(\tau-\varepsilon({\bm{s}}_{i})), we then have (recall that or\mathrm{or} is well defined on [0,1]×[0,1][0,1]\times[0,1])

πi:=or(f(si),eq(i,T))∈[0,1].\pi_{i}\coloneqq\mathrm{or}(f({\bm{s}}_{i}),\mathrm{eq}(i,T))\in[0,1].

取 sigmoid\mathrm{sigmoid} 时,我们得到更具信息量的导数。特别地,当 sigmoid=logistic\mathrm{sigmoid}=\mathrm{logistic} 时,关于 τ\tau 的导数恒不为零。平滑后的输出仍如前述表示为期望With sigmoid\mathrm{sigmoid}, we obtain more informative derivatives. In particular, with sigmoid=logistic\mathrm{sigmoid}=\mathrm{logistic}, the derivatives w.r.t. τ\tau are always non-zero. The smoothed output is expressed as before as the expectation

r=E[SI]=∑i=0T∏j=0i−1(1−πj)πisi{\bm{r}}=\mathbb{E}[S_{I}]=\sum_{i=0}^{T}\prod_{j=0}^{i-1}(1-\pi_{j})\pi_{i}{\bm{s}}_{i}

其中where

πi:=sigmoid(τ−ε(si)).\pi_{i}\coloneqq\mathrm{sigmoid}(\tau-\varepsilon({\bm{s}}_{i})).

我们也可以不强制迭代 TT 次,而是在停止概率足够高时停止 [153],前提是停止概率收敛到 11。Instead of enforcing a number TT of iterations, it is also possible to stop when the probability of stopping becomes high enough [153], assuming that the probability of stopping converges to 11.

5.11 小结5.11 Summary

  • •

    对于条件语句,我们已经看到:在谓词固定的前提下,对分支变量求导并无问题。For conditionals, we saw that differentiating through the branch variables is not problematic given a fixed predicate.

  • •

    然而对于谓词变量,我们看到必须引入可微松弛,才能避免导数为零。However, for the predicate variable, we saw that a differentiable relaxation is required to avoid null derivatives.

  • •

    我们以原则性的方式引入了软比较运算符,所借助的是随机过程视角,以及逻辑运算符的连续扩展。We introduced soft comparison operators in a principled manner, using a stochastic process perspective, as well as the continuous extension of logical operators.

  • •

    for 循环与 scan 定义的都是有效的计算图,因为它们的迭代次数事先已经确定。前馈网络与 RNN 则可分别视为参数化的 for 循环与 scan。For loops and scan define valid computational graphs, as their number of iterations is fixed ahead of time. Feedforward networks and RNNs can be seen as parameterized for loops and scan, respectively.

  • •

    与 for 循环和 scan 不同,while 循环的迭代次数事先未知,甚至可能无穷。不过,展开的 while 循环定义的是有效的有向无环图。借助马尔可夫链视角,我们给出了一种有原则的方法,可以对 while 循环的停止准则进行求导。Unlike for loops and scan, the number of iterations of while loops is not known ahead of time and may even be infinite. However, unrolled while loops define valid directed acyclic graphs. We defined a principled way to differentiate through the stopping criterion of a while loop, thanks to a Markov chain perspective.