第 3 章 概率学习Chapter 3 Probabilistic learning
本章回顾如何进行概率学习,并介绍指数族分布,因为它们在本书中起着关键作用。In this chapter, we review how to perform probabilistic learning. We also introduce exponential family distributions, as they play a key role in this book.
3.1 概率分布3.1 Probability distributions
3.1.1 离散概率分布Discrete probability distributions
集合 上的离散概率分布由其概率质量函数(PMF) 给定。于是, 的概率定义为A discrete probability distribution over a set is specified by its probability mass function (PMF) . The probability of is then defined by
其中 表示随机变量。当 服从分布 时,我们记作 (这里略微滥用记号:用同一个字母 同时表示分布与 PMF)。于是, 的期望为(其中 ,)where denotes a random variable. When follows a distribution , we write (with some abuse of notation, we use the same letter to denote the distribution and the PMF). The expectation of , where and , is then
其方差(一维变量情形)为its variance (for one-dimensional variables) is
而其众数为and its mode is
集合 上两个离散分布之间的 Kullback-Leibler(KL)散度(亦称相对熵),在相应 PMF 分别为 与 时,是如下定义的统计“距离”The Kullback-Leibler (KL) divergence (also known as relative entropy) between two discrete distributions over , with associated PMFs and , is the statistical “distance” defined by
3.1.2 连续概率分布Continuous probability distributions
集合 上的连续概率分布由其概率密度函数(PDF) 给定。于是, 的概率为A continuous probability distribution over is specified by its probability density function (PDF) . The probability of is then
期望、方差与 KL 散度的定义均与离散情形类似,只需把 换作 。具体而言, 的期望为The expectation, variance and KL divergence are defined analogously to the discrete setting, simply replacing with . Specifically, the expectation of is
方差为the variance is
而 KL 散度为and the KL divergence is
众数则定义为 PDF 的 argmax。The mode is defined as the argmax of the PDF.
当 时,还可定义累积分布函数(CDF)When , we can also define the cumulative distribution function (CDF)
于是, 落入半闭区间 内的概率为The probability of lying in the semi-closed interval is then
3.2 最大似然估计3.2 Maximum likelihood estimation
3.2.1 负对数似然Negative log-likelihood
我们已经看到,集合 上的概率分布由 给定:对离散变量它称为概率质量函数(PMF),对连续变量则称为概率密度函数(PDF)。实际中,生成数据的真实分布 未知,我们希望用一个带参数 的分布 来近似它。现给定一组有限的独立同分布观测 ,应如何将 拟合到数据?这可以通过最大化数据的似然来实现,即我们求解We saw that a probability distribution over is specified by , which is called the probability mass function (PMF) for discrete variables or the probability density function (PDF) for continuous variables. In practice, the true distribution generating the data is unknown and we wish to approximate it with a distribution , with parameters . Given a finite set of i.i.d. observations , how do we fit to the data? This can be done by maximizing the likelihood of the data, i.e., we seek to solve
这称为最大似然估计(MLE)。由于 函数单调递增,此举等价于最小化负对数似然,即我们有This is known as maximum likelihood estimation (MLE). Because the function is monotonically increasing, this is equivalent to minimizing the negative log-likelihood, i.e., we have
例 3.2.1(正态分布的最大似然估计)。Example 3.2.1 (MLE for the normal distribution).
3.2.2 关于 Kullback-Leibler 散度的一致性Consistency w.r.t. the Kullback-Leibler divergence
众所周知,MLE 在 Kullback-Leibler 散度意义下是一致的。也就是说,记真实分布为 ,并且It is well-known that the MLE is consistent, in the sense of the Kullback-Leibler divergence. That is, denoting the true distribution and
其中,where
那么,对观测取期望后有 ,当 时成立。这一结论可通过使用then in expectation over the observations, as . This can be seen by using
以及大数定律得到。and the law of large numbers.
3.3 概率监督学习3.3 Probabilistic supervised learning
3.3.1 条件概率分布Conditional probability distributions
在机器学习中,很多时候我们希望针对某个输入 定义条件概率 ,而不是针对某个 定义概率 。这可以通过归约为无条件概率分布来实现,Many times in machine learning, instead of a probability for some , we wish to define a conditional probability , for some input . This can be achieved by reduction to an unconditional probability distribution,
其中where
而 是一个带有模型参数 的模型函数。也就是说, 并非从 到 的确定性函数,而是从 到 的函数,其中后者是与输入相关联的输出分布所允许的分布参数集合。and is a model function with model parameters . That is, rather than being a deterministic function from to , is a function from to , the set of permissible distribution parameters of the output distribution associated with the input.
我们要强调, 可以是单个参数,也可以是一组参数的集合。例如,在 伯努利分布中,;而在一元正态分布中,。We emphasize that could be a single parameter or a collection of parameters. For instance, in the Bernoulli distribution, , while in the univariate normal distribution, .
在 3.4 节以及本书其余部分,当 是指数族分布的典范参数时,我们也会使用记号 来代替 。In Section 3.4 and throughout this book, we will also use the notation instead of when are the canonical parameters of an exponential family distribution.
3.3.2 推断Inference
这种概率方法的主要优势在于,我们的预测模型比仅仅学习一个从 到 的函数要丰富得多。现在我们可以获得 中所有可能结果的整个分布,并计算各种统计量:The main advantage of this probabilistic approach is that our prediction model is much richer than if we just learned a function from to . We now have access to the whole distribution over possible outcomes in and can compute various statistics:
- •
概率: 或 ,Probability: or ,
- •
期望:对于某个函数 ,,Expectation: for some function ,
- •
方差:,Variance: ,
- •
众数:。Mode: .
现在我们回顾一些概率分布,它们适用于二分类、多分类、回归、多元回归和整数回归。在下文中,为使记号更简洁,我们省略对 的依赖。We now review probability distributions useful for binary classification, multiclass classification, regression, multivariate regression, and integer regression. In the following, to make the notation more lightweight, we omit the dependence on .
3.3.3 二分类Binary classification
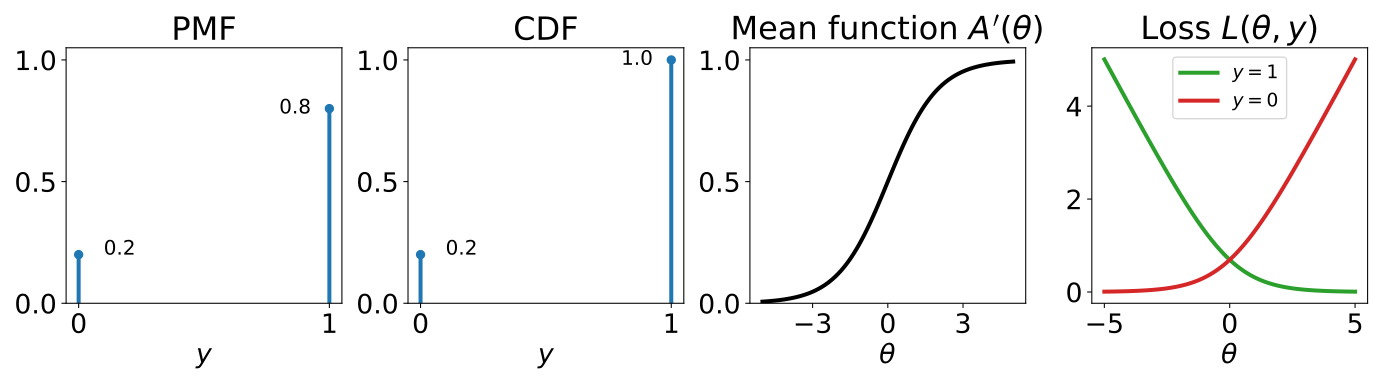
对于二值结果,其中 ,我们可以使用一个伯努利分布,其参数为For binary outcomes, where , we can use a Bernoulli distribution with parameter
当随机变量 服从参数为 的伯努利分布时,我们记作When a random variable is distributed according to a Bernoulli distribution with parameter , we write
该分布的概率质量函数为The PMF of this distribution is
伯努利分布是单次试验的二项分布。由于 ,概率质量函数可改写为The Bernoulli distribution is a binomial distribution with a single trial. Since , the PMF can be rewritten as
其均值为The mean is
其方差为and the variance is
使用 sigmoid 进行参数化Parameterization using a sigmoid
由于 伯努利分布的参数 需属于 ,我们通常使用 sigmoid 函数(4.4.3 节),例如以 logistic 函数作为输出层:Since the parameter of a Bernoulli distribution needs to belong to , we typically use a sigmoid function (Section 4.4.3), such as a logistic function as the output layer:
其中 例如是神经网络,且where is for example a neural network and
当 关于 为线性时,这称为二分类 logistic 回归。When is linear in , this is known as binary logistic regression.
注 3.3.1(与 logistic 分布的联系)。Remark 3.3.1 (Link with the logistic distribution).
3.3.4 多分类Multiclass classification
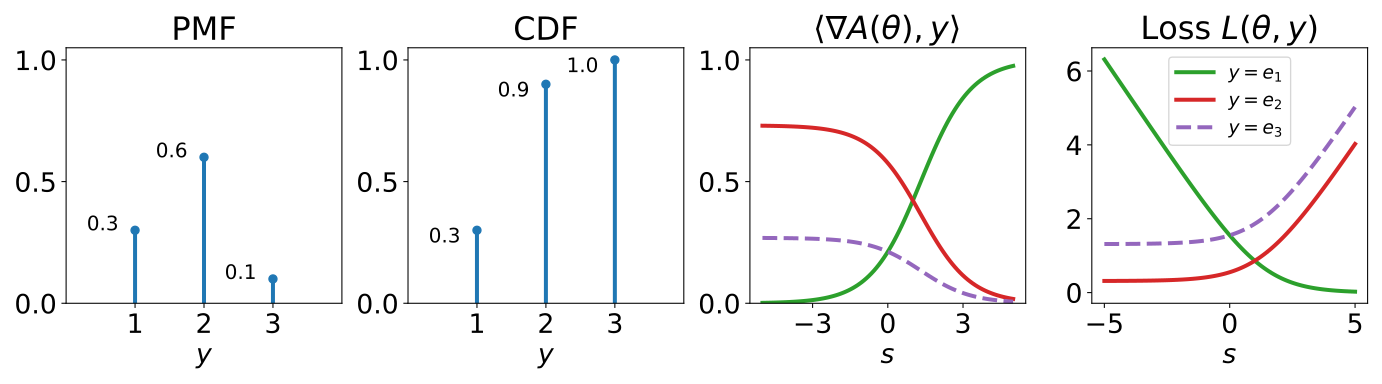
对于有 种可能取值的分类结果,其中 ,我们可以使用一个分类分布,其参数为For categorical outcomes with possible choices, where , we can use a categorical distribution with parameters
的 分类分布,其中我们定义概率单纯形where we define the probability simplex
即有效离散概率分布的集合。当 服从参数为 的分类分布时,我们记作i.e., the set of valid discrete probability distributions. When follows a categorical distribution with parameter , we write
分类分布的概率质量函数为The PMF of the categorical distribution is
其中where
是坐标 的标准基向量。is the standard basis vector for the coordinate .
由于 是 分类变量,计算 的期望并无意义,但我们可以计算 的期望,Since is a categorical variable, it does not make sense to compute the expectation of but we can compute that of ,
因此,与 伯努利分布的情形相同,此处均值与概率分布(由向量 表示)也是一致的。Therefore, as was also the case for the Bernoulli distribution, the mean and the probability distribution (represented by the vector ) are the same in this case.
使用 softargmax 进行参数化Parameterization using a softargmax
分类分布 的参数向量必须属于 ,因此我们通常以 softargmax 作为输出层:Since the parameter vector of a categorical distribution needs to belong to , we typically use a softargmax as the output layer:
其中 例如是一个神经网络;并且where is for example a neural network and
softargmax 的输出落在 的相对内部,即 。也就是说,生成的概率始终严格为正。分类分布是试验次数为一的多项分布。因而,当 关于 为线性时,这种做法被称为多分类 logistic 回归或多项 logistic 回归;不过严格说来,多项分布可采用不止一次试验。The output of the softargmax is in the relative interior of , . That is, the produced probabilities are always strictly positive. The categorical distribution is a multinomial distribution with a single trial. When is linear in , this is therefore known as multiclass or multinomial logistic regression, though strictly speaking a multinomial distribution could use more than one trial.
3.3.5 回归Regression
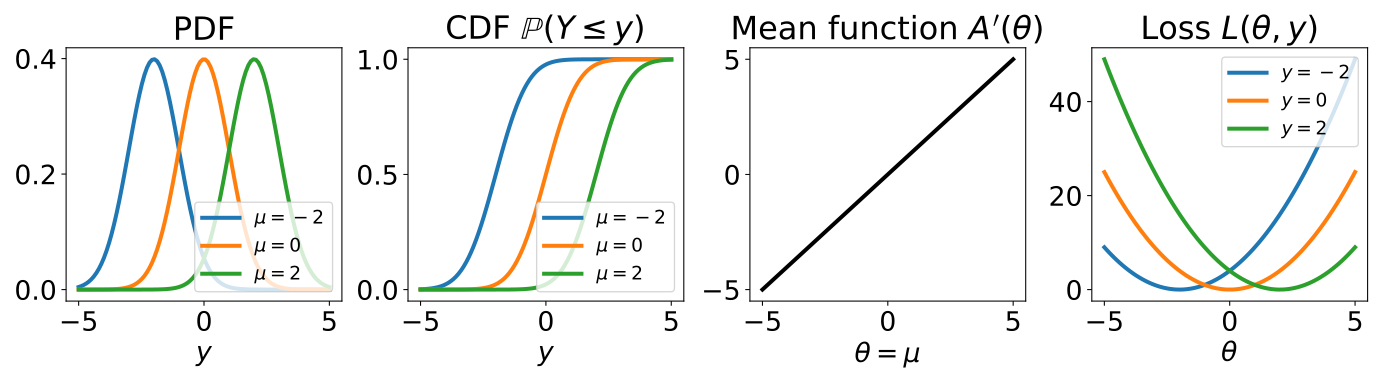
对于实值结果,其中 ,可供选择的方案之一是采用具有如下参数的正态分布:For real outcomes, where , we can use, among other choices, a normal distribution with parameters
其中 为均值参数, 为标准差参数。若 服从参数为 的正态分布,则记作where is the mean parameter and is the standard deviation parameter. When follows a normal distribution with parameters , we write
其概率密度函数为The PDF is
其期望为The expectation is
概率视角的优点之一在于,我们并不局限于预测均值,还可以计算累积分布函数One advantage of the probabilistic perspective is that we are not limited to predicting the mean. We can also compute the CDF
这里用到了误差函数where we used the error function
该函数在多数科学计算库中均可调用,例如 SciPy [203]。我们也可将其写作This function is available in most scientific computing libraries, such as SciPy [203]. We can also write
其中where
| (3.1) |
为标准高斯分布(均值为零、单位方差)的累积分布函数。借助累积分布函数,我们还能方便地得到is the CDF of the standard Gaussian distribution (with zero mean and unit variance). From the CDF, we also easily obtain
参数化Parameterization
回归中通常由模型输出均值,而标准差 保持固定(一般设为 )。由于 不受约束,我们可以直接令Typically, in regression, the mean is output by a model, while the standard deviation is kept fixed (typically set to ). Since is unconstrained, we can simply set
其中 例如是一个神经网络。也就是说, 的输出即为该分布的均值,where is for example a neural network. That is, the output of is the mean of the distribution,
我们也可以用 预测 或 ,如上所示。We can also use to predict or , as shown above.
3.3.6 多元回归Multivariate regression
更一般地,对于多变量结果,其中 ,我们可以采用如下参数的多元正态分布:More generally, for multivariate outcomes, where , we can use a multivariate normal distribution with parameters
其中 为均值, 为协方差矩阵。若 服从参数为 的多元正态分布,则记作where is the mean and is the covariance matrix. When follows a multivariate normal distribution with parameters , we write
概率密度函数为The PDF is
使用对角协方差矩阵,等价于对每个 分别使用 个独立的正态分布,其中 。其期望为Using a diagonal covariance matrix is equivalent to using independent normal distributions for each , for . The expectation is
参数化Parameterization
通常,在多元回归中,均值由模型输出,而协方差矩阵保持固定(通常设为单位矩阵)。由于 同样不受约束,我们只需令Typically, in multivariate regression, the mean is output by a model, while the covariance matrix is kept fixed (typically set to the identity matrix). Since is again unconstrained, we can simply set
更一般地,我们可以参数化函数 ,使其同时输出均值 和协方差矩阵 ,即More generally, we can parametrize the function so as to output both the mean and the covariance matrix , i.e.,
函数 的设计必须保证 对称且半正定。这一点很容易实现,例如,可对某个矩阵 参数化 。The function must be designed such that is symmetric and positive semi-definite. This is easy to achieve for instance by parametrizing for some matrix .
3.3.7 整数回归Integer regression
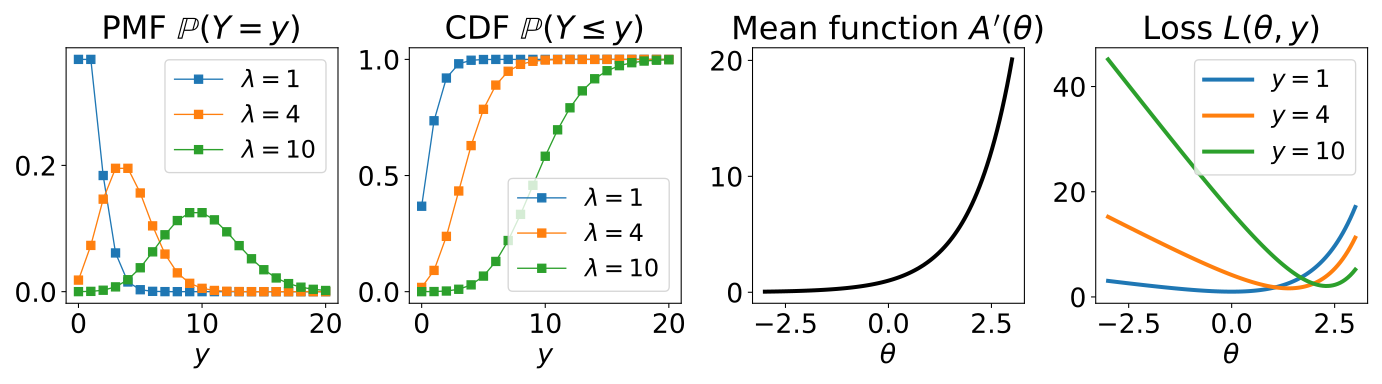
对于取值为整数的结果,即 ,我们可以选用均值参数为 的 Poisson 分布,当然也可作其他选择。当 服从参数为 的 Poisson 分布时,我们记作For integer outcomes, where , we can use, among other choices, a Poisson distribution with mean parameter . When follows a Poisson distribution with parameter , we write
其概率质量函数为The PMF is
它表示在一段时间区间内发生 个事件的概率。当可能事件数量很大、而每个事件都很罕见时,常使用 Poisson 分布。It is the probability of events occurring in an interval of time. The Poisson distribution is frequently used when there is a large number of possible events, each of which is rare.
其累积分布函数为The CDF is
Poisson 分布意味着离散指数(方差与均值之比)为 ,因为The Poisson distribution implies that the index of dispersion (the ratio between variance and mean) is , since
当这一假设不再适用时,可以使用广义 Poisson 分布 [176]。When this assumption is inappropriate, one can use generalized Poisson distributions [176].
使用指数函数进行参数化Parameterization using an exponential
由于 Poisson 分布的参数 必须严格为正,我们通常使用指数函数作为输出层:Since the parameter of a Poisson distribution needs to be strictly positive, we typically use an exponential function as output layer:
其中 。where .
3.3.8 损失函数Loss functions
下面讨论如何从输入—输出对 中学习模型参数 。We now discuss how to learn the model parameters from input-output pairs .
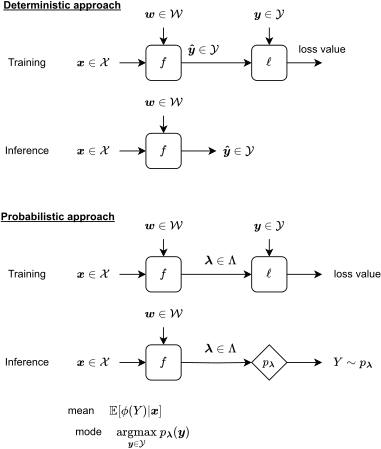
确定性方法与概率方法Deterministic vs. probabilistic approaches
在确定性方法中,若采用映射 ,我们可以构造如下形式的目标函数In a deterministic approach, if we used a mapping , we could formulate an objective function of the form
其中 是损失函数。遗憾的是,若 是离散输出空间(分类情形即如此),则 通常是不连续的,从而令优化变得困难。where is a loss function. Unfortunately, would be typically discontinuous if is a discrete output space (as is the case in classification), making optimization difficult.
相比之下,在概率方法中,我们用映射 得到分布参数,并可构造如下形式的目标:In contrast, in the probabilistic approach, we use a mapping to distribution parameters, and we can formulate an objective of the form
其中 。这通常是连续目标,因为 通常是连续集,且即便 是离散集 上的分布, 也会关于 连续变化。换言之,概率方法之所以强大,不仅在于它允许我们进行推断(概率、期望、方差、众数),还在于它允许我们构造连续且通常可微的目标函数!where . This is typically a continuous objective, since is typically a continuous set and varies continuously w.r.t. even if is a distribution over a discrete set . In other words, the probabilistic approach is not only powerful for the inference it allows us to do (probability, expectation, variance, mode), but also because it allows us to formulate a continuous and typically differentiable objective function!
图 3.5 对此进行了总结。This is summarized in Fig. 3.5.
负对数似然Negative log-likelihood
在 3.3.1 节简要回顾的条件设定下,我们可以使用最大似然估计(MLE)来估计 的模型参数 。给定一组输入—输出对 ,我们选取使数据似然最大化的模型参数,In the conditional setting briefly reviewed in Section 3.3.1, we can use maximum likelihood estimation (MLE) to estimate the model parameters of . Given a set of input-output pairs , we choose the model parameters that maximize the likelihood of the data,
其中where
同样,这等价于最小化负对数似然,Again, this is equivalent to minimizing the negative log-likelihood,
在上述记号下,这对应于定义如下损失函数:In the notation above, this corresponds to defining the loss function
恢复出众所周知的损失函数。Recovering well-known loss functions
有趣的是,MLE 使我们能够推导出若干流行的损失函数。Interestingly, MLE allows us to recover several popular loss functions.
- •
对于参数为 的 伯努利分布,其中 ,我们有For the Bernoulli distribution with parameter , where , we have
即二分类 logistic 损失函数。which is the binary logistic loss function.
- •
对于参数为 的 分类分布,其中 ,我们有For the categorical distribution with parameters , where , we have
即多分类 logistic 损失函数,也称为交叉熵损失。which is the multiclass logistic loss function, also known as cross-entropy loss.
- •
对于均值为 、方差固定为 的正态分布,我们有For the normal distribution with mean and fixed variance , we have
在相差一个常数且方差为单位方差的意义下,这就是平方损失函数。which is, up to a constant and with unit variance, the squared loss function.
- •
对于均值为 的 Poisson 分布,其中 ,我们有For the Poisson distribution with mean , where , we have
即 Poisson 损失函数。对于 ,该损失函数关于 与 是凸的。which is the Poisson loss function. The loss function is convex w.r.t. and for .
3.4 指数族分布3.4 Exponential family distributions
3.4.1 定义Definition
指数族是一类概率分布,其 PMF 或 PDF 可以写成如下形式:The exponential family is a class of probability distributions, whose PMF or PDF can be written in the form
其中 是分布的自然参数或典范参数。函数 称为基测度;函数 为充分统计量,它承载了关于 的全部信息,并用于将 嵌入向量空间。函数 称为对数配分函数或对数归一化函数(详见下文)。我们在 3.3 节中回顾的所有分布均属于指数族。这里我们略微滥用了记号:以 表示原始形式的分布,以 表示指数族形式的分布。正如我们将看到的,由 可得 ,反之亦然。下文将说明如何将分布改写为指数族形式。where are the natural or canonical parameters of the distribution. The function is known as the base measure. The function is the sufficient statistic: it holds all the information about and is used to embed in a vector space. The function is the log-partition or log-normalizer (see below for details). All the distributions we reviewed in Section 3.3 belong to the exponential family. With some abuse of notation, we use for the distribution in original form and for the distribution in exponential family form. As we will see, we can go from to and vice versa. We illustrate how to rewrite a distribution in exponential family form below.
例 3.4.1(伯努利分布)。Example 3.4.1 (Bernoulli distribution).
表 3.1 将前述各分布改写为指数族形式。该列表并不详尽:指数族中的分布远不止这些![11]We rewrite the previously-described distributions in exponential family form in Table 3.1. This list is non-exhaustive: there are many more distributions in the exponential family! [11]
| BernoulliBernoulli | CategoricalCategorical | |
| 1 | 1 | |
| 正态分布(仅位置)Normal (location only) | 正态分布(位置—尺度)Normal (location-scale) | |
| 多元正态分布Multivariate normal | PoissonPoisson | |
3.4.2 对数配分函数The log-partition function
为简明起见,本节讨论集中于离散变量。不过,本节所述结果对连续变量同样成立 [206]。对数配分函数 即分布归一化因子的对数,We focus our discussion in this section on discrete variables for simplicity. However, the results stated in this section also hold for continuous variables [206]. The log-partition function is the logarithm of the distribution’s normalization factor,
我们记有效参数集为We denote the set of valid parameters
可方便地将 改写为We can conveniently rewrite as
其中定义了仿射映射where we defined the affine map
由于 是凸函数 与仿射映射 的复合,我们立即可得如下命题。Since is the composition of , a convex function, and of , an affine map, we immediately obtain the following proposition.
命题 3.4.2(对数配分函数的凸性)。Proposition 3.4.2 (Convexity of the log-partition).
对数配分函数的一个主要性质是:其梯度等于 在 下的期望。A major property of the log-partition function is that its gradient coincides with the expectation of according to .
命题 3.4.3(对数配分函数的梯度)。Proposition 3.4.3 (Gradient of the log-partition).
证明 3.4.4。Proof 3.4.4.
该结果直接由下式得出The result follows directly from
因此,梯度 常被称为均值函数。可达均值的集合 定义为The gradient is therefore often called the mean function. The set of achievable means is defined by
其中 为 的凸包, 为 上有效概率分布的集合。where is the convex hull of and is the set of valid probability distributions over .
类似地,Hessian 矩阵 等于 在 下的协方差矩阵 [206,第 3 章]。Similarly, the Hessian coincides with the covariance matrix of according to [206, Chapter 3].
当指数族为极小指数族,即参数 能够唯一确定分布时,已知 是从 到 的一一映射。也就是说, 且 。When the exponential family is minimal, which means that the parameters uniquely identify the distribution, it is known that is a one-to-one mapping from to . That is, and .
3.4.3 最大熵原理Maximum entropy principle
假设我们观测到若干观测值 的经验均值 。如何找到一个能达到该均值的概率分布?显然,这样的分布未必唯一。在所有可能的分布中做出选择,一种办法是运用最大熵原理。我们将 Shannon 熵定义为Suppose we observe the empirical mean of some observations . How do we find a probability distribution achieving this mean? Clearly, such a distribution may not be unique. One way to choose among all possible distributions is by using the maximum entropy principle. Let us define the Shannon entropy by
对离散变量,以及通过for discrete variables and by
对连续变量。它刻画了 中“不确定性”的高低,也就是说,分布为均匀分布时它取最大值。于是,满足一阶矩条件(即其期望与经验均值相符)的最大熵分布为for continuous variables. This captures the level of “uncertainty” in , i.e., it is maximized when the distribution is uniform. Then, the maximum entropy distribution satisfying the first-order moment condition (i.e., whose expectation matches the empirical mean) is
可以证明,最大熵分布必然属于指数族,其充分统计量由 定义,而其典范参数 与上述约束的拉格朗日乘子相一致 [206,第 3.1 节]。It can be shown that the maximum entropy distribution is necessarily in the exponential family with sufficient statistic defined by and its canonical parameters coincide with the Lagrange multipliers of the above constraint [206, Section 3.1].
3.4.4 最大似然估计Maximum likelihood estimation
如同第 3.2 节,为了将指数族分布的参数 拟合到若干独立同分布的观测 ,我们可以采用 MLE 原则,即As in Section 3.2, to fit the parameters of an exponential family distribution to some i.i.d. observations , we can use the MLE principle, i.e.,
所幸,对于指数族分布,对数概率/密度具有格外简单的形式。Fortunately, for exponential family distributions, the log probability/density enjoys a particularly simple form.
命题 3.4.5(负对数似然)。Proposition 3.4.5 (Negative log-likelihood).
由命题 3.4.2 可知 是凸的。有趣的是,这里的梯度正是模型下 的期望与观测到的 之间的残差。因此,指数族分布的负对数似然可以视为在进行一阶矩匹配。It follows from Proposition 3.4.2 that is convex. Interestingly, we see that the gradient is the residual between the expectation of according to the model and the observed . Therefore, the negative log-likelihood of an exponential family distribution can be seen as performing first moment matching.
3.4.5 使用指数族的概率学习Probabilistic learning with exponential families
在概率监督学习设定中,我们希望估计形如 的条件分布。给定模型函数 (例如神经网络),定义这类条件分布的一种常见做法是将其归约为无条件设定,In the supervised probabilistic learning setting, we wish to estimate a conditional distribution of the form . Given a model function , such as a neural network, a common approach for defining such a conditional distribution is by reduction to the unconditional setting,
换言之, 的作用是在给定某个输入 时产生 的参数。它是从 到 的函数。注意, 的设计必须使其输出落在In other words, the role of is to produce the parameters of given some input . It is a function from to . Note that must be designed such that it produces an output in
很多时候, 就是整个 ,但情况并非总是如此。例如,正如前文所述,对于多元正态分布,当 时,我们需要确保 为半正定矩阵。Many times, will be the entire but this is not always the case. For instance, as we previously discussed, for a multivariate normal distribution, where , we need to ensure that is a positive semidefinite matrix.
训练Training
给定输入—输出对 ,我们接下来通过最小化负对数似然,来求取 的参数 :Given input-output pairs , we then seek to find the parameters of by minimizing the negative log-likelihood
其中 。对于指数族分布, 虽是 的凸函数,但我们要强调:当 为非线性函数(例如神经网络)时, 通常是 的非凸函数。where . While is a convex function of for exponential family distributions, we emphasize that is typically a nonconvex function of , when is a nonlinear function, such as a neural network.
推断Inference
通过最小化上述目标函数求得 之后,我们可用若干策略对新输入 进行推断。Once we have found by minimizing the objective function above, there are several possible strategies to perform inference for a new input .
- •
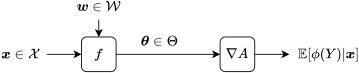
期望。若目标是计算 的期望,可以使用 。也就是说,先用 算出与 对应的分布参数,再用 求出均值。当 关于 为线性时,复合 便称为广义线性模型。图 3.6 说明了这一点。Expectation. When the goal is to compute the expectation of , we can use . That is, we compute the distribution parameters associated with by and then we compute the mean by . When is linear in , the composition is called a generalized linear model. This is illustrated in Fig. 3.6.
- •
概率。若目标是计算某个 的概率,可以先用 算出与 对应的分布参数,再计算 。在 分类分布(伯努利分布是其特例)这一特殊情形下,我们再次指出:均值与概率向量是重合的:Probability. When the goal is to compute the probability of a certain , we can compute the distribution parameters associated with by and then we can compute . In the particular case of the categorical distribution (of which the Bernoulli distribution is a special case), we point out again that the mean and the probability vector coincide:
- •
其他统计量。若目标是计算方差、CDF 等其他量,可以先将自然参数 转换为原始的分布参数 (示例见表 3.1)。随后,便可借助适用于原始形式分布的既有公式,计算出所需的量。Other statistics. When the goal is to compute other quantities, such as the variance or the CDF, we can convert the natural parameters to the original distribution parameters (see Table 3.1 for examples). Then, we can use established formulas for the distribution in original form, to compute the desired quantities.
3.5 小结3.5 Summary
- •
我们回顾了离散概率分布与连续概率分布。We reviewed discrete and continuous probability distributions.
- •
我们了解了如何依据最大似然估计(MLE)原理用数据拟合分布参数,并了解了它与 Kullback-Leibler 散度的联系。We saw how to fit distribution parameters to data using the maximum likelihood estimation (MLE) principle and saw its connection with the Kullback-Leibler divergence.
- •
我们看到,可以通过设计一个从 到分布参数 的模型函数,而不是设计一个从输入空间 到输出空间 的模型函数,来进行概率监督学习。Instead of designing a model function from the input space to the output space , we saw that we can perform probabilistic supervised learning by designing a model function from to distribution parameters .
- •
利用由此得到的参数化条件分布,我们不仅可以计算输出的概率,还可以计算输出的均值、方差等各种统计量。Leveraging the so-obtained parametric conditional distribution then allowed us to compute, not only output probabilities, but also various statistics such as the mean and the variance of the outputs.
- •
我们回顾了指数族——它是对众多分布的一种有原则的推广,我们也看到它与最大熵原理紧密相连。We reviewed the exponential family, a principled generalization of numerous distributions, which we saw is tightly connected with the maximum entropy principle.
- •
重要的是,本章所述方法产生的都是完全有效的计算图,这意味着我们可以将它们与神经网络结合,并使用自动微分来计算其导数。Importantly, the approaches described in this chapter produce perfectly valid computation graphs, meaning that we can combine them with neural networks and we can use automatic differentiation, to compute their derivatives.