目录图模型中的推断即求导

第 10 章 图模型中的推断即求导Chapter 10 Inference in graphical models as differentiation

图模型刻画随机变量之间的依赖关系,从而决定其联合概率分布如何分解。本章回顾图模型的关键概念及其与求导之间的联系,并在叙述过程中与计算链、计算图进行类比。A graphical model specifies how random variables depend on each other and therefore determines how their joint probability distribution factorizes. In this chapter, we review key concepts in graphical models and how they relate to differentiation, drawing in the process analogies with computation chains and computation graphs.

10.1 概率的链式法则10.1 Chain rule of probability

概率的链式法则是概率论中计算事件联合概率的基本法则。当只有两个事件 A1A_{1} 与 A2A_{2} 时,它退化为乘积法则The chain rule of probability is a fundamental law in probability theory for computing the joint probability of events. In the case of only two events A1A_{1} and A2A_{2}, it reduces to the product rule

P(A1∩A2)=P(A2∣A1)P(A1).\mathbb{P}(A_{1}\cap A_{2})=\mathbb{P}(A_{2}|A_{1})\mathbb{P}(A_{1}).

对于两个离散随机变量 S1S_{1} 与 S2S_{2} ,取事件 A1:={S1=s1}A_{1}\coloneqq\{S_{1}={\bm{s}}_{1}\} 与 A2:={S2=s2}A_{2}\coloneqq\{S_{2}={\bm{s}}_{2}\} ,乘积法则即化为For two discrete random variables S1S_{1} and S2S_{2}, using the events A1:={S1=s1}A_{1}\coloneqq\{S_{1}={\bm{s}}_{1}\} and A2:={S2=s2}A_{2}\coloneqq\{S_{2}={\bm{s}}_{2}\}, the product rule becomes

P(S1=s1,S2=s2)=P(S2=s2∣S1=s1)P(S1=s1).\mathbb{P}(S_{1}={\bm{s}}_{1},S_{2}={\bm{s}}_{2})=\mathbb{P}(S_{2}={\bm{s}}_{2}|S_{1}={\bm{s}}_{1})\mathbb{P}(S_{1}={\bm{s}}_{1}).

更一般地,借助乘积法则,对 KK 个事件可得More generally, using the product rule, we have for KK events

P(A1∩…∩AK)=P(AK∣A1∩…∩AK−1)P(A1∩…∩AK−1).\mathbb{P}\left(A_{1}\cap\ldots\cap A_{K}\right)=\mathbb{P}\left(A_{K}\mid A_{1}\cap\ldots\cap A_{K-1}\right)\mathbb{P}\left(A_{1}\cap\ldots\cap A_{K-1}\right).

再次运用乘积法则,便得到Applying the product rule one more time, we have

P(A1∩…∩AK−1)=P(AK−1∣A1∩…∩AK−2)P(A1∩…∩AK−2).\mathbb{P}\left(A_{1}\cap\ldots\cap A_{K-1}\right)=\mathbb{P}\left(A_{K-1}\mid A_{1}\cap\ldots\cap A_{K-2}\right)\mathbb{P}\left(A_{1}\cap\ldots\cap A_{K-2}\right).

如此递归重复,最终得到概率的链式法则Repeating the process recursively, we arrive at the chain rule of probability

P(A1∩…∩AK)\displaystyle\mathbb{P}\left(A_{1}\cap\ldots\cap A_{K}\right) =∏j=1KP(Aj∣A1∩⋯∩Aj−1)\displaystyle=\prod_{j=1}^{K}\mathbb{P}(A_{j}\mid A_{1}\cap\dots\cap A_{j-1})
=∏j=1KP(Aj ∣ ⋂i=1j−1Ai).\displaystyle=\prod_{j=1}^{K}\mathbb{P}\left(A_{j}\,\Bigg|\,\bigcap_{i=1}^{j-1}A_{i}\right).

对 KK 个离散随机变量 SjS_{j} ,取事件 Aj:={Sj=sj}A_{j}\coloneqq\{S_{j}={\bm{s}}_{j}\} ,概率的链式法则即为For KK discrete random variables SjS_{j}, using the events Aj:={Sj=sj}A_{j}\coloneqq\{S_{j}={\bm{s}}_{j}\}, the chain rule of probability becomes

P(S1=s1,…,SK=sK)=∏j=1KP(Sj=sj∣S1=s1,…,Sj−1=sj−1).\mathbb{P}\left(S_{1}={\bm{s}}_{1},\ldots,S_{K}={\bm{s}}_{K}\right)=\prod_{j=1}^{K}\mathbb{P}(S_{j}={\bm{s}}_{j}\mid S_{1}={\bm{s}}_{1},\dots,S_{j-1}={\bm{s}}_{j-1}).

重要的是,这一分解并不需要对变量 S1,…,SKS_{1},\dots,S_{K} 作任何独立性假设。换言之,右侧条件概率乘积所刻画的概率分布空间,与左侧联合概率所刻画的概率分布空间是同一个空间。若再引入额外的条件独立性假设,还可进一步简化这一分解。Importantly, this factorization holds without any independence assumption on the variables S1,…,SKS_{1},\dots,S_{K}. In other words, the space of probability distributions specified by the joint probability on the left-hand side, and the space of probability distributions specified by the product of conditional probabilities on the right-hand side, are the same. We can further simplify the factorization if we make additional conditional independence assumptions.

10.2 条件独立性10.2 Conditional independence

我们知道,若两个事件 AA 与 BB 相互独立,则We know that if two events AA and BB are independent, then

P(A∣B)=P(A).\mathbb{P}(A|B)=\mathbb{P}(A).

类似地,若两个随机变量 S1S_{1} 与 S2S_{2} 相互独立,则Similarly, if two random variables S1S_{1} and S2S_{2} are independent, then

P(S2=s2∣S1=s1)=P(S2=s2).\mathbb{P}(S_{2}={\bm{s}}_{2}|S_{1}={\bm{s}}_{1})=\mathbb{P}(S_{2}={\bm{s}}_{2}).

更一般地,考虑 KK 个变量 S1,…,SKS_{1},\dots,S_{K},其中一些变量可能彼此依赖,另一些则可能不依赖。为简化记号,给定集合 C\mathcal{C},我们定义如下简写More generally, if we work with KK variables S1,…,SKS_{1},\dots,S_{K}, some variables may depend on each other, while others may not. To simplify the notation, given a set C\mathcal{C}, we define the shorthands

SC\displaystyle S_{\mathcal{C}} :=(Si ⁣:i∈C)\displaystyle\coloneqq(S_{i}\colon i\in\mathcal{C})
sC\displaystyle{\bm{s}}_{\mathcal{C}} :=(si ⁣:i∈C).\displaystyle\coloneqq({\bm{s}}_{i}\colon i\in\mathcal{C}).

称变量 SjS_{j} 在给定 SCS_{\mathcal{C}} 的条件下独立于 SDS_{\mathcal{D}},其中 C∩D=∅\mathcal{C}\cap\mathcal{D}=\emptyset,若对任意 sj,sC,sD{\bm{s}}_{j},{\bm{s}}_{\mathcal{C}},{\bm{s}}_{\mathcal{D}} 都有We say that a variable SjS_{j} is independent of SDS_{\mathcal{D}} conditioned on SCS_{\mathcal{C}}, with C∩D=∅\mathcal{C}\cap\mathcal{D}=\emptyset, if for any sj,sC,sD{\bm{s}}_{j},{\bm{s}}_{\mathcal{C}},{\bm{s}}_{\mathcal{D}}

P(Sj=sj∣SC=sC,SD=sD)=P(Sj=sj∣SC=sC).\mathbb{P}(S_{j}={\bm{s}}_{j}\mid S_{\mathcal{C}}={\bm{s}}_{\mathcal{C}},S_{\mathcal{D}}={\bm{s}}_{\mathcal{D}})=\mathbb{P}(S_{j}={\bm{s}}_{j}\mid S_{\mathcal{C}}={\bm{s}}_{\mathcal{C}}).

10.3 推断问题10.3 Inference problems

10.3.1 联合概率分布Joint probability distributions

考虑一组 KK 个变量 s:=(s1,…,sK){\bm{s}}\coloneqq({\bm{s}}_{1},\dots,{\bm{s}}_{K}),它们可以是有序的,也可以是无序的。每个 s{\bm{s}} 都属于笛卡尔积 S:=S1×⋯×SK\mathcal{S}\coloneqq\mathcal{S}_{1}\times\dots\times\mathcal{S}_{K}。为具体起见,本章始终假设各集合 Sk\mathcal{S}_{k} 是离散的,且 Sk:={v1,…,vMk}\mathcal{S}_{k}\coloneqq\{{\bm{v}}_{1},\dots,{\bm{v}}_{M_{k}}\}。注意,由于 Sk\mathcal{S}_{k} 是离散的,我们总可以将其与 {1,…,Mk}\{1,\dots,M_{k}\} 等同起来。图模型指定了一个联合概率分布We consider a collection of KK variables s:=(s1,…,sK){\bm{s}}\coloneqq({\bm{s}}_{1},\dots,{\bm{s}}_{K}), potentially ordered or unordered. Each s{\bm{s}} belongs to the Cartesian product S:=S1×⋯×SK\mathcal{S}\coloneqq\mathcal{S}_{1}\times\dots\times\mathcal{S}_{K}. Throughout this chapter, we assume that the sets Sk\mathcal{S}_{k} are discrete for concreteness, with Sk:={v1,…,vMk}\mathcal{S}_{k}\coloneqq\{{\bm{v}}_{1},\dots,{\bm{v}}_{M_{k}}\}. Note that because Sk\mathcal{S}_{k} is discrete, we can always identify it with {1,…,Mk}\{1,\dots,M_{k}\}. A graphical model specifies a joint probability distribution

P(S=s)\displaystyle\mathbb{P}(S={\bm{s}}) =P(S1=s1,…,SK=sK)\displaystyle=\mathbb{P}(S_{1}={\bm{s}}_{1},\dots,S_{K}={\bm{s}}_{K})
=p(s)\displaystyle=p({\bm{s}})
=p(s1,…,sK),\displaystyle=p({\bm{s}}_{1},\dots,{\bm{s}}_{K}),

其中 pp 是该联合概率分布的概率质量函数。对所有可能配置构成的笛卡尔积求和,可得where pp is the probability mass function of the joint probability distribution. Summing over the Cartesian product of all possible configurations, we obtain

∑s∈Sp(s)=∑s1,…,sK∈Sp(s1,…,sK)=1.\sum_{{\bm{s}}\in\mathcal{S}}p({\bm{s}})=\sum_{{\bm{s}}_{1},\dots,{\bm{s}}_{K}\in\mathcal{S}}p({\bm{s}}_{1},\dots,{\bm{s}}_{K})=1.

正如我们将要看到的,图模型的图结构编码了变量 (S1,…,SK)(S_{1},\dots,S_{K}) 之间的依赖关系,从而也编码了它们的联合分布如何分解。给定一个联合概率分布,通常需要解决若干推断问题。As we shall see, the graph of a graphical model encodes the dependencies between the variables (S1,…,SK)(S_{1},\dots,S_{K}) and therefore how their joint distribution factorizes. Given access to a joint probability distribution, there are several inference problems one typically needs to solve.

10.3.2 似然Likelihood

一个简单的任务是计算某些观测 s=(s1,…,sK){\bm{s}}=({\bm{s}}_{1},\dots,{\bm{s}}_{K}) 的似然,A simple task is to compute the likelihood of some observations s=(s1,…,sK){\bm{s}}=({\bm{s}}_{1},\dots,{\bm{s}}_{K}),

P(S1=s1,…,SK=sK)=p(s1,…,sK).\mathbb{P}(S_{1}={\bm{s}}_{1},\dots,S_{K}={\bm{s}}_{K})=p({\bm{s}}_{1},\dots,{\bm{s}}_{K}).

计算对数似然也很常见,It is also common to compute the log-likelihood,

log⁡P(S1=s1,…,SK=sK)=log⁡p(s1,…,sK).\log\mathbb{P}(S_{1}={\bm{s}}_{1},\dots,S_{K}={\bm{s}}_{K})=\log p({\bm{s}}_{1},\dots,{\bm{s}}_{K}).

10.3.3 最大后验推断Maximum a-posteriori inference

另一个常见任务是计算最可能的配置,Another common task is to compute the most likely configuration,

arg max⁡s1∈S1,…,sK∈SKp(s1,…,sK).\argmax_{{\bm{s}}_{1}\in\mathcal{S}_{1},\dots,{\bm{s}}_{K}\in\mathcal{S}_{K}}p({\bm{s}}_{1},\dots,{\bm{s}}_{K}).

这是联合概率分布的众数。在文献中,这也被称为最大后验(MAP)推断 [206]。This is the mode of the joint probability distribution. This is also known as maximum a-posteriori (MAP) inference in the literature [206].

10.3.4 边缘推断Marginal inference

边缘化操作是指对联合概率分布中某个给定变量的所有可能取值求和(或积分),由此可以计算其余变量的边缘概率。例如,我们可能希望除 Sk=skS_{k}={\bm{s}}_{k} 之外,对所有其他变量进行边缘化。为此,我们定义笛卡尔积The operation of marginalization consists in summing (or integrating) over all possible values of a given variable in a joint probability distribution. This allows us to compute the marginal probability of the remaining variables. For instance, we may want to marginalize all variables but Sk=skS_{k}={\bm{s}}_{k}. To do so, we define the Cartesian product

Ck(sk):=S1×⋯×Sk−1⏟Ak−1×{sk}×Sk+1×⋯×SK⏟Bk+1.\displaystyle\mathcal{C}_{k}({\bm{s}}_{k})\coloneqq\underbrace{\mathcal{S}_{1}\times\dots\times\mathcal{S}_{k-1}}_{\mathcal{A}_{k-1}}\times\{{\bm{s}}_{k}\}\times\underbrace{\mathcal{S}_{k+1}\times\dots\times\mathcal{S}_{K}}_{\mathcal{B}_{k+1}}. (10.1)

对所有变量求和(SkS_{k} 除外),得到 Sk=skS_{k}={\bm{s}}_{k} 的边缘概率,即Summing over all variables but SkS_{k}, we obtain the marginal probability of Sk=skS_{k}={\bm{s}}_{k} as

P(Sk=sk)\displaystyle\mathbb{P}(S_{k}={\bm{s}}_{k}) =∑s1,…,sK∈Ck(sk)p(s1,…,sK)\displaystyle=\sum_{{\bm{s}}_{1},\dots,{\bm{s}}_{K}\in\mathcal{C}_{k}({\bm{s}}_{k})}p({\bm{s}}_{1},\dots,{\bm{s}}_{K})
=∑s1,…,sk−1∈Ak−1∑sk+1,…,sK∈Bk+1p(s1,…,sK).\displaystyle=\sum_{{\bm{s}}_{1},\dots,{\bm{s}}_{k-1}\in\mathcal{A}_{k-1}}\sum_{{\bm{s}}_{k+1},\dots,{\bm{s}}_{K}\in\mathcal{B}_{k+1}}p({\bm{s}}_{1},\dots,{\bm{s}}_{K}).

类似地定义Defining similarly

Ck,l(sk,sl):=S1×⋯×{sk}×⋯×{sl}×⋯×SK,\displaystyle\mathcal{C}_{k,l}({\bm{s}}_{k},{\bm{s}}_{l})\coloneqq\mathcal{S}_{1}\times\dots\times\{{\bm{s}}_{k}\}\times\dots\times\{{\bm{s}}_{l}\}\times\dots\times\mathcal{S}_{K},

可得we obtain

P(Sk=sk,Sl=sl)=∑s1,…,sK∈Ck,l(sk,sl)p(s1,…,sK).\displaystyle\mathbb{P}(S_{k}={\bm{s}}_{k},S_{l}={\bm{s}}_{l})=\sum_{{\bm{s}}_{1},\dots,{\bm{s}}_{K}\in\mathcal{C}_{k,l}({\bm{s}}_{k},{\bm{s}}_{l})}p({\bm{s}}_{1},\dots,{\bm{s}}_{K}).

特别地,我们可能希望计算两个相邻变量的边缘概率,P(Sk−1=sk−1,Sk=sk)\mathbb{P}(S_{k-1}={\bm{s}}_{k-1},S_{k}={\bm{s}}_{k})。In particular, we may want to compute the marginal probability of two consecutive variables, P(Sk−1=sk−1,Sk=sk)\mathbb{P}(S_{k-1}={\bm{s}}_{k-1},S_{k}={\bm{s}}_{k}).

10.3.5 期望、凸包、边缘多胞形Expectation, convex hull, marginal polytope

另一种常见操作是计算 ϕ(S)\phi(S) 在分布 pp 下的期望,其定义为Another common operation is to compute the expectation of ϕ(S)\phi(S) under a distribution pp. It is defined by

μ:=ES∼p[ϕ(S)]=∑s∈Sp(s)ϕ(s)∈M.\displaystyle{\bm{\mu}}\coloneqq\mathbb{E}_{S\sim p}[\phi(S)]=\sum_{{\bm{s}}\in\mathcal{S}}p({\bm{s}})\phi({\bm{s}})\in\mathcal{M}.

对于 pθp_{\bm{\theta}} 下的期望,我们记作For the expectation under pθp_{\bm{\theta}}, we write

μ(θ):=ES∼pθ[ϕ(S)]=∑s∈Spθ(s)ϕ(s)∈M.\displaystyle\mu({\bm{\theta}})\coloneqq\mathbb{E}_{S\sim p_{\bm{\theta}}}[\phi(S)]=\sum_{{\bm{s}}\in\mathcal{S}}p_{\bm{\theta}}({\bm{s}})\phi({\bm{s}})\in\mathcal{M}.

在指数族分布(3.4 节)中,函数 ϕ\phi 称为统计量,它可以分解为In exponential family distributions (Section 3.4), the function ϕ\phi is called a statistic. It decomposes as

ϕ(s):=(ϕC(sC))C∈C,\displaystyle\phi({\bm{s}})\coloneqq(\phi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}}))_{\mathcal{C}\in C},

其中 C⊆[K]\mathcal{C}\subseteq[K]。直观地说,ϕ(s)\phi({\bm{s}}) 可以看作 s{\bm{s}}(一个可能离散的对象,例如一个整数序列)在向量空间中的编码或嵌入。在这种分解下,我们还可以计算where C⊆[K]\mathcal{C}\subseteq[K]. Intuitively, ϕ(s)\phi({\bm{s}}) can be thought of as an encoding or embedding of s{\bm{s}} (a potentially discrete object such as a sequence of integers) in a vector space. Under this decomposition, we can also compute

μC:=ES[ϕC(SC)]=∑s∈Sp(s)ϕC(sC).{\bm{\mu}}_{\mathcal{C}}\coloneqq\mathbb{E}_{S}[\phi_{\mathcal{C}}(S_{\mathcal{C}})]=\sum_{{\bm{s}}\in\mathcal{S}}p({\bm{s}})\phi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}}).

凸包Convex hull

均值 μ{\bm{\mu}} 属于 ϕ(S):={ϕ(s) ⁣:s∈S}\phi(\mathcal{S})\coloneqq\{\phi({\bm{s}})\colon{\bm{s}}\in\mathcal{S}\} 的凸包,The mean μ{\bm{\mu}} belongs to the convex hull of ϕ(S):={ϕ(s) ⁣:s∈S}\phi(\mathcal{S})\coloneqq\{\phi({\bm{s}})\colon{\bm{s}}\in\mathcal{S}\},

M:=conv⁡(ϕ(S)):={∑s∈Sp(s)ϕ(s) ⁣:p∈P(S)},\mathcal{M}\coloneqq\conv(\phi(\mathcal{S}))\coloneqq\left\{\sum_{{\bm{s}}\in\mathcal{S}}p({\bm{s}})\phi({\bm{s}})\colon p\in\mathcal{P}(\mathcal{S})\right\},

其中 P(S)\mathcal{P}(\mathcal{S}) 是 S\mathcal{S} 上所有可能概率分布的集合。换言之,M\mathcal{M} 是 ϕ(s)\phi({\bm{s}}) 在 s∈S{\bm{s}}\in\mathcal{S} 下所有可能凸组合的集合。M\mathcal{M} 的顶点正是所有的 s∈S{\bm{s}}\in\mathcal{S}。where P(S)\mathcal{P}(\mathcal{S}) is the set of all possible probability distributions over S\mathcal{S}. In other words, M\mathcal{M} is the set of all possible convex combinations of ϕ(s)\phi({\bm{s}}) for s∈S{\bm{s}}\in\mathcal{S}. The vertices of M\mathcal{M} are all the s∈S{\bm{s}}\in\mathcal{S}.

二值编码的情形:边缘多胞形Case of binary encodings: the marginal polytope

在离散集合 Sk={v1,…,vM}\mathcal{S}_{k}=\{{\bm{v}}_{1},\dots,{\bm{v}}_{M}\} 与二值编码(指示函数)ϕ(s)\phi({\bm{s}}) 的特殊情形下,集合 M\mathcal{M} 称为边缘多胞形 [206],因为其中每个点 μ∈M{\bm{\mu}}\in\mathcal{M} 都包含边缘概率。为说明其中的原因,考虑一元势函数In the special case of a discrete set Sk={v1,…,vM}\mathcal{S}_{k}=\{{\bm{v}}_{1},\dots,{\bm{v}}_{M}\} and of a binary encoding (indicator function) ϕ(s)\phi({\bm{s}}), the set M\mathcal{M} is called the marginal polytope [206], because each point μ∈M{\bm{\mu}}\in\mathcal{M} contains marginal probabilities. To see why, consider the unary potential

[ϕ(s)]k,i=[ϕk(sk)]i=I(sk=vi)[\phi({\bm{s}})]_{k,i}=[\phi_{k}({\bm{s}}_{k})]_{i}=\mathbb{I}({\bm{s}}_{k}={\bm{v}}_{i}) (10.2)

其中当 pp 为真时 I(p):=1\mathbb{I}(p)\coloneqq 1,否则为 00。于是我们得到 Sk=viS_{k}={\bm{v}}_{i} 的边缘概率,where I(p):=1\mathbb{I}(p)\coloneqq 1 if pp is true, 00 otherwise. We then obtain the marginal probability of Sk=viS_{k}={\bm{v}}_{i},

[μ]k,i\displaystyle[{\bm{\mu}}]_{k,i} =ES[ϕ(S)k,i]\displaystyle=\mathbb{E}_{S}[\phi(S)_{k,i}]
=ESk[ϕk(Sk)i]\displaystyle=\mathbb{E}_{S_{k}}[\phi_{k}(S_{k})_{i}]
=ESk[I(Sk=vi)]\displaystyle=\mathbb{E}_{S_{k}}[\mathbb{I}(S_{k}={\bm{v}}_{i})]
=∑sk∈SkP(Sk=sk)I(sk=vi)\displaystyle=\sum_{{\bm{s}}_{k}\in\mathcal{S}_{k}}\mathbb{P}(S_{k}={\bm{s}}_{k})\mathbb{I}({\bm{s}}_{k}={\bm{v}}_{i})
=P(Sk=vi).\displaystyle=\mathbb{P}(S_{k}={\bm{v}}_{i}).

同样地,考虑成对势函数Likewise, consider the pairwise potential

[ϕ(s)]k,l,i,j=[ϕk,l(sk,sl)]i,j=I(sk=vi,sl=vj).[\phi({\bm{s}})]_{k,l,i,j}=[\phi_{k,l}({\bm{s}}_{k},{\bm{s}}_{l})]_{i,j}=\mathbb{I}({\bm{s}}_{k}={\bm{v}}_{i},{\bm{s}}_{l}={\bm{v}}_{j}). (10.3)

于是我们得到 Sk=viS_{k}={\bm{v}}_{i} 与 Sl=vjS_{l}={\bm{v}}_{j} 的边缘概率,We then obtain the marginal probability of Sk=viS_{k}={\bm{v}}_{i} and Sl=vjS_{l}={\bm{v}}_{j},

[μ]k,l,i,j\displaystyle[{\bm{\mu}}]_{k,l,i,j} =ES[ϕ(S)k,l,i,j]\displaystyle=\mathbb{E}_{S}[\phi(S)_{k,l,i,j}]
=ESk,Sl[ϕk,l(Sk,Sl)i,j]\displaystyle=\mathbb{E}_{S_{k},S_{l}}[\phi_{k,l}(S_{k},S_{l})_{i,j}]
=ESk,Sl[I(Sk=vi,Sl=vj)]\displaystyle=\mathbb{E}_{S_{k},S_{l}}[\mathbb{I}(S_{k}={\bm{v}}_{i},S_{l}={\bm{v}}_{j})]
=∑sk∈Sk∑sl∈SlP(Sk=sk,Sl=sl)I(sk=vi,sl=vj)\displaystyle=\sum_{{\bm{s}}_{k}\in\mathcal{S}_{k}}\sum_{{\bm{s}}_{l}\in\mathcal{S}_{l}}\mathbb{P}(S_{k}={\bm{s}}_{k},S_{l}={\bm{s}}_{l})\mathbb{I}({\bm{s}}_{k}={\bm{v}}_{i},{\bm{s}}_{l}={\bm{v}}_{j})
=P(Sk=vi,Sl=vj).\displaystyle=\mathbb{P}(S_{k}={\bm{v}}_{i},S_{l}={\bm{v}}_{j}).

对于高阶势函数,也可以做同样的处理。We can do the same with higher-order potential functions.

10.3.6 暴力方法的复杂度Complexity of brute force

除了计算似然(这是平凡的)之外,用暴力方法计算边缘概率、众数和期望需要 O(∏k=1K∣Sk∣)O(\prod_{k=1}^{K}|\mathcal{S}_{k}|) 时间。特别地,若 ∣Sk∣=M ∀k∈[K]|\mathcal{S}_{k}|=M \ \forall k\in[K],暴力计算需要 O(MK)O(M^{K}) 时间。Apart from computing the likelihood, which is trivial, computing the marginal, mode and expectation by brute force takes O(∏k=1K∣Sk∣)O(\prod_{k=1}^{K}|\mathcal{S}_{k}|) time. In particular, if ∣Sk∣=M ∀k∈[K]|\mathcal{S}_{k}|=M \ \forall k\in[K], brute force takes O(MK)O(M^{K}) time.

10.4 马尔可夫链10.4 Markov chains

本节简要回顾马尔可夫链。我们之所以选择这样的记号,是为了强调它与计算链的类比。In this section, we briefly review Markov chains. Our notation is chosen to emphasize the analogies with computation chains.

10.4.1 马尔可夫性质The Markov property

当随机变量按顺序组织为 S1,…,SKS_{1},\dots,S_{K} 时,条件独立的一个简单例子是:每个变量 Sk∈SkS_{k}\in\mathcal{S}_{k} 只依赖于前一个变量 Sk−1∈Sk−1S_{k-1}\in\mathcal{S}_{k-1},即When random variables are organized sequentially as S1,…,SKS_{1},\dots,S_{K}, a simple example of conditional independence is when each variable Sk∈SkS_{k}\in\mathcal{S}_{k} only depends on the previous variable Sk−1∈Sk−1S_{k-1}\in\mathcal{S}_{k-1}, that is,

P(Sk=sk∣Sk−1=sk−1,…,S1=s1)\displaystyle\mathbb{P}(S_{k}={\bm{s}}_{k}\mid S_{k-1}={\bm{s}}_{k-1},\dots,S_{1}={\bm{s}}_{1}) =P(Sk=sk∣Sk−1=sk−1)\displaystyle=\mathbb{P}(S_{k}={\bm{s}}_{k}\mid S_{k-1}={\bm{s}}_{k-1})
:=pk(sk∣sk−1).\displaystyle\coloneqq p_{k}({\bm{s}}_{k}\mid{\bm{s}}_{k-1}).

满足上述条件的概率分布称为满足马尔可夫性质,并称为马尔可夫链。计算链由函数 fkf_{k} 指定,这些函数以 sk−1{\bm{s}}_{k-1} 为输入,输出 sk{\bm{s}}_{k}。与之类似,马尔可夫链由给定 Sk−1S_{k-1} 时 SkS_{k} 的条件概率分布 pkp_{k} 指定。于是便可定义如下生成过程A probability distribution satisfying the above is said to satisfy the Markov property, and is called a Markov chain. A computation chain is specified by the functions fkf_{k}, that take sk−1{\bm{s}}_{k-1} as input and output sk{\bm{s}}_{k}. In analogy, a Markov chain is specified by the conditional probability distributions pkp_{k} of SkS_{k} given Sk−1S_{k-1}. We can then define the generative process

S0\displaystyle S_{0} :=s0\displaystyle\coloneqq{\bm{s}}_{0}
S1\displaystyle S_{1} ∼p1(⋅∣S0)\displaystyle\sim p_{1}(\cdot\mid S_{0})
S2\displaystyle S_{2} ∼p2(⋅∣S1)\displaystyle\sim p_{2}(\cdot\mid S_{1})
SK\displaystyle S_{K} ∼pK(⋅∣SK−1).\displaystyle\sim p_{K}(\cdot\mid S_{K-1}).

严格说来,我们应当写作 Sk∣Sk−1∼pk(⋅∣Sk−1)S_{k}\mid S_{k-1}\sim p_{k}(\cdot\mid S_{k-1})。之所以采用这一记号,既是为了简洁,也是为了与计算链相类比。此外,为简化记号,我们不失一般性地假设 S0S_{0} 是确定性的(若非如此,我们总可以把 S0S_{0} 移入 S1S_{1},并添加一个哑变量作为 S0S_{0})。也就是说,P(S0=s0)=p0(s0):=1\mathbb{P}(S_{0}={\bm{s}}_{0})=p_{0}({\bm{s}}_{0})\coloneqq 1,且 S0:={s0}\mathcal{S}_{0}\coloneqq\{{\bm{s}}_{0}\}。这相当于将 S1S_{1} 的初始分布设为Strictly speaking, we should write Sk∣Sk−1∼pk(⋅∣Sk−1)S_{k}\mid S_{k-1}\sim p_{k}(\cdot\mid S_{k-1}). We choose our notation both for conciseness and for analogy with computation chains. Furthermore, to simplify the notation, we assume without loss of generality that S0S_{0} is deterministic (if this is not the case, we can always move S0S_{0} to S1S_{1} and add a dummy variable as S0S_{0}). That is, P(S0=s0)=p0(s0):=1\mathbb{P}(S_{0}={\bm{s}}_{0})=p_{0}({\bm{s}}_{0})\coloneqq 1 and S0:={s0}\mathcal{S}_{0}\coloneqq\{{\bm{s}}_{0}\}. This amounts to setting the initial distribution of S1S_{1} as

P(S1=s1):=P(S0=s0)P(S1=s1∣S0=s0)=P(S1=s1∣S0=s0).\mathbb{P}(S_{1}={\bm{s}}_{1})\coloneqq\mathbb{P}(S_{0}={\bm{s}}_{0})\mathbb{P}(S_{1}={\bm{s}}_{1}|S_{0}={\bm{s}}_{0})=\mathbb{P}(S_{1}={\bm{s}}_{1}|S_{0}={\bm{s}}_{0}).

于是,马尔可夫链的联合概率可按如下方式计算We can then compute the joint probability of the Markov chain by

P(S1=s1,…,SK=sK)\displaystyle\mathbb{P}(S_{1}={\bm{s}}_{1},\dots,S_{K}={\bm{s}}_{K}) =p(s1,…,sK)\displaystyle=p({\bm{s}}_{1},\dots,{\bm{s}}_{K})
=∏k=1KP(Sk=sk∣Sk−1=sk−1)\displaystyle=\prod_{k=1}^{K}\mathbb{P}(S_{k}={\bm{s}}_{k}\mid S_{k-1}={\bm{s}}_{k-1})
=∏k=1Kpk(sk∣sk−1),\displaystyle=\prod_{k=1}^{K}p_{k}({\bm{s}}_{k}\mid{\bm{s}}_{k-1}),

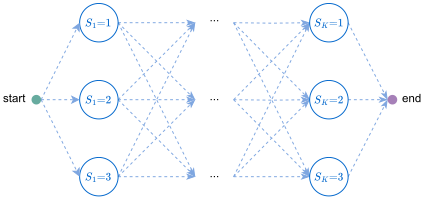
其中对 s0{\bm{s}}_{0} 的依赖被隐含,因为 p0(s0)=1p_{0}({\bm{s}}_{0})=1。具有 Sk={1,2,3}\mathcal{S}_{k}=\{1,2,3\} 的马尔可夫链如图 10.1 所示。链定义了一个全序集 {1,…,K}\{1,\dots,K\},因为图中的任意两个节点都必定由某条路径相连。where we left the dependence on s0{\bm{s}}_{0} implicit, since p0(s0)=1p_{0}({\bm{s}}_{0})=1. A Markov chain with Sk={1,2,3}\mathcal{S}_{k}=\{1,2,3\} is illustrated in Fig. 10.1. A chain defines a totally ordered set {1,…,K}\{1,\dots,K\}, since two nodes in the graph are necessarily linked to each other by a path.
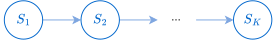
图 10.1:左:马尔可夫链。右:前向—后向算法与 Viterbi 算法的计算图:一个网格。Figure 10.1: Left: Markov chain. Right: Computation graph of the forward-backward and the Viterbi algorithms: a lattice.
例 10.4.1(分类分布链)。Example 10.4.1 (Chain of categorical distributions).
假设我们的目标是由 x∈X{\bm{x}}\in\mathcal{X} 预测一个长度为 KK 的序列,其中每个 SkS_{k} 均属于 Sk={1,…,M}\mathcal{S}_{k}=\{1,\dots,M\}。在自然语言处理中,该任务称为序列标注。我们可以定义Suppose our goal is to predict, from x∈X{\bm{x}}\in\mathcal{X}, a sequence of length KK, where each SkS_{k} belongs to Sk={1,…,M}\mathcal{S}_{k}=\{1,\dots,M\}. In natural language processing, this task is called sequence tagging. We can define Sk∼Categorical(πk−1,k,Sk−1)S_{k}\sim\mathrm{Categorical}({\bm{\pi}}_{k-1,k,S_{k-1}}) 其中where πk−1,k,i\displaystyle{\bm{\pi}}_{k-1,k,i} :=softargmax(θk−1,k,i)∈△M\displaystyle\coloneqq\mathrm{softargmax}({\bm{\theta}}_{k-1,k,i})\in\triangle^{M} =(πk−1,k,i,j)j=1M\displaystyle=(\pi_{k-1,k,i,j})_{j=1}^{M} θk−1,k,i\displaystyle{\bm{\theta}}_{k-1,k,i} :=(θk−1,k,i,j)j=1M∈RM\displaystyle\coloneqq(\theta_{k-1,k,i,j})_{j=1}^{M}\in\mathbb{R}^{M} θk−1,k,i,j\displaystyle\theta_{k-1,k,i,j} :=fk−1,k(x,i,j,wk)∈R.\displaystyle\coloneqq f_{k-1,k}({\bm{x}},i,j,{\bm{w}}_{k})\in\mathbb{R}. 因此有We therefore have P(Sk=j∣Sk−1=i)\displaystyle\mathbb{P}(S_{k}=j\mid S_{k-1}=i) =pk(j∣i)\displaystyle=p_{k}(j\mid i) =πk−1,k,i,j\displaystyle=\pi_{k-1,k,i,j} =[softargmax(θk−1,k,i)]j\displaystyle=\left[\mathrm{softargmax}({\bm{\theta}}_{k-1,k,i})\right]_{j} =exp⁡(θk−1,k,i,j)∑j′exp⁡(θk−1,k,i,j′)\displaystyle=\frac{\exp(\theta_{k-1,k,i,j})}{\sum_{j^{\prime}}\exp(\theta_{k-1,k,i,j^{\prime}})} 以及and log⁡P(Sk=j∣Sk−1=i)\displaystyle\log\mathbb{P}(S_{k}=j\mid S_{k-1}=i) =log⁡pk(j∣i)\displaystyle=\log p_{k}(j\mid i) =θk−1,k,i,j−logsumexp(θk−1,k,i)\displaystyle=\theta_{k-1,k,i,j}-\mathrm{logsumexp}({\bm{\theta}}_{k-1,k,i}) =θk−1,k,i,j−log⁡∑j′exp⁡(θk−1,k,i,j′).\displaystyle=\theta_{k-1,k,i,j}-\log\sum_{j^{\prime}}\exp(\theta_{k-1,k,i,j^{\prime}}). 我们强调,由于 k−1k-1 与 kk 总是相邻接续的,表示 θk−1,k,i,j\theta_{k-1,k,i,j} 是低效的;我们本可以改用 θk,i,j\theta_{k,i,j}。我们的记号是为与马尔可夫随机场保持一致而设计的。We emphasize that because k−1k-1 and kk are always consecutive, the representation θk−1,k,i,j\theta_{k-1,k,i,j} is inefficient; we could use θk,i,j\theta_{k,i,j} instead. Our notation is designed for consistency with Markov random fields.

10.4.2 时间齐次马尔可夫链Time-homogeneous Markov chains

时间齐次离散时间马尔可夫链对应于如下情形:无论 kk 取何值,给定 Sk−1S_{k-1} 时 SkS_{k} 的分布都相同:A time-homogeneous discrete-time Markov chain corresponds to the case when the distribution of SkS_{k} given Sk−1S_{k-1} is the same regardless of kk:

p1=⋯=pK=p.p_{1}=\dots=p_{K}=p.

有限空间情形是指每个 Sk∈SS_{k}\in\mathcal{S} 只能取有限集合 S={v1,…,vM}\mathcal{S}=\{{\bm{v}}_{1},\dots,{\bm{v}}_{M}\} 中的值,并且The finite-space case corresponds to when each Sk∈SS_{k}\in\mathcal{S} can take a finite set of values S={v1,…,vM}\mathcal{S}=\{{\bm{v}}_{1},\dots,{\bm{v}}_{M}\} and

P(Sk=vj∣Sk−1=vi)=p(vj∣vi)=πi,j,\mathbb{P}(S_{k}={\bm{v}}_{j}\mid S_{k-1}={\bm{v}}_{i})=p({\bm{v}}_{j}|{\bm{v}}_{i})=\pi_{i,j},

其中 πi,j∈[0,1]\pi_{i,j}\in[0,1] 是从 vi{\bm{v}}_{i} 到 vj{\bm{v}}_{j} 的转移概率。由于集合 S={v1,…,vM}\mathcal{S}=\{{\bm{v}}_{1},\dots,{\bm{v}}_{M}\} 是离散的,我们总可以把它与 {1,…,M}\{1,\dots,M\} 等同起来。也就是说,我们可以改写成where πi,j∈[0,1]\pi_{i,j}\in[0,1] is the transition probability from vi{\bm{v}}_{i} to vj{\bm{v}}_{j}. Because the set S={v1,…,vM}\mathcal{S}=\{{\bm{v}}_{1},\dots,{\bm{v}}_{M}\} is discrete, we can always identify it with {1,…,M}\{1,\dots,M\}. That is, we can instead write

P(Sk=j∣Sk−1=i)=p(j∣i)=πi,j.\mathbb{P}(S_{k}=j\mid S_{k-1}=i)=p(j|i)=\pi_{i,j}.

10.4.3 高阶马尔可夫链Higher-order Markov chains

更一般地,nthn^{\text{th}} 阶马尔可夫链可能不仅依赖于最后一个变量,还依赖于最后 nn 个变量,More generally, a nthn^{\text{th}}-order Markov chain may depend, not only on the last variable, but on the last nn variables,

P(Sk=sk∣Sk−1=sk−1,…,S1=s1)\displaystyle\mathbb{P}(S_{k}={\bm{s}}_{k}\mid S_{k-1}={\bm{s}}_{k-1},\dots,S_{1}={\bm{s}}_{1})
=\displaystyle= P(Sk=sk∣Sk−1=sk−1,…,Sk−n=sk−n)\displaystyle\mathbb{P}(S_{k}={\bm{s}}_{k}\mid S_{k-1}={\bm{s}}_{k-1},\dots,S_{k-n}={\bm{s}}_{k-n})
=\displaystyle= pk(sk∣sk−1,…,sk−n).\displaystyle p_{k}({\bm{s}}_{k}|{\bm{s}}_{k-1},\dots,{\bm{s}}_{k-n}).

诸如 Transformer(4.8 节)等自回归模型,可以看作是在指定一个高阶马尔可夫链,其上下文窗口大小为 nn。上下文越大,用动态规划进行精确推断在计算上就越不可行。正因如此,实践者才改用束搜索或祖先采样(10.5.3 节)。Autoregressive models such as Transformers (Section 4.8) can be seen as specifying a higher-order Markov chain, with a context window of size nn. The larger context makes exact inference using dynamic programming computationally intractable. This is why practitioners use beam search or ancestral sampling (Section 10.5.3) instead.

10.5 贝叶斯网络10.5 Bayesian networks

本节我们简要回顾贝叶斯网络。我们选择这样的记号,是为了突出贝叶斯网络与计算图之间的类比。In this section, we briefly review Bayesian networks. Our notation is chosen to emphasize the analogies with computation graphs.

10.5.1 用 DAG 表示变量依赖关系Expressing variable dependencies using DAGs

马尔可夫链以及更一般的高阶马尔可夫链,都是贝叶斯网络的特例。与 8.3 节所回顾的计算图类似,变量之间的依赖关系可以用有向无环图(DAG)G=(V,E)\mathcal{G}=(\mathcal{V},\mathcal{E}) 来表示:顶点 V={1,…,K}\mathcal{V}=\{1,\dots,K\} 表示变量,边 E\mathcal{E} 表示变量间的依赖关系。集合 {i1,…,ink}=pa⁡(k)⊆V\{i_{1},\dots,i_{n_{k}}\}={\operatorname{pa}}(k)\subseteq\mathcal{V}(其中 nk:=∣pa⁡(k)∣n_{k}\coloneqq|{\operatorname{pa}}(k)|)指明了 SkS_{k} 所依赖的变量 Si1,…,SinkS_{i_{1}},\dots,S_{i_{n_{k}}}。由此定义出一个偏序集(poset)。为记号简便起见,我们再次不失一般性地假设 S0S_{0} 是确定性的。计算图由按拓扑序排列的函数 f1,…,fKf_{1},\dots,f_{K} 指定。与之类似,贝叶斯网络则由给定 Spa⁡(k)S_{{\operatorname{pa}}(k)} 时 SkS_{k} 的条件概率分布 pkp_{k} 指定。于是我们可以定义如下的生成过程Markov chains and more generally higher-order Markov chains are a special case of Bayesian network. Similarly to computation graphs reviewed in Section 8.3, variable dependencies can be expressed using a directed acyclic graph (DAG) G=(V,E)\mathcal{G}=(\mathcal{V},\mathcal{E}), where the vertices V={1,…,K}\mathcal{V}=\{1,\dots,K\} represent variables and edges E\mathcal{E} represent variable dependencies. The set {i1,…,ink}=pa⁡(k)⊆V\{i_{1},\dots,i_{n_{k}}\}={\operatorname{pa}}(k)\subseteq\mathcal{V}, where nk:=∣pa⁡(k)∣n_{k}\coloneqq|{\operatorname{pa}}(k)|, indicates the variables Si1,…,SinkS_{i_{1}},\dots,S_{i_{n_{k}}} that SkS_{k} depends on. This defines a partially ordered set (poset). For notational simplicity, we again assume without loss of generality that S0S_{0} is deterministic. A computation graph is specified by functions f1,…,fKf_{1},\dots,f_{K} in topological order. In analogy, a Bayesian network is specified by conditional probability distributions pkp_{k} of SkS_{k} given Spa⁡(k)S_{{\operatorname{pa}}(k)}. We can then define the generative process

S0\displaystyle S_{0} :=s0\displaystyle\coloneqq{\bm{s}}_{0}
S1\displaystyle S_{1} ∼p1(⋅∣S0)\displaystyle\sim p_{1}(\cdot\mid S_{0})
S2\displaystyle S_{2} ∼p2(⋅∣Spa⁡(2))\displaystyle\sim p_{2}(\cdot\mid S_{{\operatorname{pa}}(2)})
SK\displaystyle S_{K} ∼pK(⋅∣Spa⁡(K)).\displaystyle\sim p_{K}(\cdot\mid S_{{\operatorname{pa}}(K)}).

借助概率的链式法则以及由 DAG 所表达的变量独立性,联合概率分布即为(假设 S0,S1,…,SKS_{0},S_{1},\dots,S_{K} 采用拓扑序)Using the chain rule of probability and variable independencies expressed by the DAG, the joint probability distribution is then (assuming a topological order for S0,S1,…,SKS_{0},S_{1},\dots,S_{K})

P(S=s)\displaystyle\mathbb{P}(S={\bm{s}}) :=P(S1=s1,…,SK=sK)\displaystyle\coloneqq\mathbb{P}(S_{1}={\bm{s}}_{1},\dots,S_{K}={\bm{s}}_{K})
=∏k=1KP(Sk=sk∣Spa⁡(k)=spa⁡(k))\displaystyle=\prod_{k=1}^{K}\mathbb{P}(S_{k}={\bm{s}}_{k}|S_{{\operatorname{pa}}(k)}={\bm{s}}_{{\operatorname{pa}}(k)})
:=∏k=1Kpk(sk∣spa⁡(k)).\displaystyle\coloneqq\prod_{k=1}^{K}p_{k}({\bm{s}}_{k}|{\bm{s}}_{{\operatorname{pa}}(k)}).

这种表示方式非常适合刻画随机变量之间的因果关系。This representation is well suited to express causal relationships between random variables.

10.5.2 参数化贝叶斯网络Parameterizing Bayesian networks

在贝叶斯框架中,观测数据、隐变量、参数和噪声变量统统被视为随机变量。若与节点 kk 相关联的条件分布 pkp_{k} 依赖于某些参数,则可以把这些参数经由父节点作为条件提供给 pkp_{k}。In a Bayesian framework, observed data, latent variables, parameters and noise variables are all treated as random variables. If the conditional distribution pkp_{k} associated to node kk depends on some parameters, they can be provided to pkp_{k} as conditioning, using parent nodes.

贝叶斯网络由条件分布 pkp_{k} 指定。因此,与计算图不同,贝叶斯网络中并没有函数 fkf_{k} 这一概念。不过,贝叶斯网络的根节点可以是神经网络的输出。例如,RNN 或 Transformer 等自回归模型指定了在给定先前 token 的条件下下一个 token 的条件概率分布,再借助概率的链式法则得到整个序列上的概率分布。A Bayesian network is specified by the conditional distributions pkp_{k}. Therefore, unlike computation graphs, there is no notion of function fkf_{k} in a Bayesian network. However, the root nodes of the Bayesian network can be the output of a neural network. For instance, autoregressive models, such as RNNs or Transformers, specify the conditional probability distribution of a token given past tokens, and the chain rule of probability is used to obtain a probability distribution over entire sequences.

10.5.3 祖先采样Ancestral sampling

贝叶斯网络的一大优势在于:只要每个条件分布 pkp_{k} 都已归一化,S=(S1,…,SK)S=(S_{1},\dots,S_{K}) 的联合分布便自动归一化。这意味着,我们只需遵循生成过程,就能轻而易举地从联合分布中抽取独立同分布的样本:按拓扑序 k=1,…,Kk=1,\dots,K 依次进行,在第 kk 次迭代中,以先前的取值 spa⁡(k){\bm{s}}_{{\operatorname{pa}}(k)} 为条件抽取取值 sk∼pk(⋅∣spa⁡(k)){\bm{s}}_{k}\sim p_{k}(\cdot|{\bm{s}}_{{\operatorname{pa}}(k)})。这一过程称为祖先采样。A major advantage of Bayesian networks is that, provided that each conditional distribution pkp_{k} is normalized, the joint distribution of S=(S1,…,SK)S=(S_{1},\dots,S_{K}) is automatically normalized. This means that we can very easily draw i.i.d. samples from the joint distribution, by following the generative process: we follow the topological order k=1,…,Kk=1,\dots,K and on iteration kk we draw a value sk∼pk(⋅∣spa⁡(k)){\bm{s}}_{k}\sim p_{k}(\cdot|{\bm{s}}_{{\operatorname{pa}}(k)}) conditioned on the previous values spa⁡(k){\bm{s}}_{{\operatorname{pa}}(k)}. This is known as ancestral sampling.

10.6 马尔可夫随机场10.6 Markov random fields

10.6.1 用无向图表示因子Expressing factors using undirected graphs

马尔可夫随机场(MRF),又称无向图模型,所指定的分布可分解为A Markov random field (MRF), a.k.a. undirected graphical model, specifies a distribution that factorizes as

P(S=s)=p(s):=1Z∏C∈CψC(sC),\mathbb{P}(S={\bm{s}})=p({\bm{s}})\coloneqq\frac{1}{Z}\prod_{\mathcal{C}\in C}\psi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}}),

其中 CC 是 G\mathcal{G} 的极大团集合,即 V\mathcal{V} 中完全连通的子集;ZZ 是归一化常数,定义为where CC is the set of maximal cliques of G\mathcal{G}, that is, subsets of V\mathcal{V} that are fully connected, ZZ is a normalization constant defined by

Z:=∑s∈S∏C∈CψC(sC),Z\coloneqq\sum_{{\bm{s}}\in\mathcal{S}}\prod_{\mathcal{C}\in C}\psi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}}),

而 ψC ⁣:SC→R+\psi_{\mathcal{C}}\colon\mathcal{S}_{\mathcal{C}}\to\mathbb{R}_{+} 是势函数(又称相容函数),满足 SC:=(Sj)j∈C\mathcal{S}_{\mathcal{C}}\coloneqq(\mathcal{S}_{j})_{j\in\mathcal{C}}。根据 Hammersley-Clifford 定理,马尔可夫随机场亦可等价地用马尔可夫性质来定义;感兴趣的读者可参阅 [206]。就本章而言,上述定义已足以满足需要。and ψC ⁣:SC→R+\psi_{\mathcal{C}}\colon\mathcal{S}_{\mathcal{C}}\to\mathbb{R}_{+} is a potential function (a.k.a. compatibility function), with SC:=(Sj)j∈C\mathcal{S}_{\mathcal{C}}\coloneqq(\mathcal{S}_{j})_{j\in\mathcal{C}}. According to the Hammersley-Clifford theorem, an MRF can be equivalently defined in terms of Markov properties; we refer the interested reader to [206]. For the sake of this chapter, the definition above is sufficient for our purposes.

例 10.6.1(作为马尔可夫随机场的马尔可夫链)。Example 10.6.1 (Markov chains as Markov random fields).
对于一条链,令 S=(S1,…,SK)S=(S_{1},\dots,S_{K}) 与 s=(s1,…,sK){\bm{s}}=({\bm{s}}_{1},\dots,{\bm{s}}_{K}),回顾For a chain, letting S=(S1,…,SK)S=(S_{1},\dots,S_{K}) and s=(s1,…,sK){\bm{s}}=({\bm{s}}_{1},\dots,{\bm{s}}_{K}), recall that P(S=s)=∏k=1Kpk(sk∣sk−1).\mathbb{P}(S={\bm{s}})=\prod_{k=1}^{K}p_{k}({\bm{s}}_{k}\mid{\bm{s}}_{k-1}). 这等价于一个具有 Z=1Z=1 的马尔可夫随机场(因为一条链会自动归一化),This is equivalent to an MRF with Z=1Z=1 (since a chain is automatically normalized), C:={{0,1},{1,2},…,{K−1,K}}C\coloneqq\{\{0,1\},\{1,2\},\dots,\{K-1,K\}\} 并且其势函数为and with potential function ψ{k−1,k}(sk−1,sk):=pk(sk∣sk−1).\psi_{\{k-1,k\}}({\bm{s}}_{k-1},{\bm{s}}_{k})\coloneqq p_{k}({\bm{s}}_{k}|{\bm{s}}_{k-1}). 更一般地,贝叶斯网络可以通过为每个节点的父节点构造相应的势函数,类似地写成一个马尔可夫随机场。More generally, a Bayesian network can be similarly written as an MRF by creating appropriate potential functions corresponding to the parents of each node.

10.6.2 作为指数族分布的马尔可夫随机场MRFs as exponential family distributions

下面定义势函数Let us define the potential functions

ψC(sC;θC):=exp⁡(⟨θC,ϕC(sC)⟩)\psi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}};{\bm{\theta}}_{\mathcal{C}})\coloneqq\exp(\langle{\bm{\theta}}_{\mathcal{C}},\phi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}})\rangle)

其中 ϕC ⁣:SC→ΘC\phi_{\mathcal{C}}\colon\mathcal{S}_{\mathcal{C}}\to\Theta_{\mathcal{C}} 为某个充分统计量函数,θC∈ΘC{\bm{\theta}}_{\mathcal{C}}\in\Theta_{\mathcal{C}} 为参数。于是,for some sufficient statistic function ϕC ⁣:SC→ΘC\phi_{\mathcal{C}}\colon\mathcal{S}_{\mathcal{C}}\to\Theta_{\mathcal{C}} and parameters θC∈ΘC{\bm{\theta}}_{\mathcal{C}}\in\Theta_{\mathcal{C}}. Then,

pθ(s)\displaystyle p_{\bm{\theta}}({\bm{s}}) :=1Z(θ)∏C∈CψC(sC;θC)\displaystyle\coloneqq\frac{1}{Z({\bm{\theta}})}\prod_{\mathcal{C}\in C}\psi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}};{\bm{\theta}}_{\mathcal{C}})
=1Z(θ)∏C∈Cexp⁡(⟨θC,ϕC(sC)⟩)\displaystyle=\frac{1}{Z({\bm{\theta}})}\prod_{\mathcal{C}\in C}\exp(\langle{\bm{\theta}}_{\mathcal{C}},\phi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}})\rangle)
=1Z(θ)exp⁡(∑C∈C⟨θC,ϕC(sC)⟩)\displaystyle=\frac{1}{Z({\bm{\theta}})}\exp\left(\sum_{\mathcal{C}\in C}\langle{\bm{\theta}}_{\mathcal{C}},\phi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}})\rangle\right)
=1Z(θ)exp⁡(⟨θ,ϕ(s)⟩)\displaystyle=\frac{1}{Z({\bm{\theta}})}\exp\left(\langle{\bm{\theta}},\phi({\bm{s}})\rangle\right)
=exp⁡(⟨θ,ϕ(s)⟩−A(θ))\displaystyle=\exp\left(\langle{\bm{\theta}},\phi({\bm{s}})\rangle-A({\bm{\theta}})\right)

其中where

ϕ(s)\displaystyle\phi({\bm{s}}) :=(ϕC(sC))C∈C\displaystyle\coloneqq(\phi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}}))_{\mathcal{C}\in C}
θ\displaystyle{\bm{\theta}} :=(θC)C∈C\displaystyle\coloneqq({\bm{\theta}}_{\mathcal{C}})_{\mathcal{C}\in C}
Z(θ)\displaystyle Z({\bm{\theta}}) :=∑s∈S∏C∈CψC(sC;θC)\displaystyle\coloneqq\sum_{{\bm{s}}\in\mathcal{S}}\prod_{\mathcal{C}\in C}\psi_{\mathcal{C}}({\bm{s}}_{\mathcal{C}};{\bm{\theta}}_{\mathcal{C}})
=∑s∈Sexp⁡(⟨θ,ϕ(s)⟩)\displaystyle=\sum_{{\bm{s}}\in\mathcal{S}}\exp\left(\langle{\bm{\theta}},\phi({\bm{s}})\rangle\right)
A(θ)\displaystyle A({\bm{\theta}}) :=log⁡Z(θ).\displaystyle\coloneqq\log Z({\bm{\theta}}).

因此,对于这种势函数选择,我们可以把马尔可夫随机场视为一个指数族分布(3.4 节):其自然参数为 θ{\bm{\theta}},充分统计量为 ϕ\phi,对数配分函数为 A(θ)A({\bm{\theta}})。Therefore, for this choice of potential functions, we can view an MRF as an exponential family distribution (Section 3.4) with natural parameters θ{\bm{\theta}}, sufficient statistic ϕ\phi and log-partition function A(θ)A({\bm{\theta}}).

例 10.6.2(Ising 模型)。Example 10.6.2 (Ising model).
Ising 模型是马尔可夫随机场的经典例子。设 Y=(Y1,…,YM)∈{0,1}MY=(Y_{1},\dots,Y_{M})\in\{0,1\}^{M} 是一个由二值变量 Yi∈{0,1}Y_{i}\in\{0,1\} 构成的无序集合。它构成一个图 G=(V,E)\mathcal{G}=(\mathcal{V},\mathcal{E}),其中 V=[M]\mathcal{V}=[M] 且 E⊆V2\mathcal{E}\subseteq V^{2},使得 (i,j)∈E(i,j)\in\mathcal{E} 表示 YiY_{i} 与 YjY_{j} 相互作用。在统计物理中,YiY_{i} 可以表示粒子的存在与否,或磁体的取向;在图像处理中,YiY_{i} 可以表示一个黑白像素;在多标签分类中,YiY_{i} 可以表示某个标签的存在与否。于是 y=(y1,…,yM)∈{0,1}M{\bm{y}}=(y_{1},\dots,y_{M})\in\{0,1\}^{M} 的概率为The Ising model is a classical example of MRF. Let Y=(Y1,…,YM)∈{0,1}MY=(Y_{1},\dots,Y_{M})\in\{0,1\}^{M} be an unordered collection of binary variables Yi∈{0,1}Y_{i}\in\{0,1\}. This forms a graph G=(V,E)\mathcal{G}=(\mathcal{V},\mathcal{E}), where V=[M]\mathcal{V}=[M] and E⊆V2\mathcal{E}\subseteq V^{2}, such that (i,j)∈E(i,j)\in\mathcal{E} means that YiY_{i} interacts with YjY_{j}. In statistical physics, YiY_{i} may indicate the presence or absence of particles, or the orientation of magnets. In image processing, YiY_{i} may represent a black and white pixel. In multi-label classification, YiY_{i} may indicate the presence or absence of a label. The probability of y=(y1,…,yM)∈{0,1}M{\bm{y}}=(y_{1},\dots,y_{M})\in\{0,1\}^{M} is then P(Y=y)\displaystyle\mathbb{P}(Y={\bm{y}}) =pθ(y)\displaystyle=p_{\bm{\theta}}({\bm{y}}) =exp⁡(∑i∈Vθiyi+∑(i,j)∈Eθi,jyiyj−A(θ))\displaystyle=\exp\left(\sum_{i\in\mathcal{V}}\theta_{i}y_{i}+\sum_{(i,j)\in\mathcal{E}}\theta_{i,j}y_{i}y_{j}-A({\bm{\theta}})\right) =exp⁡(∑C∈C⟨θC,ϕC(y)⟩−A(θ)),\displaystyle=\exp\left(\sum_{\mathcal{C}\in C}\langle{\bm{\theta}}_{\mathcal{C}},\phi_{\mathcal{C}}({\bm{y}})\rangle-A({\bm{\theta}})\right), 其中 C:=V∪EC\coloneqq\mathcal{V}\cup\mathcal{E},且 θ∈R∣V∣+∣E∣{\bm{\theta}}\in\mathbb{R}^{|\mathcal{V}|+|\mathcal{E}|} 是 (θi)i∈V(\theta_{i})_{i\in\mathcal{V}} 与 (θi,j)(i,j)∈E(\theta_{i,j})_{(i,j)\in\mathcal{E}} 的拼接。在神经网络的语境中,这类模型也称为玻尔兹曼机。一般 Ising 模型中的 MAP 推断已知是 NP 难的,但当交互权重 θi,j\theta_{i,j} 非负时,MAP 推断可以归约为图割算法 [83]。上述方程可以通过两种方式扩展。第一,我们可以使用高阶交互,例如对 (i,j,k)∈V3(i,j,k)\in\mathcal{V}^{3} 使用 yiyjyky_{i}y_{j}y_{k}。第二,我们可能希望使用分类变量,这引出了 Potts 模型。where C:=V∪EC\coloneqq\mathcal{V}\cup\mathcal{E} and θ∈R∣V∣+∣E∣{\bm{\theta}}\in\mathbb{R}^{|\mathcal{V}|+|\mathcal{E}|} is the concatenation of (θi)i∈V(\theta_{i})_{i\in\mathcal{V}} and (θi,j)(i,j)∈E(\theta_{i,j})_{(i,j)\in\mathcal{E}}. These models are also known as Boltzmann machines in a neural network context. MAP inference in general Ising models is known to be NP-hard, but when the interaction weights θi,j\theta_{i,j} are non-negative, MAP inference can be reduced to graph cut algorithms [83]. There are two ways the above equation can be extended. First, we can use higher-order interactions, such as yiyjyky_{i}y_{j}y_{k} for (i,j,k)∈V3(i,j,k)\in\mathcal{V}^{3}. Second, we may want to use categorical variables, which leads to the Potts model.

10.6.3 条件随机场Conditional random fields

条件随机场 [114, 192] 是马尔可夫随机场的一种特例,其中显式地引入了条件变量。例如,当目标是预测以变量 x{\bm{x}} 为条件的变量 y{\bm{y}} 时,条件随机场定义为Conditional random fields [114, 192] are a special case of Markov random field, in which a conditioning variable is explicitly incorporated. For example, when the goal is to predict a variable y{\bm{y}} conditioned on a variable x{\bm{x}}, CRFs are defined as

P(Y=y∣X=x)=p(y∣x)=1Z(x)∏C∈CψC(yC,x).\mathbb{P}(Y={\bm{y}}\mid X={\bm{x}})=p({\bm{y}}\mid{\bm{x}})=\frac{1}{Z({\bm{x}})}\prod_{\mathcal{C}\in C}\psi_{\mathcal{C}}({\bm{y}}_{\mathcal{C}},{\bm{x}}).

注意,势函数 ψC\psi_{\mathcal{C}} 可以依赖于整个 x{\bm{x}},因为 x{\bm{x}} 只是一个条件变量。Note that the potential functions ψC\psi_{\mathcal{C}} are allowed to depend on the whole x{\bm{x}}, as x{\bm{x}} is just a conditioning variable.

10.6.4 采样Sampling

与贝叶斯网络不同,马尔可夫随机场需要显式的归一化常数 ZZ。因此,从一般马尔可夫随机场所表示的分布中采样,通常比贝叶斯网络的情形更为繁琐。一种常用技术是 Gibbs 采样。Contrary to Bayesian networks, MRFs require an explicit normalization constant ZZ. As a result, sampling from a distribution represented by a general MRF is usually more involved than for Bayesian networks. A commonly-used technique is Gibbs sampling.

10.7 链上的推断10.7 Inference on chains

本节回顾如何对如下形式的联合分布进行边缘推断与最大后验推断In this section, we review how to perform marginal inference and maximum a-posteriori inference on joint distributions of the form

p(s1,…,sK)=1Z∏k=1Kψk(sk−1,sk),p({\bm{s}}_{1},\dots,{\bm{s}}_{K})=\frac{1}{Z}\prod_{k=1}^{K}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k}),

其中where

Z:=∑s∈S∏k=1Kψk(sk−1,sk)Z\coloneqq\sum_{{\bm{s}}\in\mathcal{S}}\prod_{k=1}^{K}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})

其中我们用 ψk\psi_{k} 作为 ψk−1,k\psi_{k-1,k} 的简写,因为 k−1k-1 与 kk 是相邻的。如例 10.6.1 所解释的,这也可以通过令and where we used ψk\psi_{k} as a shorthand for ψk−1,k\psi_{k-1,k}, since k−1k-1 and kk are consecutive. As explained in Example 10.6.1, this also includes Markov chains by setting

ψk(sk−1,sk):=pk(sk∣sk−1),\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\coloneqq p_{k}({\bm{s}}_{k}\mid{\bm{s}}_{k-1}),

来纳入马尔可夫链,此时 Z=1Z=1 。in which case Z=1Z=1.

10.7.1 前向—后向算法The forward-backward algorithm

前向—后向算法的关键思想,是利用乘法对加法的分配律,将其写成The key idea of the forward-backward algorithm is to use the distributivity of multiplication over addition to write

Z=∑s1∈S1ψ1(s0,s1)∑s2∈S2ψ2(s1,s2)⋯∑sK∈SKψK(sK−1,sK).Z=\sum_{{\bm{s}}_{1}\in\mathcal{S}_{1}}\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1})\sum_{{\bm{s}}_{2}\in\mathcal{S}_{2}}\psi_{2}({\bm{s}}_{1},{\bm{s}}_{2})\dots\sum_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\psi_{K}({\bm{s}}_{K-1},{\bm{s}}_{K}).

我们可以递归地计算这些和,既可以向前也可以向后。回顾式 10.1 中 Ak−1\mathcal{A}_{k-1} 和 Bk+1\mathcal{B}_{k+1} 的定义,我们定义上至和下至 kk 的求和,We can compute these sums recursively, either forward or backward. Recalling the definitions of Ak−1\mathcal{A}_{k-1} and Bk+1\mathcal{B}_{k+1} in Eq. 10.1, we define the summations up to and down to kk,

αk(sk)\displaystyle\alpha_{k}({\bm{s}}_{k}) :=∑s1,…,sk−1∈Ak−1∏j=1kψj(sj−1,sj)\displaystyle\coloneqq\sum_{{\bm{s}}_{1},\dots,{\bm{s}}_{k-1}\in\mathcal{A}_{k-1}}\prod_{j=1}^{k}\psi_{j}({\bm{s}}_{j-1},{\bm{s}}_{j})
=∑sk−1∈Sk−1ψk(sk−1,sk)⋯∑s1∈S1ψ2(s1,s2)ψ1(s0,s1)\displaystyle=\sum_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\dots\sum_{{\bm{s}}_{1}\in\mathcal{S}_{1}}\psi_{2}({\bm{s}}_{1},{\bm{s}}_{2})\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1})
βk(sk)\displaystyle\beta_{k}({\bm{s}}_{k}) :=∑sk+1,…,sK∈Bk+1∏j=k+1Kψj(sj−1,sj)\displaystyle\coloneqq\sum_{{\bm{s}}_{k+1},\dots,{\bm{s}}_{K}\in\mathcal{B}_{k+1}}\prod_{j=k+1}^{K}\psi_{j}({\bm{s}}_{j-1},{\bm{s}}_{j})
=∑sk+1∈Sk+1ψk+1(sk,sk+1)⋯∑sK∈SKψK(sK−1,sK).\displaystyle=\sum_{{\bm{s}}_{k+1}\in\mathcal{S}_{k+1}}\psi_{k+1}({\bm{s}}_{k},{\bm{s}}_{k+1})\dots\sum_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\psi_{K}({\bm{s}}_{K-1},{\bm{s}}_{K}).

我们可以通过前向递归和后向递归来计算这两个量We can compute the two quantities by recursing forward and backward

αk(sk)\displaystyle\alpha_{k}({\bm{s}}_{k}) =∑sk−1∈Sk−1ψk(sk−1,sk)αk−1(sk−1)\displaystyle=\sum_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\alpha_{k-1}({\bm{s}}_{k-1})
βk(sk)\displaystyle\beta_{k}({\bm{s}}_{k}) =∑sk+1∈Sk+1ψk+1(sk,sk+1)βk+1(sk+1)\displaystyle=\sum_{{\bm{s}}_{k+1}\in\mathcal{S}_{k+1}}\psi_{k+1}({\bm{s}}_{k},{\bm{s}}_{k+1})\beta_{k+1}({\bm{s}}_{k+1})

其中我们定义了初始化where we defined the initializations

α1(s1)\displaystyle\alpha_{1}({\bm{s}}_{1}) :=ψ1(s0,s1)∀s1∈S1\displaystyle\coloneqq\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1})\quad\forall{\bm{s}}_{1}\in\mathcal{S}_{1}
βK(sK)\displaystyle\beta_{K}({\bm{s}}_{K}) :=1∀sK∈SK.\displaystyle\coloneqq 1\quad\forall{\bm{s}}_{K}\in\mathcal{S}_{K}.

归一化项随后可由下式计算The normalization term can then be computed by

Z=∑sK∈SKαK(sK)βK(sK)=∑s1∈S1α1(s1)β1(s1)\displaystyle Z=\sum_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\alpha_{K}({\bm{s}}_{K})\beta_{K}({\bm{s}}_{K})=\sum_{{\bm{s}}_{1}\in\mathcal{S}_{1}}\alpha_{1}({\bm{s}}_{1})\beta_{1}({\bm{s}}_{1})

而边缘概率为and the marginal probabilities by

P(Sk=sk)\displaystyle\mathbb{P}(S_{k}={\bm{s}}_{k}) =1Zαk(sk)βk(sk)\displaystyle=\frac{1}{Z}\alpha_{k}({\bm{s}}_{k})\beta_{k}({\bm{s}}_{k})
P(Sk−1=sk−1,Sk=sk)\displaystyle\mathbb{P}(S_{k-1}={\bm{s}}_{k-1},S_{k}={\bm{s}}_{k}) =1Zαk−1(sk−1)ψk(sk−1,sk)βk(sk).\displaystyle=\frac{1}{Z}\alpha_{k-1}({\bm{s}}_{k-1})\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\beta_{k}({\bm{s}}_{k}).

我们也可以通过下式计算条件概率We can also compute the conditional probabilities by

P(Sk=sk∣Sk−1=sk−1)\displaystyle\mathbb{P}(S_{k}={\bm{s}}_{k}\mid S_{k-1}={\bm{s}}_{k-1}) =P(Sk−1=sk−1,Sk=sk)P(Sk−1=sk−1)\displaystyle=\frac{\mathbb{P}(S_{k-1}={\bm{s}}_{k-1},S_{k}={\bm{s}}_{k})}{\mathbb{P}(S_{k-1}={\bm{s}}_{k-1})}
=αk−1(sk−1)ψk(sk−1,sk)βk(sk)αk−1(sk−1)βk−1(sk−1)\displaystyle=\frac{\alpha_{k-1}({\bm{s}}_{k-1})\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\beta_{k}({\bm{s}}_{k})}{\alpha_{k-1}({\bm{s}}_{k-1})\beta_{k-1}({\bm{s}}_{k-1})}
=ψk(sk−1,sk)βk(sk)βk−1(sk−1).\displaystyle=\frac{\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\beta_{k}({\bm{s}}_{k})}{\beta_{k-1}({\bm{s}}_{k-1})}.

在实际中,为保持数值稳定性,这两个递归通常在对数域中实现,In practice, the two recursions are often implemented in the log-domain for numerical stability,

log⁡αk(sk)\displaystyle\log\alpha_{k}({\bm{s}}_{k}) =log⁡∑sk−1∈Sk−1exp⁡(log⁡ψk(sk−1,sk)+log⁡αk−1(sk−1))\displaystyle=\log\sum_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\exp(\log\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})+\log\alpha_{k-1}({\bm{s}}_{k-1}))
log⁡βk(sk)\displaystyle\log\beta_{k}({\bm{s}}_{k}) =log⁡∑sk+1∈Sk+1exp⁡(log⁡ψk+1(sk,sk+1)+log⁡βk+1(sk+1)).\displaystyle=\log\sum_{{\bm{s}}_{k+1}\in\mathcal{S}_{k+1}}\exp(\log\psi_{k+1}({\bm{s}}_{k},{\bm{s}}_{k+1})+\log\beta_{k+1}({\bm{s}}_{k+1})).

我们认出了 log-sum-exp 算子,它可以以数值稳定的方式实现(4.4.2 节)。整个动态规划流程,又称前向—后向算法 [13, 162],总结在算法 1 中。我们注意到,前向传播与后向传播实际上是彼此独立的,因此可以并行执行。We recognize the log-sum-exp operator, which can be implemented in a numerically stable way (Section 4.4.2). The overall dynamic programming procedure, a.k.a. forward-backward algorithm [13, 162], is summarized in Algorithm 1. We notice that the forward and backward passes are actually independent of each other, and can therefore be performed in parallel.

算法 1 链上的边缘推断Algorithm 1 Marginal inference on a chain
1: Potential functions: ψ1,…,ψK\psi_{1},\dots,\psi_{K}
2: Input: s0{\bm{s}}_{0}
3: Initialize α1(s1):=ψ1(s0,s1) ∀s1∈S1\alpha_{1}({\bm{s}}_{1})\coloneqq\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1}) \ \forall{\bm{s}}_{1}\in\mathcal{S}_{1}
4: for k:=2,…,Kk\coloneqq 2,\ldots,K do ▹\triangleright Forward pass
5:   for sk∈Sk{\bm{s}}_{k}\in\mathcal{S}_{k} do
6:    αk(sk):=∑sk−1∈Sk−1ψk(sk−1,sk)αk−1(sk−1)\alpha_{k}({\bm{s}}_{k})\coloneqq\displaystyle{\sum_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\alpha_{k-1}({\bm{s}}_{k-1})}   
7: Initialize βK(sK):=1 ∀sK∈SK\beta_{K}({\bm{s}}_{K})\coloneqq 1 \ \forall{\bm{s}}_{K}\in\mathcal{S}_{K}
8: for k:=K−1,…,1k\coloneqq K-1,\ldots,1 do ▹\triangleright Backward pass
9:   for sk∈Sk{\bm{s}}_{k}\in\mathcal{S}_{k} do
10:    βk(sk):=∑sk+1∈Sk+1ψk+1(sk,sk+1)βk+1(sk+1)\beta_{k}({\bm{s}}_{k})\coloneqq\displaystyle{\sum_{{\bm{s}}_{k+1}\in\mathcal{S}_{k+1}}\psi_{k+1}({\bm{s}}_{k},{\bm{s}}_{k+1})\beta_{k+1}({\bm{s}}_{k+1})}   
11: Compute Z=∑sK∈SKαK(sK)βK(sK)=∑sK∈SKαK(sK)Z=\displaystyle{\sum_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\alpha_{K}({\bm{s}}_{K})\beta_{K}({\bm{s}}_{K})}=\displaystyle{\sum_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\alpha_{K}({\bm{s}}_{K})}
12: Outputs: ∀k∈[K]\forall k\in[K]:
13: P(Sk=sk)=1Zαk(sk)βk(sk)\mathbb{P}(S_{k}={\bm{s}}_{k})=\frac{1}{Z}\alpha_{k}({\bm{s}}_{k})\beta_{k}({\bm{s}}_{k})
14: P(Sk−1=sk−1,Sk=sk)=1Zαk−1(sk−1)ψk(sk−1,sk)βk(sk)\mathbb{P}(S_{k-1}={\bm{s}}_{k-1},S_{k}={\bm{s}}_{k})=\frac{1}{Z}\alpha_{k-1}({\bm{s}}_{k-1})\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\beta_{k}({\bm{s}}_{k})

10.7.2 Viterbi 算法The Viterbi algorithm

类似地,利用乘法对最大化运算的分配律,Similarly, using the distributivity of multiplication over maximization,

max⁡s1∈S1,…,sK∈SK∏k=1Kψk(sk−1,sk)\displaystyle\max_{{\bm{s}}_{1}\in\mathcal{S}_{1},\dots,{\bm{s}}_{K}\in\mathcal{S}_{K}}\prod_{k=1}^{K}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})
=\displaystyle= max⁡sK∈SKmax⁡sK−1∈SK−1ψK(sK−1,sK)…max⁡s1∈S1ψ2(s1,s2)ψ1(s0,s1).\displaystyle\max_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\max_{{\bm{s}}_{K-1}\in\mathcal{S}_{K-1}}\psi_{K}({\bm{s}}_{K-1},{\bm{s}}_{K})\dots\max_{{\bm{s}}_{1}\in\mathcal{S}_{1}}\psi_{2}({\bm{s}}_{1},{\bm{s}}_{2})\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1}).

我们为 k∈[K]k\in[K] 定义Let us define for k∈[K]k\in[K]

δk(sk):=max⁡sk−1∈Sk−1ψk(sk−1,sk)…max⁡s1∈S1ψ2(s1,s2)ψ1(s0,s1).\delta_{k}({\bm{s}}_{k})\coloneqq\max_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\dots\max_{{\bm{s}}_{1}\in\mathcal{S}_{1}}\psi_{2}({\bm{s}}_{1},{\bm{s}}_{2})\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1}).

我们可以递归地计算这些量,因为对于 k∈[K]k\in[K]We can compute these quantities recursively, since for k∈[K]k\in[K]

δk(sk)=max⁡sk−1∈Sk−1ψk(sk−1,sk)δk−1(sk−1),\delta_{k}({\bm{s}}_{k})=\max_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\delta_{k-1}({\bm{s}}_{k-1}),

其中 δ1(s1):=ψ1(s0,s1)\delta_{1}({\bm{s}}_{1})\coloneqq\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1}) 。最终我们得到with δ1(s1):=ψ1(s0,s1)\delta_{1}({\bm{s}}_{1})\coloneqq\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1}). We finally have

max⁡s1∈S1,…,sK∈SKp(s1,…,sK)=1Zmax⁡sK∈SKδK(sK).\max_{{\bm{s}}_{1}\in\mathcal{S}_{1},\dots,{\bm{s}}_{K}\in\mathcal{S}_{K}}p({\bm{s}}_{1},\dots,{\bm{s}}_{K})=\frac{1}{Z}\max_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\delta_{K}({\bm{s}}_{K}).

在实际中,为保持数值稳定性,我们通常在对数域中实现前向递归。利用对数函数的单调性,我们确实对所有的 k∈[K]k\in[K] 都有In practice, for numerical stability, we often implement the forward recursion in the log-domain. Using the fact that the logarithm is monotonic, we indeed have for all k∈[K]k\in[K]

log⁡δk(sk)=max⁡sk−1∈Sk−1log⁡ψk(sk−1,sk)+log⁡δk−1(sk−1).\log\delta_{k}({\bm{s}}_{k})=\max_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\log\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})+\log\delta_{k-1}({\bm{s}}_{k-1}).

为了能够高效地回溯,在前向传播过程中,我们计算To enable efficient backtracking, during the forward pass, we compute

qk(sk):=arg max⁡sk−1∈Sk−1ψk(sk−1,sk)δk−1(sk−1)q_{k}({\bm{s}}_{k})\coloneqq\argmax_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\delta_{k-1}({\bm{s}}_{k-1})

它可以被视为从 sk⋆{\bm{s}}_{k}^{\star} 指向 sk−1⋆{\bm{s}}_{k-1}^{\star} 的回溯指针。which can be thought of as backpointers from sk⋆{\bm{s}}_{k}^{\star} to sk−1⋆{\bm{s}}_{k-1}^{\star}.

所得的动态规划流程,又称 Viterbi 算法 [204, 69],总结在算法 2 中。The resulting dynamic programming procedure, a.k.a. Viterbi algorithm [204, 69], is summarized in Algorithm 2.

算法 2 链上的最大后验推断Algorithm 2 MAP inference on a chain
1: Potential functions: ψ1,…,ψK\psi_{1},\dots,\psi_{K}
2: Input: s0{\bm{s}}_{0}
3: Initialize δ1(s1):=ψ1(s0,s1) ∀s1∈S1\delta_{1}({\bm{s}}_{1})\coloneqq\psi_{1}({\bm{s}}_{0},{\bm{s}}_{1}) \ \forall{\bm{s}}_{1}\in\mathcal{S}_{1}
4: for k:=2,…,Kk\coloneqq 2,\ldots,K do ▹\triangleright Forward pass
5:   for sk∈Sk{\bm{s}}_{k}\in\mathcal{S}_{k} do
6:    δk(sk):=max⁡sk−1∈Sk−1ψk(sk−1,sk)δk−1(sk−1)\delta_{k}({\bm{s}}_{k})\coloneqq\displaystyle{\max_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\delta_{k-1}({\bm{s}}_{k-1})}
7:    qk(sk):=arg max⁡sk−1∈Sk−1ψk(sk−1,sk)δk−1(sk−1)q_{k}({\bm{s}}_{k})\coloneqq\displaystyle{\argmax_{{\bm{s}}_{k-1}\in\mathcal{S}_{k-1}}\psi_{k}({\bm{s}}_{k-1},{\bm{s}}_{k})\delta_{k-1}({\bm{s}}_{k-1})}   
8: δ⋆:=max⁡sK∈SKδK(sK)\delta^{\star}\coloneqq\displaystyle{\max_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\delta_{K}({\bm{s}}_{K})}
9: sK⋆:=arg max⁡sK∈SKδK(sK){\bm{s}}_{K}^{\star}\coloneqq\displaystyle{\argmax_{{\bm{s}}_{K}\in\mathcal{S}_{K}}\delta_{K}({\bm{s}}_{K})}
10: for k:=K−1,…,1k\coloneqq K-1,\ldots,1 do ▹\triangleright Backtracking
11:   sk⋆:=qk+1(sk+1⋆){\bm{s}}_{k}^{\star}\coloneqq q_{k+1}({\bm{s}}_{k+1}^{\star})
12: Outputs: max⁡s1∈S1,…,sK∈SKp(s1,…,sK)∝δ⋆\displaystyle{\max_{{\bm{s}}_{1}\in\mathcal{S}_{1},\dots,{\bm{s}}_{K}\in\mathcal{S}_{K}}p({\bm{s}}_{1},\dots,{\bm{s}}_{K})\propto\delta^{\star}}
13:        arg max⁡s1∈S1,…,sK∈SKp(s1,…,sK)=(s1⋆,…,sK⋆)\displaystyle{\argmax_{{\bm{s}}_{1}\in\mathcal{S}_{1},\dots,{\bm{s}}_{K}\in\mathcal{S}_{K}}p({\bm{s}}_{1},\dots,{\bm{s}}_{K})=({\bm{s}}_{1}^{\star},\dots,{\bm{s}}_{K}^{\star})}

10.8 树上的推断10.8 Inference on trees

更一般地,当变量之间的依赖关系用树或多树表示时,可以执行基于动态规划的高效推断。所得的边缘推断与最大后验推断算法通常被称为和—积算法与最大—和算法。和—积算法也被称为信念传播或消息传递,因为它可以被解释为在图中传播“局部消息”。更多细节可参见例如 [206, 2.5.1 节]。More generally, efficient inference based on dynamic programming can be performed when dependencies between variables are expressed using a tree or polytree. The resulting marginal inference and MAP inference algorithms are often referred to as the sum-product and max-sum algorithms. The sum-product algorithm is also known as belief propagation or message passing, since it can be interpreted as propagating “local messages” through the graph. See for instance [206, Section 2.5.1] for more details.

10.9 推断即求导10.9 Inference as differentiation

本节回顾一方面对指数族分布的对数配分函数求导,另一方面执行边缘推断(以及零温度极限下的最大后验推断),二者之间的深刻联系。In this section, we review the profound connections between differentiating the log-partition function of an exponential family distribution on one hand, and performing marginal inference (as well as maximum a-posteriori inference in the zero-temperature limit) on the other hand.

10.9.1 推断即对数配分函数的梯度Inference as gradient of the log-partition

我们首先讨论图模型文献中一个众所周知的事实:当以二进制编码作为指数族分布的充分统计量 ϕ\phi 时,对数配分函数 A(θ)A({\bm{\theta}}) 的梯度 ∇A(θ)\nabla A({\bm{\theta}}) 汇集了所有边缘概率 [206]。We first discuss a well-known fact in the graphical model literature: when using a binary encoding as the sufficient statistic ϕ\phi in an exponential family distribution, the gradient ∇A(θ)\nabla A({\bm{\theta}}) of the log-partition A(θ)A({\bm{\theta}}) gathers all the marginals [206].

要理解其中的原因,回顾 3.4 节中指数族分布的定义To see why, recall from Section 3.4 the definition of an exponential family distribution

pθ(s)\displaystyle p_{\bm{\theta}}({\bm{s}}) =h(s)exp⁡[⟨θ,ϕ(s)⟩−A(θ)]\displaystyle=h({\bm{s}})\exp\left[\langle{\bm{\theta}},\phi({\bm{s}})\rangle-A({\bm{\theta}})\right]

及其对数配分函数and of its log-partition

A(θ):=log⁡∑s∈Sh(s)exp⁡[⟨θ,ϕ(s)⟩].A({\bm{\theta}})\coloneqq\log\sum_{{\bm{s}}\in\mathcal{S}}h({\bm{s}})\exp\left[\langle{\bm{\theta}},\phi({\bm{s}})\rangle\right].

由命题 3.4.3,From Proposition 3.4.3,

μ(θ):=∇A(θ)=EY∼pθ[ϕ(Y)]∈M.\displaystyle\mu({\bm{\theta}})\coloneqq\nabla A({\bm{\theta}})=\mathbb{E}_{Y\sim p_{\bm{\theta}}}[\phi(Y)]\in\mathcal{M}.

因此,结合式 10.2 与式 10.3 中的二进制编码,Therefore, with the binary encodings in Eq. 10.2 and Eq. 10.3,

P(Sk=vi)\displaystyle\mathbb{P}(S_{k}={\bm{v}}_{i}) =[∇A(θ)]k,i\displaystyle=[\nabla A({\bm{\theta}})]_{k,i}
P(Sk=vi,Sl=vj)\displaystyle\mathbb{P}(S_{k}={\bm{v}}_{i},S_{l}={\bm{v}}_{j}) =[∇A(θ)]k,l,i,j.\displaystyle=[\nabla A({\bm{\theta}})]_{k,l,i,j}.

换言之,若已有计算 A(θ)A({\bm{\theta}}) 的高效算法,便可对 A(θ)A({\bm{\theta}}) 执行反向模式自动微分以得到 ∇A(θ)\nabla A({\bm{\theta}}),从而得到边缘概率。根据 8.3.3 节,计算所有边缘概率的复杂度因此与计算 A(θ)A({\bm{\theta}}) 的复杂度大致相同。Put differently, if we have an efficient algorithm for computing A(θ)A({\bm{\theta}}), we can perform reverse-mode autodiff on A(θ)A({\bm{\theta}}) to obtain ∇A(θ)\nabla A({\bm{\theta}}), and therefore obtain the marginal probabilities. Following Section 8.3.3, the complexity of computing all marginal probabilities is therefore roughly the same as that of computing A(θ)A({\bm{\theta}}).

在链这一特殊情形下,可得In the special case of chains, we obtain

P(Sk=vi)\displaystyle\mathbb{P}(S_{k}={\bm{v}}_{i}) =[∇A(θ)]k,i=1Zαk(vi)βk(vi)\displaystyle=[\nabla A({\bm{\theta}})]_{k,i}=\frac{1}{Z}\alpha_{k}({\bm{v}}_{i})\beta_{k}({\bm{v}}_{i})
P(Sk−1=vi,Sk=vj)\displaystyle\mathbb{P}(S_{k-1}={\bm{v}}_{i},S_{k}={\bm{v}}_{j}) =[∇A(θ)]k−1,k,i,j=1Zαk−1(vi)ψk(vi,vj)βk(vj),\displaystyle=[\nabla A({\bm{\theta}})]_{k-1,k,i,j}=\frac{1}{Z}\alpha_{k-1}({\bm{v}}_{i})\psi_{k}({\bm{v}}_{i},{\bm{v}}_{j})\beta_{k}({\bm{v}}_{j}),

其中我们隐式地保留了 ZZ、α\alpha 和 β\beta 对 θ{\bm{\theta}} 的依赖关系。where we left the dependence of ZZ, α\alpha and β\beta on θ{\bm{\theta}} implicit.

若定义 Aε(θ):=εA(θ/ε)A_{\varepsilon}({\bm{\theta}})\coloneqq\varepsilon A({\bm{\theta}}/\varepsilon),则在零温度极限 ε→0\varepsilon\to 0 下可得,μ(θ){\bm{\mu}}({\bm{\theta}}) 是众数的二进制编码,亦即最大后验推断解的二进制编码。If we define Aε(θ):=εA(θ/ε)A_{\varepsilon}({\bm{\theta}})\coloneqq\varepsilon A({\bm{\theta}}/\varepsilon), in the zero-temperature limit ε→0\varepsilon\to 0, we obtain that μ(θ){\bm{\mu}}({\bm{\theta}}) is a binary encoding of the mode, i.e., of the maximum a-posteriori inference solution.

下面我们说明:i) 如何利用半环与 softmax 算子统一前向—后向算法与 Viterbi 算法的前向传播;ii) 如何利用反向传播计算对数配分函数的梯度。We now show i) how to unify the forward pass of the forward-backward and Viterbi algorithms using semirings and softmax operators ii) how to compute the gradient of the log-partition using backpropagation.

10.9.2 半环与 softmax 算子Semirings and softmax operators

前向—后向算法与 Viterbi 算法中的前向传播显然相似。事实上,二者可以通过半环在形式上相互关联。The forward passes in the forward-backward and Viterbi algorithms are clearly similar. In fact, they can be formally linked to each other using semirings.

定义 10.9.1(半环)。Definition 10.9.1 (Semiring).
半环是一个集合 K\mathbb{K},配备两个二元运算 (⊕,⊗)(\oplus,\otimes),使得A semiring is a set K\mathbb{K} equipped with two binary operations (⊕,⊗)(\oplus,\otimes) such that • ⊕\oplus 满足结合律与交换律,⊕\oplus is associative and commutative, • ⊗\otimes 满足结合律,且对 ⊕\oplus 满足分配律,⊗\otimes is associative and distributive over ⊕\oplus, • ⊕\oplus 与 ⊗\otimes 分别具有单位元 0ˉ\bar{0} 与 1ˉ\bar{1}。⊕\oplus and ⊗\otimes have identity elements 0ˉ\bar{0} and 1ˉ\bar{1}, respectively.

我们采用记号 ⊕\oplus、⊗\otimes、0ˉ\bar{0} 和 1ˉ\bar{1},以便与经典的加法、乘法、00 和 11 清楚地区分开来。We use the notations ⊕\oplus, ⊗\otimes, 0ˉ\bar{0} and 1ˉ\bar{1} to clearly distinguish them from the classical addition, multiplication, 00 and 11.

下面回顾二元运算的若干法则:We recall the following laws for binary operations:

  • •

    ⊕\oplus 的交换律:a⊕b=b⊕aa\oplus b=b\oplus a,Commutativity of ⊕\oplus: a⊕b=b⊕aa\oplus b=b\oplus a,

  • •

    ⊕\oplus 的结合律:a⊕(b⊕c)=(a⊕b)⊕ca\oplus(b\oplus c)=(a\oplus b)\oplus c,Associativity of ⊕\oplus: a⊕(b⊕c)=(a⊕b)⊕ca\oplus(b\oplus c)=(a\oplus b)\oplus c,

  • •

    ⊗\otimes 对 ⊕\oplus 的分配律:a⊗(b⊕c)=(a⊗b)⊕(a⊗c)a\otimes(b\oplus c)=(a\otimes b)\oplus(a\otimes c)。Distributivity of ⊗\otimes over ⊕\oplus: a⊗(b⊕c)=(a⊗b)⊕(a⊗c)a\otimes(b\oplus c)=(a\otimes b)\oplus(a\otimes c).

若一个集合配备一个满足结合律并具有单位元的二元运算,则称为幺半群;若其中每个元素都存在逆元,则称为群。环与半环的区别在于,后者只要求 (K,⊕)(\mathbb{K},\oplus) 和 (K,⊗)(\mathbb{K},\otimes) 构成幺半群,而不要求构成群。A set equipped with a binary operation supporting associativity and an identity element is called a monoid. A monoid such that every element has an inverse element is called a group. The difference between a ring and a semiring is that the latter only requires (K,⊕)(\mathbb{K},\oplus) and (K,⊗)(\mathbb{K},\otimes) to be monoids, not groups.

有了这些定义之后,我们便可以把 Viterbi 算法与前向—后向算法中的前向传播解释如下:Equipped with these definitions, we can interpret the forward passes in the Viterbi and forward-backward algorithms as follows:

  • •

    指数域中的前向—后向算法使用半环 R+\mathbb{R}_{+},该半环配备 (+,×)(+,\times) 以及单位元 (0,1)(0,1);the forward-backward algorithm in the exponential domain uses the semiring R+\mathbb{R}_{+} equipped with (+,×)(+,\times) and identity elements (0,1)(0,1);

  • •

    对数域中的 Viterbi 算法使用半环 R\mathbb{R},该半环配备 (max⁡,+)(\max,+) 以及单位元 (−∞,0)(-\infty,0);the Viterbi algorithm in the log domain uses the semiring R\mathbb{R} equipped with (max⁡,+)(\max,+) and identity elements (−∞,0)(-\infty,0);

  • •

    对数域中的前向—后向算法使用半环 R\mathbb{R},该半环配备 (max⁡ε,+)(\max_{\varepsilon},+) 以及单位元 (−∞,0)(-\infty,0),其中我们定义了软最大值算子(log-add-exp)the forward-backward algorithm in the log domain uses the semiring R\mathbb{R} equipped with (max⁡ε,+)(\max_{\varepsilon},+) and identity elements (−∞,0)(-\infty,0), where we defined the soft max operator (log-add-exp)

    maxε(a,b):=εlog⁡(exp⁡(a/ε)+exp⁡(b/ε)),\text{max}_{\varepsilon}(a,b)\coloneqq\varepsilon\log(\exp(a/\varepsilon)+\exp(b/\varepsilon)),

    默认取 ε:=1\varepsilon\coloneqq 1。with ε:=1\varepsilon\coloneqq 1 by default.

可以验证,maxε\text{max}_{\varepsilon} 确实是可交换的、可结合的,并且加法关于 maxε\text{max}_{\varepsilon} 满足分配律。其单位元为 −∞-\infty。由结合律可得It can be checked that indeed maxε\text{max}_{\varepsilon} is commutative, associative, and addition is distributive over maxε\text{max}_{\varepsilon}. Its identity element is −∞-\infty. By associativity,

maxε(a1,maxε(a2,a3))\displaystyle\text{max}_{\varepsilon}(a_{1},\text{max}_{\varepsilon}(a_{2},a_{3})) =logsumexpε(a1,a2,a3)\displaystyle=\mathrm{logsumexp}_{\varepsilon}(a_{1},a_{2},a_{3})
=εlog⁡∑iexp⁡(ai/ε).\displaystyle=\varepsilon\log\sum_{i}\exp(a_{i}/\varepsilon).

相比之下,请注意 13.5 节中的 sparsemax 并不满足结合律。In contrast, note that the sparsemax in Section 13.5 is not associative.

得益于结合律,我们可以引入如下简写记号Thanks to associativity, we can introduce the shorthand notations

maxεv∈V f(v):=εlog⁡∑v∈Vexp⁡(f(v)/ε)∈R.\underset{{\bm{v}}\in\mathcal{V}}{\text{max}_{\varepsilon}} \ f({\bm{v}})\coloneqq\varepsilon\log\sum_{{\bm{v}}\in\mathcal{V}}\exp(f({\bm{v}})/\varepsilon)\in\mathbb{R}.

以及and

argmaxεv∈V f(v):=(exp⁡(f(v′)/ε)/∑v∈Vexp⁡(f(v)/ε))v′∈V∈P(V).\underset{{\bm{v}}\in\mathcal{V}}{\text{argmax}_{\varepsilon}} \ f({\bm{v}})\coloneqq\left(\exp(f({\bm{v}}^{\prime})/\varepsilon)/\sum_{{\bm{v}}\in\mathcal{V}}\exp(f({\bm{v}})/\varepsilon)\right)_{{\bm{v}}^{\prime}\in\mathcal{V}}\in\mathcal{P}(\mathcal{V}).

借助半环的使用,许多算法都可以得到推广;参见 [4, 137] 等文献。分配律与结合律在把大型问题分解为较小问题方面起着关键作用 [201]。Many algorithms can be generalized thanks to the use of semirings; see among others [4, 137]. The distributive and associative properties play a key role in breaking down large problems into smaller ones [201].

10.9.3 推断即反向传播Inference as backpropagation

本节将说明,从算法角度看,回溯可作为反向传播的一种特例而得到。另见 [61, 132]。In this section, we show that, algorithmically, backtracking is recovered as a special case of backpropagation. See also [61, 132].

为简化记号,我们假设对所有 k∈[K]k\in[K] 都有 S0={1}\mathcal{S}_{0}=\{1\} 和 Sk={1,…,M}\mathcal{S}_{k}=\{1,\dots,M\}。我们重点关注如下情形For notation simplicity, we assume S0={1}\mathcal{S}_{0}=\{1\} and Sk={1,…,M}\mathcal{S}_{k}=\{1,\dots,M\} for all k∈[K]k\in[K]. We focus on the case

log⁡ψk(i,j)=⟨θk,ϕk(i,j)⟩=θk,i,j.\log\psi_{k}(i,j)=\langle{\bm{\theta}}_{k},\phi_{k}(i,j)\rangle=\theta_{k,i,j}.

我们还引入简写We also introduce the shorthands

a1,j\displaystyle a_{1,j} :=log⁡α1(j)=θ1,1,j\displaystyle\coloneqq\log\alpha_{1}(j)=\theta_{1,1,j}
ak,j\displaystyle a_{k,j} :=log⁡αk(j)=maxεi∈[M] θk,i,j+ak−1,i\displaystyle\coloneqq\log\alpha_{k}(j)=\underset{i\in[M]}{\text{max}_{\varepsilon}} \ \theta_{k,i,j}+a_{k-1,i}

以及and

qk,j:=argmaxεi∈[M] θk,i,j+ak−1,i.\displaystyle q_{k,j}\coloneqq\underset{i\in[M]}{\text{argmax}_{\varepsilon}} \ \theta_{k,i,j}+a_{k-1,i}.

我们的目标是计算下式关于 θ∈RK×M×M{\bm{\theta}}\in\mathbb{R}^{K\times M\times M} 的梯度Our goal is to compute the gradient w.r.t. θ∈RK×M×M{\bm{\theta}}\in\mathbb{R}^{K\times M\times M} of

log⁡Z=A=maxεj∈[M] aK,j.\log Z=A=\underset{j\in[M]}{\text{max}_{\varepsilon}} \ a_{K,j}.

该量的软 argmax 对应形式为The soft argmax counterpart of this quantity is

Q:=argmaxεj∈[M] aK,j∈△M,Q\coloneqq\underset{j\in[M]}{\text{argmax}_{\varepsilon}} \ a_{K,j}\in\triangle^{M},

其中我们使用了 P([M])=△M\mathcal{P}([M])=\triangle^{M}。where we used P([M])=△M\mathcal{P}([M])=\triangle^{M}.

计算 AA 的梯度与计算前馈网络的梯度类似,因为 θk{\bm{\theta}}_{k} 不仅影响 aka_{k},也影响 ak+1,…,aKa_{k+1},\dots,a_{K}。下面引入伴随变量Computing the gradient of AA is similar to computing the gradient of a feedforward network, in the sense that θk{\bm{\theta}}_{k} influences not only aka_{k} but also ak+1,…,aKa_{k+1},\dots,a_{K}. Let us introduce the adjoint variable

rk,i:=∂A∂ak,i,r_{k,i}\coloneqq\frac{\partial A}{\partial a_{k,i}},

我们将其初始化为which we initialize as

rK,i=∂A∂aK,i=Qi.r_{K,i}=\frac{\partial A}{\partial a_{K,i}}=Q_{i}.

由于 θk,i,j\theta_{k,i,j} 直接影响 ak,ja_{k,j},因此对于 k∈[K]k\in[K]、i∈[M]i\in[M] 和 j∈[M]j\in[M],有Since θk,i,j\theta_{k,i,j} directly influences ak,ja_{k,j}, we have for k∈[K]k\in[K], i∈[M]i\in[M] and j∈[M]j\in[M]

μk,i,j\displaystyle\mu_{k,i,j} :=∂A∂θk,i,j\displaystyle\coloneqq\frac{\partial A}{\partial\theta_{k,i,j}}
=∂A∂ak,j⋅∂ak,j∂θk,i,j\displaystyle=\frac{\partial A}{\partial a_{k,j}}\cdot\frac{\partial a_{k,j}}{\partial\theta_{k,i,j}}
=rk,j⋅qk,j,i.\displaystyle=r_{k,j}\cdot q_{k,j,i}.

由于 ak,ia_{k,i} 直接影响 ak+1,ja_{k+1,j}(对于 j∈[M]j\in[M]),因此对于 k∈{1,…,K−1}k\in\{1,\dots,K-1\} 和 i∈[M]i\in[M],有Since ak,ia_{k,i} directly influences ak+1,ja_{k+1,j} for j∈[M]j\in[M], we have for k∈{1,…,K−1}k\in\{1,\dots,K-1\} and i∈[M]i\in[M]

rk,i=∂A∂ak,i\displaystyle r_{k,i}=\frac{\partial A}{\partial a_{k,i}} =∑j∈[M]∂A∂ak+1,j∂ak+1,j∂ak,i\displaystyle=\sum_{j\in[M]}\frac{\partial A}{\partial a_{k+1,j}}\frac{\partial a_{k+1,j}}{\partial a_{k,i}}
=∑j∈[M]rk+1,jqk+1,j,i\displaystyle=\sum_{j\in[M]}r_{k+1,j}q_{k+1,j,i}
=∑j∈[M]μk+1,i,j.\displaystyle=\sum_{j\in[M]}\mu_{k+1,i,j}.

我们将这一流程总结为算法 3。前向传播使用 softmax 算子 maxε\text{max}_{\varepsilon} 与 softargmax 算子 argmaxε\text{argmax}_{\varepsilon}。在硬 max 情形下,算法 2 用 qq 存储从整数到整数的回溯指针;在软 max 情形下,算法 3 用 q{\bm{q}} 存储软回溯指针,即离散概率分布。在零温度极限下,反向传播给出的正是回溯解的二进制编码。We summarize the procedure in Algorithm 3. The forward pass uses the softmax operator maxε\text{max}_{\varepsilon} and the softargmax operator argmaxε\text{argmax}_{\varepsilon}. In the hard max case, in Algorithm 2, we used qq to store backpointers from integer to integer. In the soft max case, in Algorithm 3, we used q{\bm{q}} to store soft backpointers, that is, discrete probability distributions. In the zero-temperature limit, backpropagation outputs a binary encoding of the solution of backtracking.

算法 3 以带 max 算子的反向传播实现链上推断Algorithm 3 Inference on a chain as backprop with max operators
1: Input: θ∈RK×M×M{\bm{\theta}}\in\mathbb{R}^{K\times M\times M}
2: Max operator: max⁡ε\max_{\varepsilon}
3: Initialize a1,j:=θ1,1,j ∀j∈[M]a_{1,j}\coloneqq\theta_{1,1,j} \ \forall j\in[M]
4: for k:=2,…,Kk\coloneqq 2,\ldots,K do ▹\triangleright Forward pass
5:   for j∈[M]j\in[M] do
6:    ak,j:=maxεi∈[M] θk,i,j+ak−1,i∈Ra_{k,j}\coloneqq\underset{i\in[M]}{\text{max}_{\varepsilon}} \ \theta_{k,i,j}+a_{k-1,i}\in\mathbb{R}
7:    qk,j:=argmaxεi∈[M] θk,i,j+ak−1,i∈△M{\bm{q}}_{k,j}\coloneqq\underset{i\in[M]}{\text{argmax}_{\varepsilon}} \ \theta_{k,i,j}+a_{k-1,i}\in\triangle^{M}   
8: A:=maxεi∈[M] aK,i∈RA\coloneqq\underset{i\in[M]}{\text{max}_{\varepsilon}} \ a_{K,i}\in\mathbb{R}
9: Q:=argmaxεi∈[M] aK,i∈△M\bm{Q}\coloneqq\underset{i\in[M]}{\text{argmax}_{\varepsilon}} \ a_{K,i}\in\triangle^{M}
10: Initialize rK,j=Qjr_{K,j}=Q_{j} ∀j∈[K]\forall j\in[K]
11: for k:=K−1,…,1k\coloneqq K-1,\ldots,1 do ▹\triangleright Backward pass
12:   for i∈[M]i\in[M] do
13:    for j∈[M]j\in[M] do
14:      μk+1,i,j=rk+1,j⋅qk+1,j,i\mu_{k+1,i,j}=r_{k+1,j}\cdot q_{k+1,j,i}
15:      rk,i←rk,i+μk+1,i,jr_{k,i}\leftarrow r_{k,i}+\mu_{k+1,i,j}      
16: Outputs: max⁡εi1,…,iK∈[M]Kθ1,1,i1+∑k=2Kθk,ik−1,ik=A\underset{i_{1},\dots,i_{K}\in[M]^{K}}{\max_{\varepsilon}}\theta_{1,1,i_{1}}+\sum_{k=2}^{K}\theta_{k,i_{k-1},i_{k}}=A, ∇A(θ)=μ\nabla A({\bm{\theta}})=\mu

10.10 小结10.10 Summary

  • •

    图模型刻画变量之间的条件依赖关系,从而指明其联合分布如何分解。Graphical models represent the conditional dependencies between variables and therefore specify how their joint distribution factorizes.

  • •

    函数世界与分布世界之间有着清晰的类比:计算链与计算图,分别对应马尔可夫链与贝叶斯网络。There are clear analogies between the worlds of functions and of distributions: the counterparts of computation chains and computation graphs are Markov chains and Bayesian networks.

  • •

    对指数族分布而言,链上乃至更一般的树上的推断,无论在统计意义还是算法意义上,都等价于对对数配分函数求导。Inference on chains and more generally on trees, for exponential family distributions, is equivalent, both statistically and algorithmically, to differentiating the log-partition function.

  • •

    前向—后向算法可看作采用和—积代数,Viterbi 算法则可看作采用最大—加代数。等价地,在对数域中,前者可视为采用软最大值,后者可视为采用硬最大值。The forward-backward algorithm can be seen as using a sum-product algebra, while the Viterbi algorithm can be seen as using a max-plus algebra. Equivalently, in the log domain, we can see the former as using a soft max, and the latter as using a hard max.