第 17 章 二阶优化Chapter 17 Second-order optimization
本章回顾的方法,其迭代都具有如下形式:We review in this chapter methods whose iterations take the form
其中 为步长, 为包含二阶导数的预条件矩阵。where is a stepsize and is a pre-conditioning matrix involving second-order derivatives.
17.1 牛顿法17.1 Newton’s method
17.1.1 变分视角Variational perspective
我们在式 16.2 中看到,梯度下降可以从变分视角来解释:在该视角下,我们借助由当前梯度得到的目标函数在当前迭代值附近的线性近似。类似地,若我们不仅能取得目标函数的梯度,还能取得其 Hessian 矩阵,便可使用目标函数在当前迭代值附近的二次近似。更准确地说,给定函数 ,我们可以考虑极小化 在当前迭代值 附近的二阶泰勒近似:We saw in Eq. 16.2 that gradient descent can be motivated from a variational perspective, in which we use a linear approximation of the objective around the current iterate, obtained from the current gradient. Similarly, if we have access not only to the gradient but also to the Hessian of the objective, we can use a quadratic approximation of the objective around the current iterate. More precisely, given a function , we may consider minimizing the second-order Taylor approximation of around the current iterate ,
牛顿法所做的,正是围绕当前迭代值 反复极小化这一二次近似,即Newton’s method simply iteratively minimizes this quadratic approximation around the current iteration , namely,
| (17.1) |
若Hessian 矩阵在 处正定(记作 ),则该极小值点良定义且唯一(例如,当 为严格凸时即属此情形)。此时,迭代值可解析地写为If the Hessian is positive definite at , which we denote by , then the minimum is well-defined and unique (this is for example the case if is strictly convex). The iterates can then be written analytically as
若Hessian 矩阵并非正定,极小值就可能无定义。此时若无视这一问题而径直采用该解析表达式,则可能带来危险:例如,当该二次函数为严格凹(即 )时,这样做所算出的可能反而成了该二次函数的极大值。If the Hessian is not positive definite, the minimum may not be defined. Ignoring this issue and taking the analytical formulation could be dangerous, as it could amount to computing the maximum of the quadratic instead if, for example, the quadratic was strictly concave (i.e., ).
17.1.2 正则化牛顿法Regularized Newton method
规避这一问题的一种简单做法,是给 Hessian 矩阵添加一个正则化项。也就是说,从变分视角出发,我们可以加入邻近项 ,促使迭代值保持在当前 附近。于是,这种正则化牛顿法的迭代值具有如下形式:A simple technique to circumvent this issue consists in adding a regularization term to the Hessian. Namely, from a variational viewpoint, we can add a proximity term , encouraging it to stay close to the current . The iterates of this regularized Newton method then take the form
其中 控制正则化强度。假设 足够强,足以使 正定,则有where controls the regularization strength. Assuming is strong enough to make positive-definite, we have
其中我们定义了方向where we defined the direction
| (17.2) |
规避这一问题的其他技术还包括采用三次正则化,以及修改 Hessian 矩阵的谱分解——或对特征值作阈值处理,或取其绝对值。感兴趣的读者可参阅例如 [146, 211] 以了解详情。Other techniques to circumvent this issue include using cubic regularization and modifying the spectral decomposition of the Hessian, by thresholding the eigenvalues or taking their absolute values. We refer the interested reader to, e.g., [146, 211] for more details.
17.1.3 近似方向Approximate direction
我们注意到,实现这种二阶优化算法的一个主要障碍在于:即便我们能免费获取目标函数的 Hessian 矩阵,且该矩阵正定,要精确计算式 17.2 中的方向 ,仍需计算梯度 的逆 Hessian—向量乘积(IHVP)。而精确计算该乘积,需要求解一个线性方程组We observe a main impediment for implementing such a second-order optimization algorithm: even if we had access to the Hessian of the objective for free and this Hessian was positive definite, computing the exact direction in Eq. 17.2 requires computing an inverse-Hessian vector product (IHVP) with the gradient . Doing so exactly requires solving a linear system
这一求解原则上需要 时间。不过在实践中,我们可以近似计算 IHVP,具体如 9.4 节所述。which a priori takes time. In practice, however, we can compute IHVPs approximately, as explained in Section 9.4.
17.1.4 收敛性保证Convergence guarantees
实现牛顿法虽需付出更高的计算代价,却也能换来更快的收敛速率。简言之,若牛顿法从一个足够接近 -强凸函数极小值点 的点 出发,且该函数的Hessian 矩阵满足 -Lipschitz 连续性(即 ),则牛顿法以二次速率收敛 [146],即 (性能保证的简要介绍见 15.5 节)。这远胜于梯度下降。正是这种高效性推动了内点法的发展;借助对数障碍罚函数,内点法成为约束优化领域的一项突破 [146]。While implementing Newton’s method comes at a higher computational cost, it can also benefit from faster convergence rates. Briefly, if Newton’s method is initialized at a point close enough to the minimizer of a -strongly convex function with -Lipschitz continuous Hessian (namely ), then Newton’s method converges at a quadratic rate [146], that is, (see Section 15.5 for a brief introduction to performance guarantees). This is far superior to gradient descent. Such an efficiency motivated the development of interior point methods, that have been a breakthrough in constrained optimization, thanks to the use of log-barrier penalties [146].
17.1.5 线搜索Linesearch
实践中,我们未必能获得足够接近极小值点的初始点。此时,即便对于严格凸函数——牛顿步对其是良定义的——取 也未必能保证目标值下降。不过,方向 仍可能按下文定义构成一个下降方向。In practice, we may not have access to an initial point close enough to the minimizer. In that case, even for strictly convex functions for which Newton’s steps are well-defined, taking may not ensure a decrease of the objective values. Nevertheless, the direction may define a descent direction as defined below.
定义 17.1.1(下降方向)。Definition 17.1.1 (Descent direction).
对于未加正则化的牛顿法,只要 且 ,则 就是 处的一个下降方向。若 ,则选取 使 ,同样能保证 是下降方向(只要 )。于是,牛顿法通常会配合一种线搜索方法,该方法试图取如下形式的步长For Newton’s method without regularization, is then a descent direction at , as long as and . If , choosing such that , also ensures that is a descent direction (as long as ). Newton’s method is then generally equipped with a linesearch method that attempts to take steps of the form
其中 取为 (对 )中使目标函数满足充分下降条件(例如对 有)的最大步长,with chosen as the largest stepsize among for until a sufficient decrease of the objective is satisfied such as, for ,
对于强凸函数,这种实现会分为两个阶段:第一阶段用步长 对牛顿步进行“阻尼”;第二阶段则超快收敛,此时步长取 ,目标函数迅速下降。即便离最优点很远,牛顿方向也能适应目标函数的局部几何,从而比常规梯度下降更快收敛,详见下文。For strongly convex functions, such an implementation exhibits two phases: a first phase during which Newton’s steps are “damped” by using a stepsize and a second phase of super-fast convergence during which stepsizes are taken, and the objective decreases very fast. Even far from the optimum, Newton directions can advantageously adapt to the local geometry of the objective to speed up convergence compared to a regular gradient descent as explained below.
17.1.6 几何解释Geometric interpretation
为理解牛顿法相对于梯度下降的高效性,考虑一个简单二次函数的最小化问题To understand the efficiency of Newton’s method compared to gradient descent, consider the minimization of a simple quadratic
对于 ,如图 17.1 所示。梯度下降沿 的方向移动,其步长受第一个坐标变化的制约,因而产生振荡。若仅用 对梯度作缩放,即取如下形式的步长for , as illustrated in Fig. 17.1. A gradient descent moves along the directions and its stepsize is limited by the variations in the first coordinate leading to some oscillations. If we were simply rescaling the gradient by , i.e., taking steps of the form
则两个坐标上的变化都归一为一,步长可直接取 ,从而直接得到 。换言之,让方向的几何结构与目标函数诱导的几何结构相匹配,便能绕开振荡。the variations in both coordinates would be normalized to one and the stepsize could simply be chosen to to directly get . In other words, by adapting the geometry of the directions with the geometry induced by the objective, we can circumvent the oscillations.
牛顿法正是如此:它借助 Hessian 矩阵的逆来修正梯度方向。形式上,在第 次迭代时,考虑修改后的目标函数That’s exactly what Newton’s method does by modifying the gradient direction using the inverse of the Hessian. Formally, at iteration , consider the modified objective
其中 严格凸, 为 Hessian 矩阵的逆矩阵平方根。不难验证,牛顿步等价于在 上做梯度步,即with strictly convex and the inverse matrix square root of the Hessian. One easily verifies that a Newton step is equivalent to a gradient step on , that is,
其中where
在 诱导的几何结构下,目标函数通常具有更好的条件数,如图 17.1 所示。这正是牛顿法高效的原因。特别地,对任意强凸二次函数,一次牛顿步即可在一次迭代中抵达最优点,而梯度步则可能需要多得多的迭代。In the geometry induced by , the objective is generally better conditioned as illustrated in Fig. 17.1. This explains the efficiency of Newton’s method. In particular for any strongly convex quadratic, a Newton step reaches the optimum in one iteration, while a gradient step can take many more iterations.
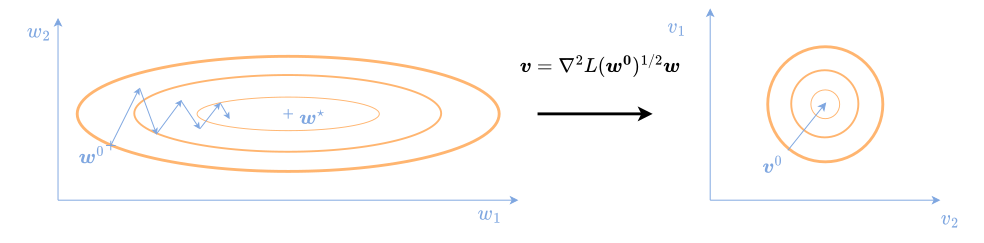
17.1.7 随机牛顿法Stochastic Newton’s method
现在考虑一个期望损失Consider now an expected loss
此时,可以仿照构造梯度估计的方式构造Hessian 矩阵的估计,依据是In that case, an estimate of the Hessian can be constructed just like for the gradient using that
于是记Les us then denote
它们分别是梯度与Hessian 矩阵的某种随机估计,其中 独立地采自 ,或来自小批量大小各异的小批量近似。随机牛顿法的一种实现如下:some stochastic estimates of the gradient and the Hessian, respectively, with independently drawn from or from mini-batch approximations with varying mini-batch sizes. One implementation of a stochastic Newton method can then be
其中 满足 ,且 固定不变,或按某个充分下降条件选取。更多细节与变体,请感兴趣的读者参阅例如 [212]。for such that and fixed or chosen to satisfy some sufficient decrease condition. We refer the interested reader to, e.g., [212], for more details and variants.
17.2 Gauss-Newton 方法17.2 Gauss-Newton method
牛顿法(17.1)对于非凸目标函数通常并没有良定义,因为 Hessian 矩阵在当前迭代值处可能不是正定的。我们在 9.2 节已经看到,Gauss-Newton 矩阵可用来定义 Hessian 矩阵的一个半正定近似。这里,我们从变分视角与部分线性化视角重新审视 Gauss-Newton 方法。虽然最初的 Gauss-Newton 方法源自非线性最小二乘,我们仍先描述它对任意凸损失函数的推广,因为这种表述既更具一般性,也更容易解释。Newton’s method (17.1) is usually not properly defined for non-convex objective functions, since the Hessian may not be positive definite at the current iterate. We saw in Section 9.2 that the Gauss-Newton matrix can be used to define a positive-semidefinite approximation of the Hessian. Here, we revisit the Gauss-Newton method from a variational and partial linearization perspective. While the original Gauss-Newton method originates from nonlinear least-squares, we will first describe an extension to arbitrary convex loss functions, since it is both more general and easier to explain.
17.2.1 外层函数精确已知的情形With exact outer function
考虑如下形式的复合目标函数Consider a composite objective of the form
其中 是凸函数,例如作用在给定样本上的凸损失函数; 是非线性函数,例如参数为 的神经网络,并在同一样本上求值。我们已经看到,梯度下降与牛顿法分别相当于在当前迭代值 附近对 使用线性近似与二次近似。作为两者之间的折中,Gauss-Newton 方法使用 在 附近的线性化where is a convex function, such as a convex loss function applied on a given sample, and is a nonlinear function, such as a neural network with parameters , evaluated on the same sample. We saw that gradient descent and Newton’s method amount to using linear and quadratic approximations of around the current iterate , respectively. As a middle ground between the two, the Gauss-Newton method uses the linearization of around
但保持 不变,从而得到目标函数but keeps as is to obtain the objective
其中我们定义了简写 与 。我们把 称为 在 处的部分线性化,以区别于梯度下降中所使用的 的完全线性化。where we defined the shorthands and . We call the partial linearization of at , as opposed to the full linearization of used in gradient descent.
由于凸函数与线性函数的复合仍是凸函数,因此即便 是非凸的,该目标函数也是凸的。实践中,我们常常加入一个邻近项作为正则化,从而定义Since the composition of a convex function and of linear function is convex, this objective is convex even if is nonconvex. In practice, we often add a proximity term as regularization to define
| (17.3) |
我们可以把这一更新视为对邻近点更新的近似We can see this update as an approximation of the proximal point update
其中 已被替换为其部分线性化。用基于梯度的求解器求解式 17.3,需要计算 的梯度,即 。因此,用自动微分计算该梯度需要执行一次前向传播来计算 JVP ,再执行一次反向传播来计算 VJP 。关于这些算子的介绍见 2.3 节,关于自动微分的介绍见第 8 章。where has been replaced by its partial linearization. Solving Eq. 17.3 using gradient-based solvers requires computing the gradient of , which is . Computing this gradient by autodiff therefore requires performing a forward pass to compute the JVP and a backward pass to compute the VJP . See Section 2.3 for an introduction to these operators and Chapter 8 for an introduction to autodiff.
带任意凸外层损失的 Gauss-Newton 方法,常被称为修正 Gauss-Newton 方法 [145] 或 prox-linear 方法 [57]。经典的 Gauss-Newton 方法与 Levenberg-Marquardt 方法 [118, 126] 源自非线性最小二乘,当 为二次函数时,便可还原出这两种方法 [105],例如 ,其中 为某个参考目标。在经典意义上,Gauss-Newton 方法对应于不使用正则化的情形(即 ),而 Levenberg-Marquardt 法则使用了正则化(通常称为阻尼,并可能在不同迭代中改变 )。关于各种变体,可参见例如 [133] 的综述。The Gauss-Newton method with arbitrary convex outer loss is often called modified Gauss-Newton [145] or prox-linear [57]. The classical Gauss-Newton and Levenberg-Marquardt [118, 126] methods originate from nonlinear least-squares and are recovered when is quadratic [105], such as , for some reference target. The Gauss-Newton method corresponds classically to not using regularization (i.e., ) and the Levenberg-Marquardt method uses regularization (usually called damping, potentially changing across iterations). See e.g., [133], for a survey of different variants.
17.2.2 外层函数取近似的情形With approximate outer function
Gauss-Newton 方法的另一种变体,是把凸损失 替换为它在 附近的二次近似,Another variant of the Gauss-Newton method consists in replacing the convex loss with its quadratic approximation around ,
由此定义如下更新to define the update
注意,此处已将 替换为其二次近似 。该目标始终为凸二次函数;相比之下,式 17.1 中牛顿法的目标函数在 为非线性时,先验地是一个非凸二次函数。简单的计算表明Notice that has been replaced by its quadratic approximation . This objective is always a convex quadratic, unlike the objective of the Newton method in Eq. 17.1, which is a priori a nonconvex quadratic, if is nonlinear. Simple calculations show that
其中 。其闭式解为where The closed form solution is
这里我们使用了 的(广义)Gauss-Newton 矩阵,该矩阵的定义见 9.2 节。where we used the (generalized) Gauss-Newton matrix of , defined in Section 9.2.
17.2.3 线搜索Linesearch
与牛顿法类似,Gauss-Newton 方法若单独使用,其迭代值也可能发散。不过,方向 对任意 都构成下降方向,并且可以与步长 (通常通过线搜索选取)结合,得到如下形式的迭代值Similarly to Newton’s method, the iterates of a Gauss-Newton method may diverge when used alone. However, the direction defines a descent direction for any and can be combined with a stepsize (typically chosen using a linesearch) to obtain iterates of the form
17.2.4 随机 Gauss-NewtonStochastic Gauss-Newton
在深度学习中,目标函数通常由损失函数与网络函数的复合关于样本的期望构成:In deep learning, the objective generally consists in an expectation over samples of the composition between a loss function and a network function:
其中 表示由输入 及其对应标签 构成的样本对。此时,正如 9.2 节已讨论过的,Gauss-Newton 矩阵 是各个 Gauss-Newton 矩阵的期望where denotes a sample pair of input with associated label . In that case, as already studied in Section 9.2, the Gauss-Newton matrix is the expectation of the individual Gauss-Newton matrices
我们可以分别用 和 来估计梯度与 Gauss-Newton 矩阵,其中 ,或改用小批量近似。因此,随机 Gauss-Newton 方法执行的迭代为We can estimate the gradient and the Gauss-Newton matrix by, respectively, , and for or using mini-batch approximations. A stochastic Gauss-Newton method therefore performs iterates
其中 与 保持固定,或按某种准则加以选取。for and fixed or selected to satisfy some criterion.
17.3 自然梯度下降17.3 Natural gradient descent
自然梯度下降[5]遵循与梯度下降类似的准则:在当前迭代值附近对目标函数作线性化,并最小化该近似与一个邻近项之和。它与梯度下降的不同之处在于邻近项的选取:它不采用参数间的平方欧几里得距离,而采用这些参数所定义的概率分布之间的 Kullback-Leibler 散度。Natural gradient descent [5] follows a similar principle as gradient descent: linearize the objective around the current iterate and minimize this approximation together with a proximity term. It differs from gradient descent in the choice of the proximity term: rather than using a squared Euclidean distance between the parameters, it uses a Kullback-Leibler divergence between the probability distributions these parameters define.
负对数似然Negative log-likelihood
我们考虑如下形式的目标函数:We consider objectives of the form
其中 是未知的数据分布(但我们可以从中采样), 则是由 参数化的概率分布。如第 3 章所述,负对数似然可用作损失函数(许多损失函数都可由此视角理解,其中包括平方损失函数与 logistic 损失函数)。在无监督设定中,即 ,我们直接按原样使用 。在有监督设定中,即 ,我们借助乘积法则 ,将 参数化为where is an unknown data distribution (but from which we can sample) and where is a probability distribution parameterized by . As reviewed in Chapter 3, the negative log-likelihood can be used as a loss function (many loss functions can be seen from this perspective, including the squared and logistic loss functions). In the unsupervised setting, where , we simply use as is. In the supervised setting, where , we use the product rule to parameterize as
其中 是 的边缘分布, 是某一概率分布的 PMF/PDF,而 例如是一个神经网络,其参数为 、输入为 。where is the marginal distribution for , is the PMF/PDF of a probability distribution and is for instance a neural network with parameters and input .
17.3.1 变分视角Variational perspective
自然梯度下降的出发点,是如下形式的更新:Natural gradient descent is motivated by updates of the form
其中 为 Kullback-Leibler(KL)散度。因此,与梯度下降不同,这里的邻近项衡量的是当前分布 与候选概率分布 之间的差异。上述问题在一般情况下难以求解,因为 KL 散度可能没有闭式形式。不过可以证明[5],其二次近似具有如下简洁形式:where is the Kullback-Leibler (KL) divergence. Unlike gradient descent, the proximity term is therefore between the current distribution and a candidate probability distribution . The above problem is intractable in general, as the KL may not have a closed form. Nevertheless, its quadratic approximation can be shown [5] to admit a simple form,
其中用到了 9.3 节所研究的 Fisher 信息矩阵 。有了 KL 散度的这一二次近似,自然梯度下降便相当于按如下方式计算迭代值:where we used the Fisher information matrix , studied in Section 9.3. Equipped with this quadratic approximation of the KL divergence, natural gradient descent amounts to computing iterates as
其中加入了二次邻近项,以保证解唯一。由于 半正定,因此这是一个严格凸问题。其闭式解为where a quadratic proximity term was added to ensure a unique solution. This is a strictly convex problem as is positive semi-definite. The closed-form solution is
由于当 为指数族分布时,Gauss-Newton 矩阵与 Fisher 信息矩阵等价(命题 9.3.5),因此在这种情况下,Gauss-Newton 方法与自然梯度方法彼此一致。Because the Gauss-Newton and Fisher information matrices are equivalent when is an exponential family distribution (Proposition 9.3.5), the Gauss-Newton and natural gradient methods coincide in this case.
17.3.2 随机自然梯度下降Stochastic natural gradient descent
在实践中, 是关于 的期望,我们未必能获得其闭式形式;此外, 也可能无法以闭式形式计算。为估计 Fisher 信息矩阵,我们可以利用(见 9.3 节)如下简写 ,In practice, we may not have access to in closed form as it is an expectation over . Moreover, may not be computable in closed form either. To estimate the Fisher information matrix, we can use that (see Section 9.3) using the shorthand ,
然后,我们可以基于从 中采样得到的 ,以及从 中采样得到的 ,构建估计量 与 。随机自然梯度下降便可按如下方式实现:We can then build estimates and for sampled from and sampled from . A stochastic natural gradient descent can then be implemented as
其中 是步长,可由线搜索选取。where is a stepsize, possibly chosen by linesearch.
在深度学习中,与 Fisher 矩阵或 Gauss-Newton 矩阵之逆相乘的计算代价可能仍然很高。为此,人们已经提出了若干近似方法,例如 KFAC [128, 31],它利用计算效率高的结构近似来逼近这些矩阵。In deep learning, the product with the inverse Fisher or Gauss-Newton matrices can remain costly to compute. Several approximations have been proposed, such as KFAC [128, 31], which uses a computationally efficient structural approximation to these matrices.
17.4 拟牛顿法17.4 Quasi-Newton methods
17.4.1 BFGSBFGS
拟牛顿法的一个著名例子是 BFGS 方法 [37, 67, 80, 183],其缩写来自其作者的名字。BFGS 更新的依据再次源于变分观点。我们希望为目标 建立一个简单的二次模型,所用的某个 是沿迭代过程构造出来的,而不是取作 。这种二次模型的一个理想性质是,其在相邻迭代点处的梯度与原函数的梯度相匹配,即 和 。一个更简单的条件称为割线条件,它在于考虑这些向量的差,也就是确保A celebrated example of quasi-Newton method is the BFGS method [37, 67, 80, 183], whose acronym follows from its authors’ names. The rationale of the BFGS update stems once again from a variational viewpoint. We wish to build a simple quadratic model of the objective for some built along the iterations rather than taken as . One desirable property of such a quadratic model would be that its gradients at consecutive iterates match the gradients of the original function, i.e., and . A simpler condition, called the secant condition consists in considering the differences of these vectors, that is, ensuring that
对于 。接着,可按如下方式构建满足割线方程的 ,即 Hessian 矩阵之逆的替代量:for . Building , a surrogate of the inverse of the Hessian satisfying the secant equation, can then be done as
其中where
BFGS 的一种典型实现会在内存中存储 ;当 很大时,这种做法的内存开销会大得令人却步。A typical implementation of BFGS stores in memory, which is prohibitive when is large.
17.4.2 有限内存 BFGSLimited-memory BFGS
在实践中,人们往往更青睐 BFGS 的有限内存版本,即 LBFGS [119]。LBFGS 的关键观察是,我们并不需要在内存中具体化 :我们只需要将其与梯度 相乘即可,也就是说,可以把 视为一个线性映射。幸运的是,只要在内存中存储 ,就能高效地计算 与任意向量 的乘积。实践中,人们会利用过去取值的一小段历史来降低内存与计算代价。由于 LBFGS 兼具类二阶方法的好处而代价大大降低,它已成为事实上的标准算法,对于没有特殊结构的中等规模问题,其表现优于大多数其他算法 [119]。In practice, the limited-memory counterpart of BFGS, called LBFGS [119], is often preferred. The key observation of LBFGS is that we do not need to materialize in memory: we only need to multiply it with the gradient . That is, we can see as a linear map. Fortunately, the product between and any vector can be computed efficiently if we store in memory. In practice, a small history of past values is used to reduce memory and computational cost. Because LBFGS has the benefits of second-order-like methods with much reduced cost, it has become a de-facto algorithm, outperforming most other algorithms for medium-scale problems without particular structure [119].
17.5 近似 Hessian 对角逆预条件矩阵17.5 Approximate Hessian diagonal inverse preconditioners
9.7 节中所发展的Hessian 矩阵对角线近似方法,其应用之一是获得Hessian 矩阵对角线逆的一种廉价近似,One application of the approximations of the Hessian diagonal developed in Section 9.7 is to obtain cheap approximations of the Hessian diagonal inverse,
这样的缩放足以让图 17.1 中的二次函数示例顺利运行。许多优化算法——包括流行的 ADAM——都可以被视为使用了某种基于近似 Hessian 对角逆的预条件矩阵。Such a scaling would for instance be sufficient to make the quadratic example presented in Fig. 17.1 work. Many optimization algorithms, including the popular ADAM, can be viewed as using a preconditioner that approximates the inverse of the Hessian’s diagonal.
17.6 小结17.6 Summary
- •
我们回顾了牛顿法、Gauss-Newton 方法、自然梯度下降法、拟牛顿法以及预条件方法。We reviewed Newton’s method, the Gauss-Newton method, natural gradient descent, quasi-Newton methods and preconditioning methods.
- •
我们采用变分视角:该方法的下一迭代值,取为使函数近似(线性、部分线性或二次)的极小化与邻近项(平方欧几里得或 KL)之间达到权衡的解。We adopted a variational viewpoint, where the method’s next iterate is computed as the solution of a trade-off between minimizing an approximation of the function (linear, partially linear, quadratic) and a proximity term (squared Euclidean, KL).
- •
已经证明,所有方法使用的迭代值都具有如下形式All methods were shown to use iterates of the form
但它们在计算 的代价,以及所用关于 的信息丰富程度之间,有着不同的权衡。but have different trade-offs between the cost it takes to evaluate and the richness of the information used about .