第 16 章 一阶优化Chapter 16 First-order optimization
16.1 梯度下降16.1 Gradient descent
梯度下降是我们工具箱中用于最小化函数的最简单的算法之一。在每次迭代中,它沿负梯度方向移动,并由步长 缩放:Gradient descent is one of the simplest algorithms in our toolbox to minimize a function. At each iteration, it moves along the negative gradient direction, scaled by a stepsize :
| (16.1) |
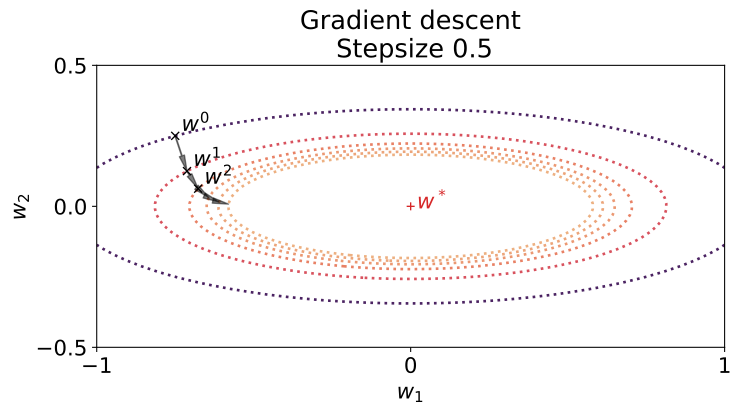
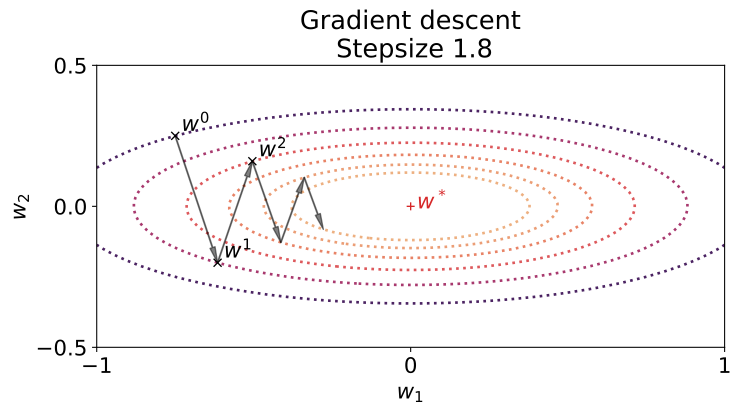
梯度下降在一个简单二次函数上所走过的路径如图 16.1 所示,图中针对不同的步长选择给出了相应的轨迹。The path taken by a gradient descent on a simple quadratic is illustrated in Fig. 16.1 for different choices of the stepsize.
16.1.1 变分视角Variational perspective
考虑 在 附近的线性近似,Consider the linear approximation of around ,
容易验证,式 16.1 中的梯度下降更新可以改写为如下极小化问题的解,即:One can easily check that the gradient descent update in Eq. 16.1 can be rewritten as the solution of a minimization problem, namely,
| (16.2) |
用文字来说,梯度下降的一次更新优化了这样一个权衡:一方面借助邻近项 保持与当前 接近,另一方面极小化 在 附近的线性化。直观上,只要选取足够小的 ,就能保证正则化线性近似的极小值点仍落在该线性近似有效的邻域内。这一视角有助于引出梯度下降的各种推广。In words, a gradient descent update optimizes a trade-off between staying close to the current , thanks to the proximity term , and minimizing the linearization of around . Intuitively, by choosing sufficiently small, we ensure that the minimizer of the regularized linear approximation stays in a neighborhood where the linear approximation is valid. This viewpoint is useful to motivate gradient descent extensions.
16.1.2 光滑函数的收敛性Convergence for smooth functions
只要 ,函数 在 0 处的导数就为负,即 。因此,只要 ,就存在一个步长,使得每次迭代的目标函数值都下降。然而,若没有进一步的假设,这样的步长可能依赖于每一次迭代,并且可能小到无穷小。为了定量刻画采用常数步长的梯度下降的收敛性,我们限定在光滑函数类中讨论。对梯度下降的迭代值应用命题 15.4.4,可得As long as , the function has a negative derivative at 0, i.e., . Hence, as long as , there exists a stepsize ensuring a decrease in objective values at each iterate. However, without further assumptions, such a stepsize may depend on each iterate and may be infinitesimally small. To quantify the convergence of gradient descent with a constant stepsize, we restrict to the class of smooth functions. By applying Proposition 15.4.4 on the iterate of gradient descent, we obtain that
因此,对于 -光滑函数,选取 ,便有Therefore, for -smooth functions, by selecting , we get that
这揭示了梯度下降背后的主要机制:每一次迭代都使目标函数值下降一个常数乘以当前迭代值的梯度范数。该式还可以对所有直至 的迭代求和。这样目标函数值便相互抵消,从而得到which illustrates the main mechanism behind gradient descent: each iteration decreases the objective by a constant times the norm of the gradient of the current iterate. This equation can further be summed over all iterates up to . This telescopes the objective values, leading to
其中回顾 是 的下确界。因此,经过足够多次迭代后,梯度下降会找到一个梯度范数任意小的点。where we recall that is the infimum of . Therefore, after sufficiently many iterations, gradient descent finds a point whose gradient norm is arbitrarily small.
非凸情形Non-convex case
在没有进一步假设的情况下,即在非凸情形下,上述结果(即通过梯度范数度量的、收敛到驻点)在理论上已是我们所能得到的最好结果。记 为梯度下降输出一个 -驻点(即 )所需的迭代次数,则有 。Without further assumptions, i.e., in the non-convex case, the above result (i.e., convergence to a stationary point, measured by the gradient norm) is the best we may get in theory. Denoting the number of iterations needed for a gradient descent to output a point that is -stationary, i.e., , we have .
凸情形Convex case
通过对目标函数添加凸性假设,我们便可以利用凸性假设所提供的下界来确保收敛到极小值。具体而言,对于 -光滑且凸的函数 ,并取步长 ,有 [146]By adding a convexity assumption on the objective, we can use the lower bound provided by the convexity assumption to ensure convergence to a minimum. Namely, for a -smooth and convex function , and with stepsize , we have that [146]
也就是说,我们得到了次线性收敛速率,而找到极小值所对应的计算复杂度为 。That is, we get a sublinear convergence rate, and the associated computational complexity to find a minimum is .
强凸情形Strongly convex case
如果我们进一步加强假设,考虑 -光滑、-强凸的函数,则可以证明,对于任意步长 ,梯度下降的收敛速率为 [146],If we further strengthen the assumptions by considering -smooth, -strongly convex functions, the convergence rate of a gradient descent can be shown to be [146], for any stepsize ,
也就是说,我们得到线性收敛速率,相应的计算复杂度为 。上述收敛速率还可以进一步细化 [146];为清晰起见,我们上文只关注了最简单的结果。That is, we obtain a linear convergence rate and the associated computational complexity is . The above convergence rates may be further refined [146]; we focused above on the simplest result for clarity.
强凸性也可以替换为一个更弱的假设,即梯度支配性质 [158],也就是说,对于某个常数 和任意 ,有 。凸的、满足梯度支配性质的函数同样可以以线性速率被极小化。Strong convexity can also be replaced by a weaker assumption, gradient-dominating property [158], i.e., for some constant and any . A convex, gradient-dominating function can also be minimized at a linear rate.
16.1.3 动量与加速变体Momentum and accelerated variants
我们从梯度下降这一一阶优化算法的简单示例出发。然而,根据所能获得的一阶 oracle 以及对所考虑函数类的了解,可以设计出不同的优化算法。例如,考虑二次凸函数 ;若 为正定矩阵,则它们是光滑强凸函数的一个基本例子。在这种情况下,一个最优方法是 [159] 的重球法,它可以写成We started with gradient descent as a simple example of first-order optimization algorithm. However, different optimization algorithms can be designed from the access to first-order oracles and the knowledge of the class of functions considered. For example, consider quadratic convex functions , that are a basic example of smooth strongly convex functions if is positive definite. An optimal method in this case is the heavy-ball method of [159], that can be written as
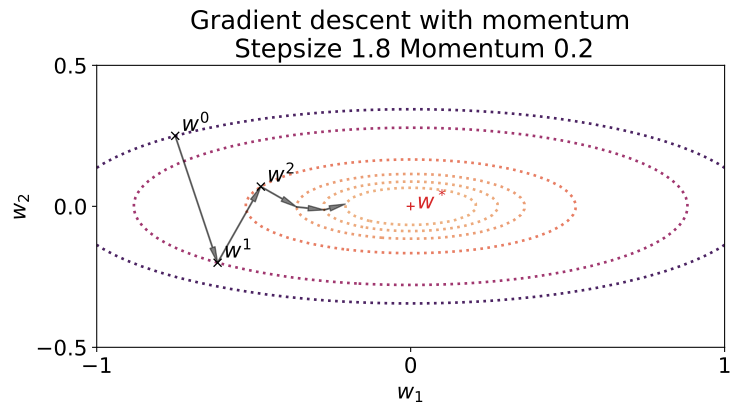
重球法使用了一个额外的变量 ,它可以被解释为一个由负梯度驱动的、朝着极小值收敛的小球的速度。直观地说,这个额外的速度避免了梯度下降可能出现的振荡,如图 16.2 与图 16.1 的对比所示。当 时,我们恢复出通常的梯度下降。当 时,这些速度累积成一种惯性动量的形式,其中 被解释为小球的“质量”。就收敛速率而言,可以证明重球法与梯度下降类似地线性收敛,但在适当选取 时,其速率为 。相比之下,通过为梯度下降选取最优步长,其收敛速率为 ,而这一速率可证明更差,因为我们总有 。The heavy-ball method uses an additional variable , that can be interpreted as the velocity of a ball driven by the negative gradient to converge towards a minimum. Intuitively, this additional velocity circumvents the oscillations that a gradient descent may present as illustrated in Fig. 16.2 compared to Fig. 16.1. For , we recover usual gradient descent. For , the velocities accumulate a form of an inertia momentum, where is interpreted as the “mass” of the ball. In terms of convergence rates, the heavy-ball method can be shown to converge linearly similarly to gradient descent, but with a rate for appropriate choices of . In comparison, by choosing an optimal stepsize for the gradient descent, its convergence rate is which is provably worse, as we always have .
除二次函数的情形之外,[146] 还针对凸函数或强凸函数开发了梯度下降的加速变体。这类变体启发了下文所介绍的随机设定下优化算法的设计。Beyond the case of quadratic functions, accelerated variants of gradient descent for convex or strongly convex functions have been developed by [146]. Such variants have inspired the design of optimization algorithms in stochastic settings presented below.
16.2 随机梯度下降16.2 Stochastic gradient descent
在机器学习中,我们通常希望最小化模型在数据分布 上的期望损失:In machine learning, we are usually interested in minimizing the expected loss of the model over the data distribution :
例如, 通常取为 ,其中 是损失函数, 是神经网络,而 是从 中采样得到的随机对,由一个输入 及与之关联的目标 组成。在这种设定下,数据分布 通常是未知的,而且可能具有无穷的支撑集,因此我们无法精确计算期望损失 或其梯度 。For example, is often set to , where is a loss function, is a neural network and is a random pair, composed of an input and an associated target , sampled from . In this setting, since the data distribution is generally unknown and may be infinite, we cannot exactly evaluate the expected loss or its gradient .
在实践中,我们通常给定一个包含 个对 的固定数据集。这是期望损失设定的一种特殊情形,因为可以将其视为经验分布 In practice, we are often given a fixed dataset of pairs . This is a special case of the expected loss setting, since this can be seen as an empirical distribution
于是, 的梯度为The gradient of is then
在这种情况下可以看到,梯度下降所需的完整梯度 是各个体梯度的平均。也就是说,计算 的代价与训练点的数目 成正比。当 极大,即样本量极大时,这一计算代价可能高得令人却步。随机梯度则绕开了这一难题。In this case, we see that the full gradient , as needed by gradient descent, is the average of the individual gradients. That is, the cost of computing is proportional to the number of training points . For very large, that is a very large amount of samples, this computational cost can be prohibitive. Stochastic gradients circumvent this issue.
16.2.1 随机梯度Stochastic gradients
通常,即便我们并不知道 ,也仍可从中采样,也就是说,我们能够获得样本 。于是,便可将形如 的随机梯度用作 的随机估计。这看似只是一个粗略的估计,但平均而言,它是有效的近似,因为Usually, even if we do not know , we can sample from it, i.e., we have access to samples . We can then use a stochastic gradient of the form as a random estimate of . This may look like a rough estimate but, on average, this is a valid approximation since
我们称 为 的无偏估计量。为进一步改善近似,还可以考虑小批量估计:采样 个数据点 ,并采用 ,其期望仍与 相符,同时通过对多个随机梯度取平均,还可能减小近似误差。从计算角度看,其主要优势在于代价现在与 成正比,而非与 成正比。We say that is an unbiased estimator of . To further improve the approximation, we may also consider mini-batch estimates by sampling data points and using , whose expectation still matches , while potentially reducing the approximation error by averaging multiple stochastic gradients. Computationally, the main advantage is that the cost is now proportional to instead of .
在最一般的情况下,可以考虑下文所定义的随机一阶 oracle。In whole generality, one can consider stochastic first-order oracles defined below.
定义 16.2.1(随机一阶 oracle)。Definition 16.2.1 (Stochastic first-order oracles).
当 时,即得到随机梯度;当 是按 独立抽取的 个样本的乘积时,则得到小批量随机梯度。一阶随机优化算法以随机一阶 oracle 为基础,近似地求期望目标函数的最小值。在这种设定下,算法的迭代值按定义即是随机的。因此,收敛速率需要以概率的方式表述,例如考察针对 oracle 随机性所取的期望目标值。When , we recover stochastic gradients. When is the product of independent samples according to , we recover mini-batch stochastic gradients. First-order stochastic optimization algorithms build upon stochastic first-order oracles to approximately find the minimum of the expected objective. In such a setting, the iterates of the algorithm are by definition random. Convergence rates therefore need to be expressed in probabilistic terms by considering for example the expected objective value according to the randomness of the oracles.
16.2.2 朴素 SGDVanilla SGD
有了随机一阶 oracle(例如(小批量)随机梯度),我们便可将随机梯度下降定义为Equipped with a stochastic first-order oracle, such as (mini-batch) stochastic gradients, we can define stochastic gradient descent as
我们假设 与 相互独立。与通常的梯度下降相比,随机设定下的主要障碍在于随机估计所引入的额外噪声,即其方差。We assume that is independent of . Compared to the usual gradient descent, the main impediment of the stochastic setting is the additional noise induced by the stochastic estimates: their variance.
例如,考虑对 -光滑凸函数 的期望施加随机梯度下降,并使用无偏 oracle。为利用迭代值的随机性,可考虑在 次迭代后输出前 个迭代值的平均,即 。此外,假设对 的所有极小值点 ,随机一阶 oracle 的方差都以 为界。以 表示与随机 oracle 关联的随机性,则在步长为 时 [115],有For example, consider applying a stochastic gradient descent on the expectation of -smooth convex functions with unbiased oracles. To harness the randomness of the iterates, consider after iterations outputting the average of the first iterates, that is . Moreover, suppose that the variance of the stochastic first-order oracles is bounded by for all minimizers of . Denoting by the randomness associated to the stochastic oracles, we have then that for a stepsize [115],
所得的收敛速率表明,随机梯度下降会收敛到期望目标函数的最小值,但相差一个依赖于 oracle 方差与步长的常数项。人们可以通过采用小批量来减小该方差:若单个随机梯度的方差为 ,则由 个梯度组成的小批量会将相应 oracle 的方差降低为 。为减小这一附加项,也可以在迭代过程中逐渐减小步长。例如,通过选择如 这样的递减步长,收敛速率便为 量级。步长也可以取为常数 ,它使前 次迭代的平均目标值下降,并以固定间隔乘以一个乘性因子,例如对 取 ,以处理 之间的迭代。诸如余弦衰减 [122] 之类的其他步长调度方案近来也颇为流行。The resulting convergence rate illustrates that a stochastic gradient descent converges to the minimum of the expected objective up to a constant term depending on the variance of the oracle and the stepsize. One can diminish the variance by considering mini-batches: if the variance of a single stochastic gradient is , considering a mini-batch of gradients reduces the variance of the corresponding oracle to . To decrease the additional term, one may also decrease the stepsizes over the iterations. For example, by choosing a decreasing stepsize like , the convergence rate is then of the order . The stepsize can also be selected as a constant that decreases the average objective for the first iterations and is reduced by a multiplicative factor at regular intervals like for to handle iterations between . Alternative stepsize schedules such as a cosine decay [122] have recently become popular.
关于随机优化的其他方案的文献仍在迅速发展,新的启发式方法不断被提出。下面我们介绍两种流行的方法。The literature on alternative optimization schemes for stochastic optimization is still rapidly evolving, with new heuristics regularly proposed. We present below two popular techniques.
16.2.3 动量变体Momentum variants
确定性设定下发展出的加速优化算法,可以推广到随机设定。例如,将重球法适配到随机设定,便得到带动量的随机梯度下降 [191],其通常实现为Accelerated optimization algorithms developed in the deterministic setting may be extended to the stochastic setting. For example, the heavy-ball method can be adapted to the stochastic setting, leading to stochastic gradient descent with momentum [191] generally implemented as
如前所述,可以对动量方法加以修改,以处理非二次的光滑强凸函数。这在确定性设定下引出了 Nesterov 加速方法;该方法已被适配到随机设定,并采用所谓的 Nesterov 动量 [191]As mentioned earlier the momentum method can be modified to handle non-quadratic smooth strongly convex functions. This leads to Nesterov’s accelerated method in the deterministic setting. This has been adapted to the stochastic setting with a so-called Nesterov momentum [191]
16.2.4 自适应变体Adaptive variants
在任何类梯度下降算法中,步长的选取都是获得良好性能的关键。若函数光滑,可以使用常数步长,但我们可能事先并不知道目标函数的光滑性常数,这意味着可能需要额外的过程来适当地选取步长。在确定性情形下,可以使用诸如 Armijo 或 Wolfe 准则 [211] 之类的线搜索,在每次迭代中检验所选步长是否使目标函数充分下降。此类准则已被调整以适应随机设定 [200]。In any gradient descent-like algorithm, selecting the stepsize is key for good performance. While a constant stepsize may be used if the function is smooth, we may not know in advance the smoothness constant of the objective, which means that additional procedures may be required to select appropriately the stepsize. In the deterministic case, line-searches such as the Armijo or Wolfe’s rules [211] can be used to check whether the selected stepsize sufficiently decreases the objective at each iteration. Such rules have been adapted in the stochastic setting [200].
降低算法对步长敏感性的另一条途径,是估计梯度的一阶矩与二阶矩,并将后者用作一种预条件,以平滑迭代值的轨迹。这引出了流行的 Adam 优化器 [106],其形式为Another way to decrease the sensitivity of the algorithm with respect to the stepsize has been to estimate first- and second-order moments of the gradients and use the latter as a form of preconditioning to smooth the trajectory of the iterates. This led to the popular Adam optimizer [106]. It takes the form,
其中 , 表示 的逐元素平方, 则是该算法的超参数。该算法变体众多,例如可在迭代过程中改变上式中的步长 。where , denotes the element-wise square of and are hyper-parameters of the algorithm. Numerous variants exist, such as varying the stepsize above along the iterations.
16.3 投影梯度下降16.3 Projected gradient descent
我们常常希望求解带有变量约束的极小化问题,其形式为Oftentimes, we seek to find the solution of a minimization problem subject to constraints on the variables, of the form
| (16.3) |
其中 为约束集。若 满足 ,则称其为式 16.3 的一个可行近似解。自然地,约束情形下的算法设计如今不仅取决于关于 的信息,还取决于关于 的信息。where is a set of constraints. We say that an approximate solution to Eq. 16.3 is feasible if . Naturally, the design of algorithms for the constrained setting now depends, not only on information about , but also on information about .
与 类似,关于 也可以考虑不同的 oracle。其中最常用的 oracle 之一是欧几里得投影Similarly to , different oracles can be considered about . One of the most commonly used oracles is the Euclidean projection
定义 16.3.1(欧几里得投影)。Definition 16.3.1 (Euclidean projection).
当 为凸集时,该投影是良定义的,可用于投影梯度下降;下面我们简要回顾这一算法。通常,在某个特定集合 上的投影需要专门的算法来计算。This projection, which is well-defined when is a convex set, can be used in projected gradient descent, that we briefly review below. Typically, the projection on a particular set requires a dedicated algorithm to compute it.
其他可用的 oracle 还有用于 Frank-Wolfe 算法的线性极大化 oracle(LMO),以及用于镜像下降算法的 Bregman 投影 oracle。具体选用哪种算法,可取决于关于 能获得何种 oracle。Other possible oracles are linear maximization oracles (LMO) used in Frank-Wolfe algorithms and Bregman projection oracles, used in mirror descent algorithms. The algorithm choice can be dictated by what oracle about is available.
16.3.1 变分视角Variational perspective
投影梯度下降是基于欧几里得投影 oracle 对梯度下降的自然推广。其迭代值写为Projected gradient descent is a natural generalization of gradient descent, based on the Euclidean projection oracle. Its iterates read
在每次迭代中,我们尝试沿负梯度方向移动以降低目标函数值,同时借助投影步骤确保下一个迭代值仍然可行。At each iteration, we attempt to decrease the objective by moving along the negative gradient direction, while ensuring that the next iterate remains feasible, thanks to the projection step.
与式 16.2 中梯度下降的变分视角类似,投影梯度下降的更新等价于Similarly to the variational perspective of gradient descent in Eq. 16.2, the projected gradient descent update is equivalent to
这表明,投影梯度下降最小化的是这样一种权衡:既要接近 ,又要最小化 在 附近的线性化,同时保持在 中。This shows that projected gradient descent minimizes a trade-off between staying close to and minimizing the linearization of around , while staying in .
就收敛速率而言,它们与梯度下降保持一致 [146]。例如,对于光滑凸函数,投影梯度下降仍以 的速率收敛。In terms of convergence rates, they remain the same as gradient descent [146]. For example, projected gradient descent on a smooth convex function still converges at a rate .
朴素投影梯度下降有许多扩展。与梯度下降类似,步长可以通过线搜索技术自动调整,并且存在加速变体。若将 替换为随机梯度 ,就得到随机投影梯度下降。There are numerous extensions of vanilla projected gradient descent. Similarly to gradient descent, the stepsize can be automatically adjusted using linesearch techniques and there exists accelerated variants. If we replace with a stochastic gradient , we obtain a stochastic projected gradient descent.
16.3.2 最优性条件Optimality conditions
在无约束情形下,极小值点的梯度必然为零。在约束设定下,可能不存在梯度为零的可行参数。此时,一个点的最优性由如下事实刻画:在该点沿梯度移动且保持在约束内时,找不到更好的解。形式上,这意味着对任意 , 在 上的极小值点 满足In the unconstrained case, a minimum necessarily has a zero gradient. In the constrained setting, there may not be any feasible parameters with zero gradient. Instead, the optimality of a point is characterized by the fact that no better solution can be found by moving along the gradient at that point, while staying in the constraints. Formally, it means that for any , a minimizer of on satisfies
可以证明,该条件等价于 [146]It can be shown that this condition is equivalent [146] to
16.3.3 常用投影Commonly used projections
下面我们简要回顾几个有用的欧几里得投影。We now briefly review a few useful Euclidean projections.
- •
若 ,显然有If , we obviously have
因此,在无约束设定下,投影梯度下降确实退化为梯度下降。Therefore, in the unconstrained setting, projected gradient descent indeed recovers gradient descent.
- •
若 (盒约束),则有If (box constraints), we have
其中 与 是按坐标逐一施加的。where the and are applied coordinate-wise.
- •
作为上述情形的特例,若 (非负象限),As a special case of the above, if (non-negative orthant),
这也称为非负部分或 ReLU。also known as non-negative part or ReLU.
- •
若 (单位概率单纯形),If (unit probability simplex),
其中 是一个常数,用来确保 归一化为 。已知可通过一次排序在 时间内求出 。利用类似寻找中位数的算法,可将其改进为 。where is a constant ensuring that normalizes to . It is known that can be found in using a sort. This can be improved to using a median-finding like algorithm.
16.4 邻近梯度法16.4 Proximal gradient method
通过将分析推广到取无穷值的函数,约束设定(其中 为凸集)可以重新表述为无约束优化。我们把集合 的指示函数记为The constrained setting (with a convex set) can be recast as unconstrained optimization, by extending our analysis to functions taking infinite values. Let us denote the indicator function of the set by
显然,式 16.3 中的约束问题随后可以改写为Clearly, the constrained problem in Eq. 16.3 can then be rewritten as
这表明,约束优化是如下形式的复合目标函数的一个特例This suggests that constrained optimization is a special case of composite objectives of the form
其中 是凸函数,但未必可微。我们假定可以访问与 相关联的一个 oracle,即邻近算子。where is a convex but potentially non-differentiable function. We assume that we have access to an oracle associated with called the proximal operator.
定义 16.4.1(邻近算子)。Definition 16.4.1 (Proximal operator).
由此引出下文将要回顾的邻近梯度法。This leads to the proximal gradient method, reviewed below.
16.4.1 变分视角Variational perspective
在该方法中,更新式为With this method, the update reads
这一更新同样具有直观的变分解释,即This update again enjoys an intuitive variational perspective, namely,
也就是说,我们把 在 附近线性化,而保持 不变。That is, we linearize around , but keep as is.
当目标函数含有促稀疏的正则化项 时,邻近梯度法尤为常用。例如,LASSO [195] 旨在由观测 预测目标值 ,此时我们取 、,其中 控制正则化强度。这时, 正是所谓的软阈值算子(见下文)。The proximal gradient method is popularly used when the objective function contains a sparsity-inducing regularizer . For example, for the LASSO [195], which aims at predicting targets from observations , we set and , where controls the regularization strength. In this case, is the so-called soft-thresholding operator (see below).
邻近梯度法的收敛性保证与梯度下降相同,例如对光滑凸函数可达到 的速率。Convergence guarantees of the proximal gradient method remain the same as for gradient descent, such as a rate for smooth convex functions.
16.4.2 最优性条件Optimality conditions
该问题的最优解由如下不动点方程刻画:An optimal solution of the problem is characterized by the fixed point equation
对一切 成立 [146]。换言之,邻近梯度法(梯度下降与投影梯度下降均为其特例)可视为不动点迭代方案。这一视角提示我们可采用不动点文献中的加速方法,例如 Anderson 加速 [157];在设计第 8 章所述的隐式微分方案时,这一视角同样有用。for all [146]. In other words, the proximal gradient method (which includes gradient descent and projected gradient descent as special cases), can be seen as fixed point iteration schemes. Such a viewpoint suggests using acceleration methods from the fixed point literature such as Anderson acceleration [157]. It is also useful when designing implicit differentiation schemes as presented in Chapter 8.
16.4.3 常用的邻近算子Commonly-used proximal operators
下面简要回顾几个有用的邻近算子。We now briefly review a few useful proximal operators.
- •
若 ,则If , we have
因此,采用这一邻近算子时,邻近梯度法即退化为梯度下降。Therefore, with this proximal operator, the proximal gradient method recovers gradient descent.
- •
若 ,则If , we have
因此,采用这一邻近算子时,邻近梯度法即恢复为投影梯度下降。Therefore, with this proximal operator, the proximal gradient method recovers projected gradient descent.
- •
若 ,则If , we have
其中各运算均按坐标逐一进行。这就是所谓的软阈值算子。where the operations are applied coordinate-wise. This is the so-called soft-thresholding operator.
- •
若 ,其中 是 的一个划分, 表示限制在 上的子向量,则有 where is a partition of and denotes the subvector restricted to , then we have
该算子用于 group lasso [213],可用来促使组稀疏。which is used in the group lasso [213] and can be used to encourage group sparsity.
关于更多邻近算子的综述,可参见例如 [7, 150]。For a review of more proximal operators, see for instance [7, 150].
16.5 小结16.5 Summary
- •
从变分视角看,梯度下降就是将目标函数线性化并引入二次正则化项后所得的算法。From a variational perspective, gradient descent is the algorithm obtained when linearizing the objective function and using a quadratic regularization term.
- •
投影梯度下降则是在存在额外约束时所得的算法(由于二次正则化项,欧几里得投影自然出现)。Projected gradient descent is the algorithm obtained when there is an additional constraint (the Euclidean projection naturally appearing, due to the quadratic regularization term).
- •
当目标函数由一个可微函数与一个不可微函数相加而成时,邻近梯度法正是将可微函数线性化、同时保持不可微函数不变所得的算法。When the objective is the sum of a differentiable function and a non-differentiable function, proximal gradient is the algorithm obtained when the differentiable function is linearized but the non-differentiable function is kept as is.
- •
我们还回顾了多种基于随机梯度的算法,包括朴素 SGD、带动量的 SGD 以及 Adam。We also reviewed various stochastic gradient based algorithms, including vanilla SGD, SGD with momentum and Adam.